Designing for Testability in Distributed Microservices
A system design interview guide to making a massively distributed microservices architecture testable — from the shape of the test suite to contract tests, hermetic environments, chaos engineering, and safely verifying in production.
Student edition · start with the guarantee
Make distributed logic reproducible in fast tests while recognizing what mocks and toy stores cannot prove.
Correctness contract: Tests state their oracle, model assumptions, controlled time/concurrency, and coverage limits. Production experiments are isolated, bounded, and authorized separately.
Basic HTTP, databases, and programming are assumed. Specialized terms are explained below. Named products motivate the problem; this is an educational design, not a claim about their current internals. Capacity numbers are illustrative decimal payload estimates, not benchmarks. Add indexes, protocol overhead, replicas, headroom, and failure capacity before provisioning.
In a monolith, testing is mostly a solved shape: unit tests underneath, a few end-to-end tests on top, one process to run. Break that monolith into hundreds of independently deployed services and testing becomes a distributed-systems problem in its own right. Any request now crosses a dozen network hops owned by a dozen teams; a full end-to-end environment is expensive, slow, and perpetually broken; and the interesting failures are no longer logic bugs but timeouts, retries, partial outages, and version skew between services that were tested in isolation. Testability stops being something you add at the end and becomes something you design for. This guide works through that design: the test pyramid rebalanced for microservices, consumer-driven contract tests that catch integration breaks without a shared environment, techniques for isolating dependencies, fault injection and chaos engineering for the failures that only appear under stress, and the discipline of verifying safely in production with canaries, shadow traffic, and probers. Observability is the connective tissue — see the companion Distributed Tracing guide for the request-level visibility these techniques lean on.
Intuition first
Think of testing a car. You test each part on a bench first (unit tests). You check that the parts bolt together the way both sides agreed (contract tests). You test drive the car a few times (end-to-end tests). Last, you watch real cars on real roads (testing in production). Most bugs should be caught on the bench, because bench tests are fast, cheap and give the same answer every time.
Each definition includes a concrete example and the condition under which the mechanism is useful. You can read this guide without opening another guide.
Dependency injection and test doubles
Pass clocks, stores, and clients into logic instead of constructing them internally. Fakes execute a lightweight model, stubs return preset answers, and mocks verify interactions. A hermetic test controls its inputs and external dependencies.
Example. A fake clock advances a rate-limiter test by 60 seconds instantly, without sleep or wall-clock flakiness.
Limit. An in-memory fake does not prove production SQL isolation, crash durability, or network behavior. Pair fast unit tests with provider contracts and targeted integration/fault tests.
Optimistic concurrency and compare-and-set
Update state only if the expected version or status still matches, in the same atomic operation that changes it. A failed comparison means a conflicting operation won; reread or return a conflict.
Example. UPDATE seats SET status='held', version=version+1 WHERE id=? AND status='available' allows only one concurrent claimant to update the row.
Limit. Application-level GET then unconditional SET is not equivalent. Include acquisition identity to reject stale callbacks, and couple related invariants in a transaction.
Wall and monotonic clocks
A wall clock maps to civil/epoch time and can jump because of correction. A monotonic clock measures elapsed time locally without wall-clock jumps, but its origin is not a shared global epoch.
Example. Use an epoch timestamp to label an event and a monotonic deadline to bound how long a process waits for the next usable timestamp.
Limit. Neither establishes causal order across machines. Monotonic readings cannot be compared between hosts or assumed to survive reboot with the same origin.
Canaries, shadow traffic, and rollout gates
A canary sends a small real traffic cohort to a new version and compares user-relevant signals with a control. Shadow traffic executes copied inputs but isolates its effects; rollout gates stop promotion when evidence is inadequate or harmful.
Example. Release 1%, then 5%, then 25%, checking error rates, latency, queue lag, and correctness with sufficient observations per cohort.
Limit. No universal sample fraction or dwell time proves safety. Rare failures need enough samples; cohorts must be comparable. Rollback cannot automatically undo emitted events or incompatible data writes.
SLIs, SLOs, and error budgets
An SLI measures a user-relevant outcome; an SLO sets its target over a window. For a success-ratio SLO, the allowed bad fraction is 1−SLO. An SLA is a contractual commitment that may use different definitions.
Example. 99.9% successful requests over 1 billion requests allows 1 million bad requests. A time-based 30-day availability target instead allows 43.2 unavailable minutes.
Limit. Request and time budgets are not interchangeable under variable traffic or partial failure. SLOs are not universally stricter than SLAs; choose both from their definitions and user needs.
Idempotency keys
A client-generated identity for one logical operation. The server binds it to caller scope, endpoint, request fingerprint, state, and result. A retry uses the same key and reuses the original outcome rather than repeating the effect.
Example. Payment p42 times out after the provider charged it. Retrying with p42 lets the provider return the same charge instead of creating a new one.
Limit. A unique local claim is insufficient if the business effect and saved result can diverge. Keep unknown outcomes pending, use downstream idempotency, and state the retention/retry horizon.
1. Requirements & Scope
“Design for testability” is open-ended, so the first move is to state what testability actually has to deliver in a distributed system, and where the hard parts are.
Fast, reliable feedback. A developer changing one service must get a trustworthy signal in minutes, without spinning up the whole fleet. Slow or flaky feedback is the disease that kills testing cultures.
Independent deployability. Each service must be testable and releasable on its own. A test strategy that requires all services to be in lockstep defeats the point of microservices.
Integration safety without a full environment. We must catch breaking changes at service boundaries before deploy, without relying on a fragile, shared end-to-end environment as the only gate.
Resilience verification. The dominant failures are partial — a slow dependency, a dropped call, a bad node. The system must be testable against those, not just against clean logic.
Confidence in production. No pre-prod environment fully mirrors production scale and traffic, so verifying safely in production must be a first-class, designed capability — not a euphemism for “we don’t test.”
Non-goals. This is about testability as an architectural property, not a tutorial on any one framework.
Questions to ask first
How many services and teams? Does each team deploy on its own schedule?
How are services wired: synchronous RPC, events on a queue, or both?
What breaks most often today: logic bugs, integration breaks, or failures under load?
Is there a shared staging environment, and how reliable is it?
How long may a pre-merge test run take before developers stop waiting for it?
2. The Test Pyramid, Rebalanced
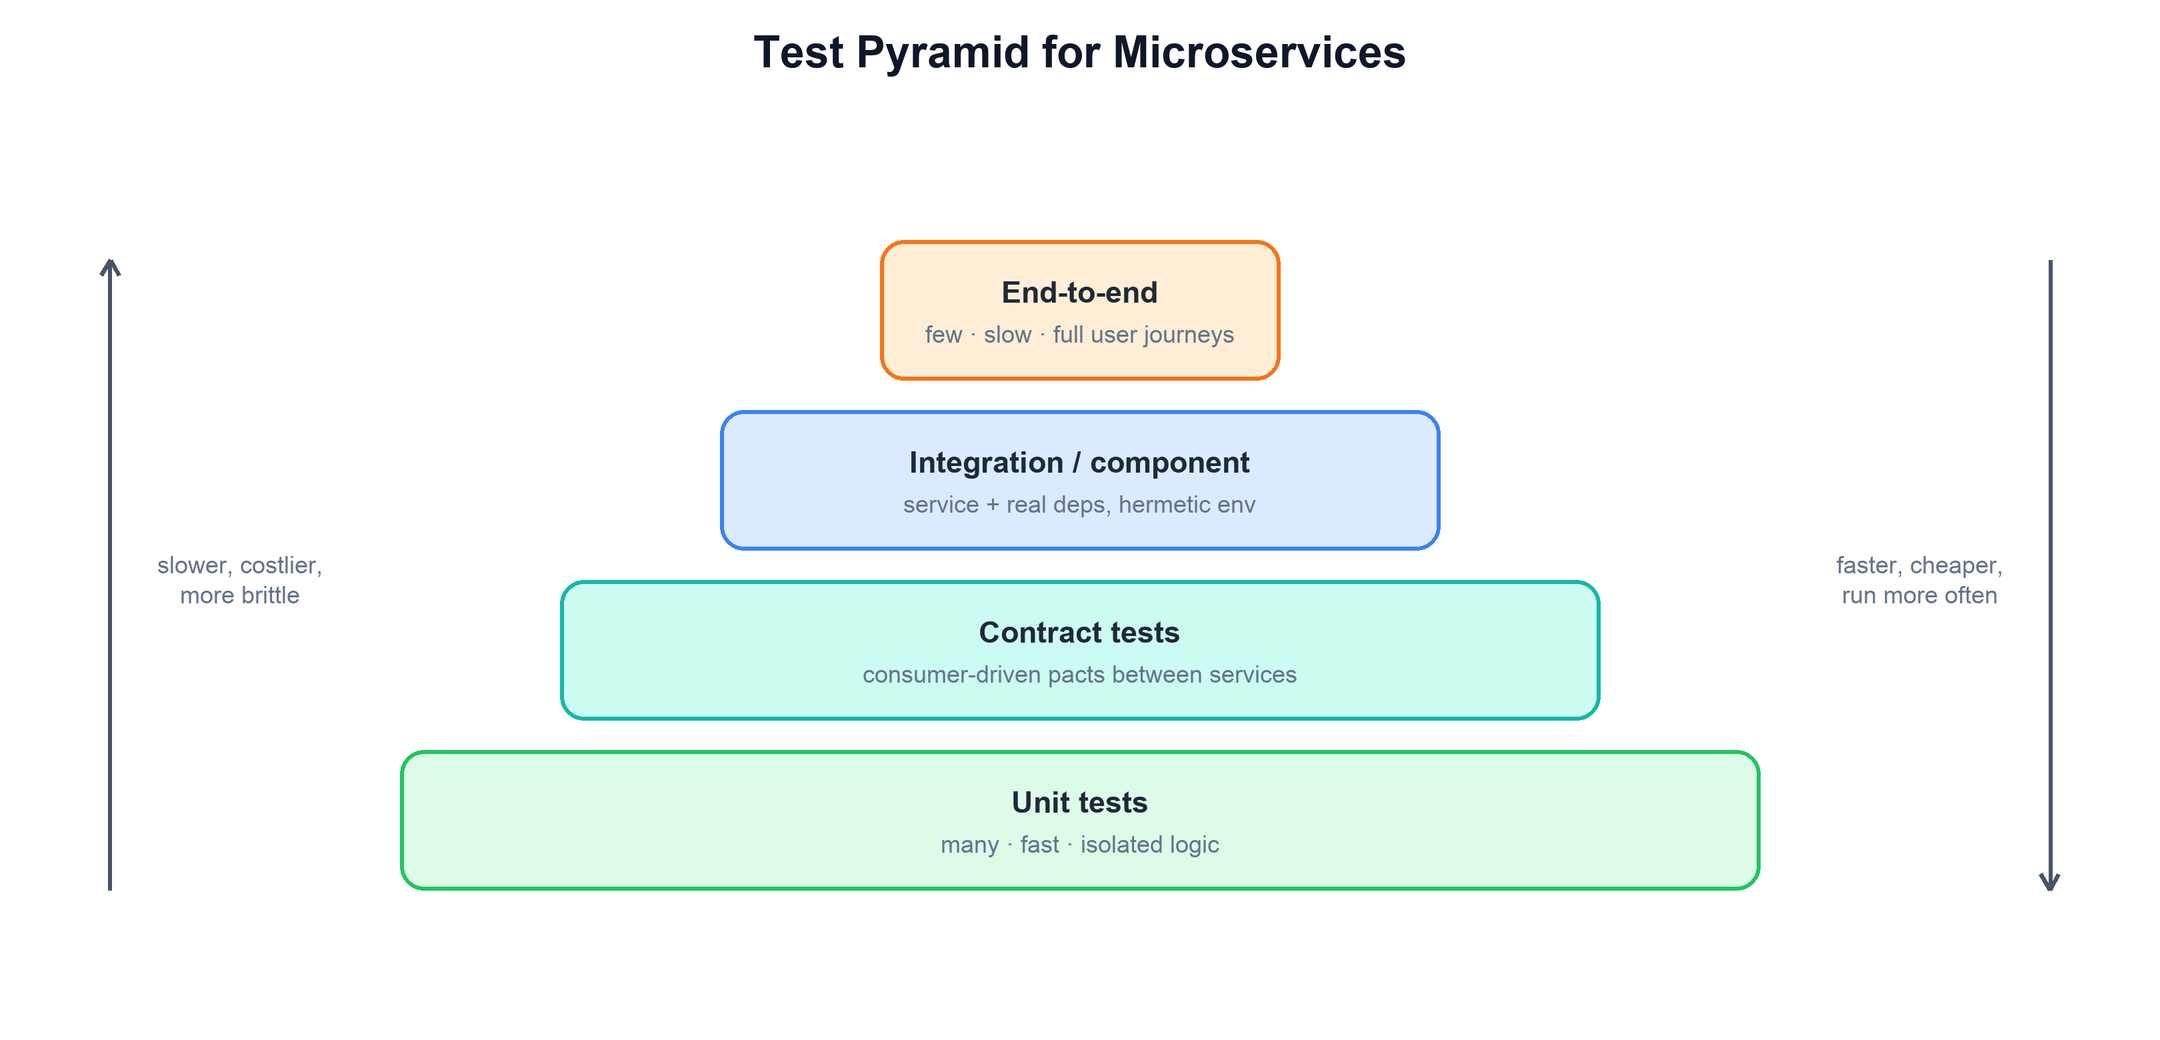
The classic test pyramid still holds, but microservices reshape it. The instinct to lean on end-to-end tests — “just run the whole thing and click through it” — is exactly wrong at scale: those tests are slow, brittle, and flaky because any of a hundred services can knock them over. The winning shape keeps the base wide and fast and adds a distinctly distributed layer — contract tests — to cover the seams between services without a shared environment.
The microservices test pyramid. A wide base of fast unit tests, a distinctive contract-test layer that pins down inter-service APIs, a thinner band of integration/component tests in hermetic environments, and a deliberately narrow tip of slow, brittle end-to-end tests.
Layer
Scope
Speed & count
Unit
One function/class, no I/O.
Milliseconds; thousands. The bulk of coverage.
Contract
The API between a consumer and a provider.
Fast; one per integration. Replaces most cross-service E2E.
Integration / component
One service with its real adjacent deps (DB, cache) in a hermetic env.
Seconds; dozens per service.
End-to-end
A full user journey across many services.
Minutes; a handful of critical paths only.
The key inversion versus the naive approach: push coverage down. Every bug you can catch with a unit or contract test is a bug you did not need a flaky end-to-end run to find. Reserve end-to-end tests for a few golden critical paths (sign-up, checkout) and accept that everything else is covered by cheaper, more reliable layers.
Worked example: why flakiness and E2E tests do not scale
Small per-test failure rates multiply across a suite, just like availabilities multiply along a request path.
Situation
Math
Result
500 tests, each flaky 0.1% of runs
0.999500
60.6% green
Same flake rate, 2,000 tests
0.9992000
13.5% green
500 tests, each failing test retried once (hides real flakes)
(1 − 0.001²)500
99.95% green
One E2E journey through 10 services, each up 99% in staging
0.9910
90.4% pass
This is why the pyramid pushes coverage down. A unit test has no network and no shared state, so its flake rate can be close to zero. An E2E test inherits the flakiness of every service it touches. Retries make the suite green, but they hide the problem, so track and fix flaky tests instead of silently retrying them forever.
3. Contract Testing
Consumer-driven contracts record the requests and responses a consumer depends on; provider verification checks them against the real provider implementation with controlled provider state. A broker shares versioned contracts and verification results for deployment compatibility gates.
Contracts can include behavior/examples, not just JSON shape, but do not exhaustively prove semantics, performance, concurrency, authorization, or every input. Providers may need local real dependencies/test state; 'no integration environment' does not mean no integration verification. Complement contracts with service tests and a small number of critical end-to-end journeys.
4. Isolating Dependencies
To test one service without dragging in the other ninety-nine, you have to stand in for its dependencies. The trick is choosing the right kind of stand-in for the level of the pyramid — too shallow and the test proves nothing, too heavy and it becomes a slow, flaky end-to-end test in disguise.
Mocks. Assert on how a collaborator is called (this method, these args). Cheap and precise for unit tests, but over-mocking couples the test to implementation and can pass while reality diverges — the failure contract testing exists to catch.
Fakes. Lightweight working implementations — an in-memory database, a fake queue. They behave correctly enough to test real logic without the real dependency’s cost, and are the workhorse of integration tests.
Stubs. Stand-ins that return canned answers (“for user 42, return this JSON”) with no real logic. Unlike a mock, a stub does not check how it was called; it just feeds the code under test. Service virtualization is a stub at the network level: a fake HTTP or gRPC endpoint (for example WireMock) that returns programmed responses and can be told to add latency or errors. Useful for third-party APIs you cannot run locally or want deterministic control over.
Hermetic environments. A fully self-contained, reproducible environment — the service plus its real adjacent dependencies (its own database, cache) spun up in containers, seeded deterministically, with no shared mutable state and no network to the outside. Hermeticity is what makes a test give the same answer every run on every machine; it is the antidote to “works on my laptop” and shared-staging contention.
The design principle behind all of these is dependency injection: a service should receive its collaborators (clients, clocks, config) from outside rather than constructing them internally. Code written that way can be handed a fake or a stub in a test and the real thing in production without changing a line — testability is largely a consequence of this one design choice.
Runnable example: injecting a clock
A rate limiter that calls time.monotonic() directly would need a real 61-second sleep to test its window. Injecting the clock lets a test move time forward instantly and makes the result the same on every run.
import time

class RateLimiter:
    """Allows `limit` calls per `window` seconds. The clock is injected."""
    def __init__(self, limit, window, clock=time.monotonic):
        self.limit, self.window, self.clock = limit, window, clock
        self.calls = []

    def allow(self):
        now = self.clock()
        self.calls = [t for t in self.calls if now - t < self.window]
        if len(self.calls) < self.limit:
            self.calls.append(now)
            return True
        return False

class FakeClock:                      # a fake: tiny but real behaviour
    def __init__(self): self.t = 0.0
    def __call__(self): return self.t
    def advance(self, s): self.t += s

clock = FakeClock()
rl = RateLimiter(limit=2, window=60, clock=clock)
assert rl.allow() and rl.allow()
assert not rl.allow()                 # third call in the window is refused
clock.advance(61)                     # no sleep(61): the test runs instantly
assert rl.allow()
print("rate limiter tests pass")

# why flaky tests hurt: chance a whole suite is green
for n in (500, 2000):
    print(n, "tests at 0.1% flake each ->", f"{0.999 ** n:.1%} green")
Common mistake: mocking everything
If every collaborator is a mock that asserts exact calls, the test breaks whenever the code is refactored, and it still passes when the real dependency changes its behaviour. Prefer fakes for things you own (an in-memory store), contract tests for other teams’ services, and mocks only where the call itself is the behaviour you care about (“an email was sent”).
5. Fault Injection & Chaos Engineering
Unit and contract tests verify correct behavior on the happy path. But in a distributed system the failures that cause outages are the unhappy ones — a dependency that got slow, a call that timed out, a region that vanished — and those are precisely the paths that never run in a normal test. Fault injection deliberately provokes them; chaos engineering does it as a disciplined, ongoing experiment.
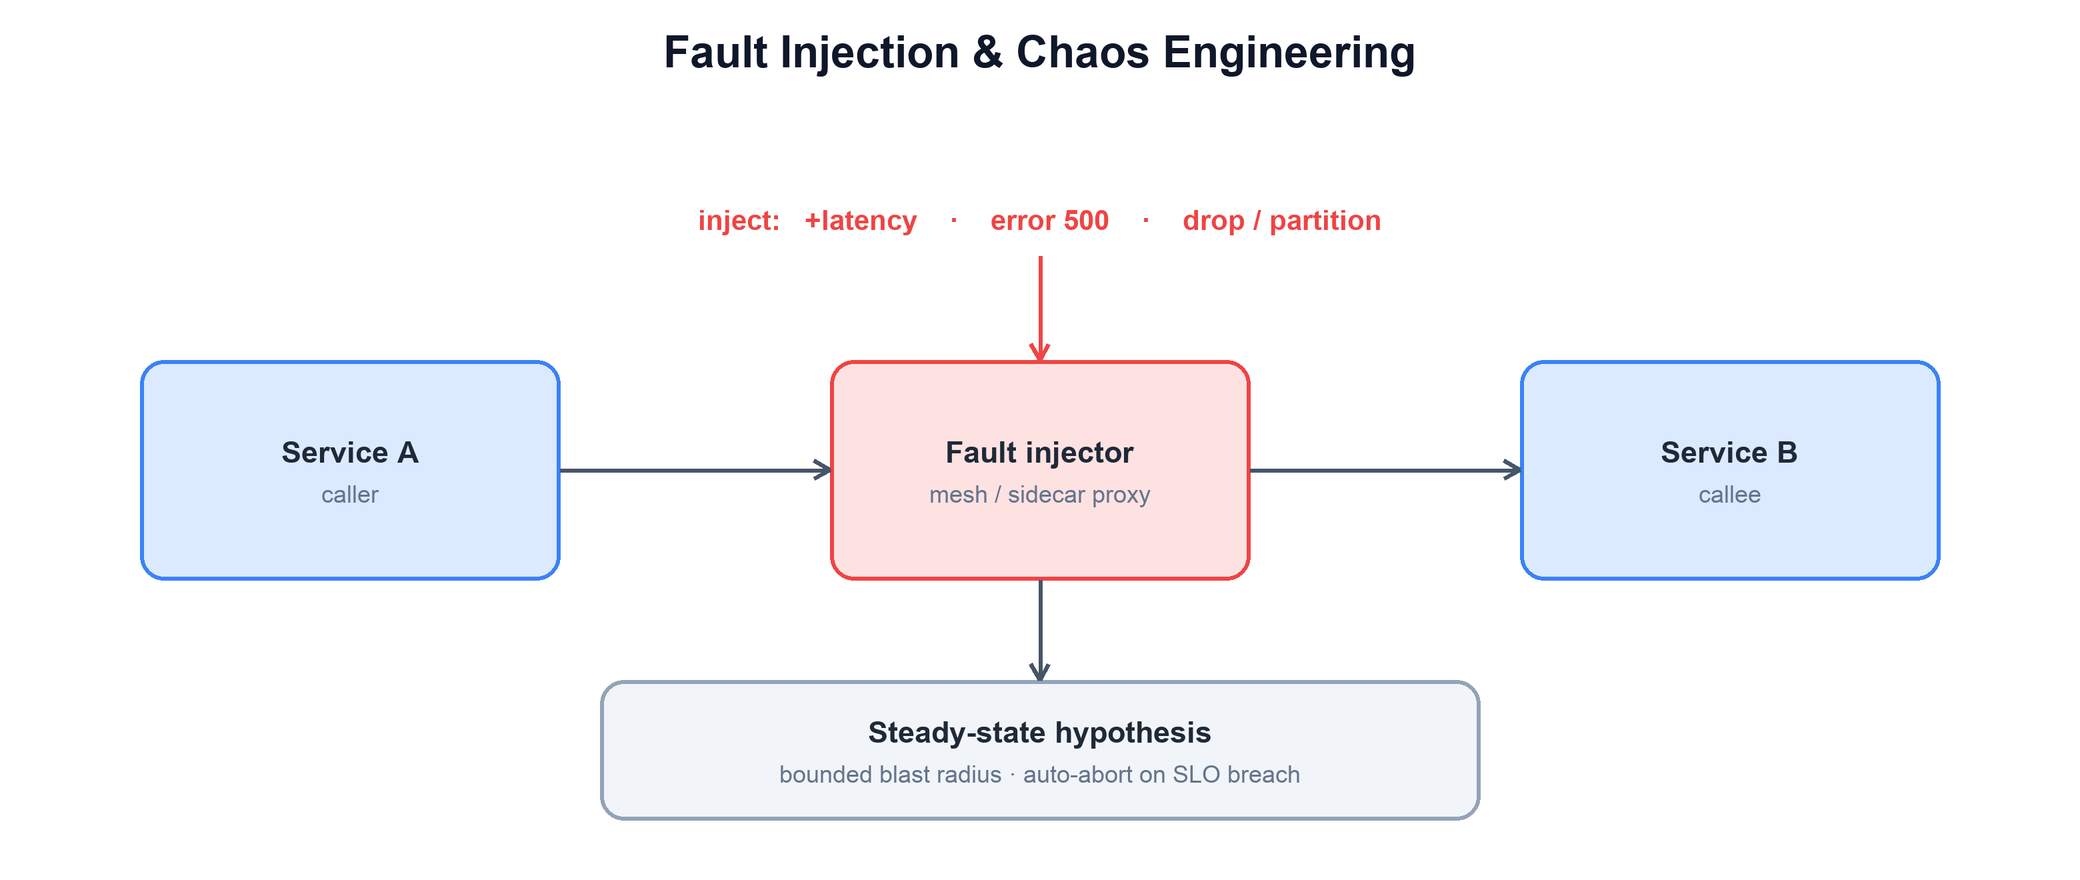
Fault injection sits in the call path — commonly a service-mesh sidecar — and can add latency, return errors, or drop/partition calls between services. A chaos experiment frames this as a steady-state hypothesis with a bounded blast radius and automatic abort if an SLO is breached.
What you inject. Added latency (does the caller’s timeout and retry behave?), error responses (does the circuit breaker trip and the fallback engage?), and dropped or partitioned calls (does the system degrade gracefully or cascade?). A service mesh makes these injectable without touching application code.
Chaos engineering discipline. Define the normal steady state as a measurable SLO, form a hypothesis (“killing one replica will not move p99”), inject the fault, and compare. The value is in disproving the comforting assumption that a fault is handled when it is not.
Blast radius & safety. Start in a hermetic or staging environment, then run controlled experiments in production on a small slice of traffic, with an automatic abort (a “big red button”) the moment real user impact appears. Chaos without a bounded blast radius is just an outage.
Game days. Scheduled, human-in-the-loop drills of larger failures (lose a zone, fail over a database) that test the people and runbooks as much as the code.
6. Testing in Production
No staging environment matches production’s scale, data shape, or traffic mix, so some classes of bug are only discoverable in production. The mature stance is not to avoid production but to make testing there safe by design, decoupling deploy from release and always keeping a fast path back.
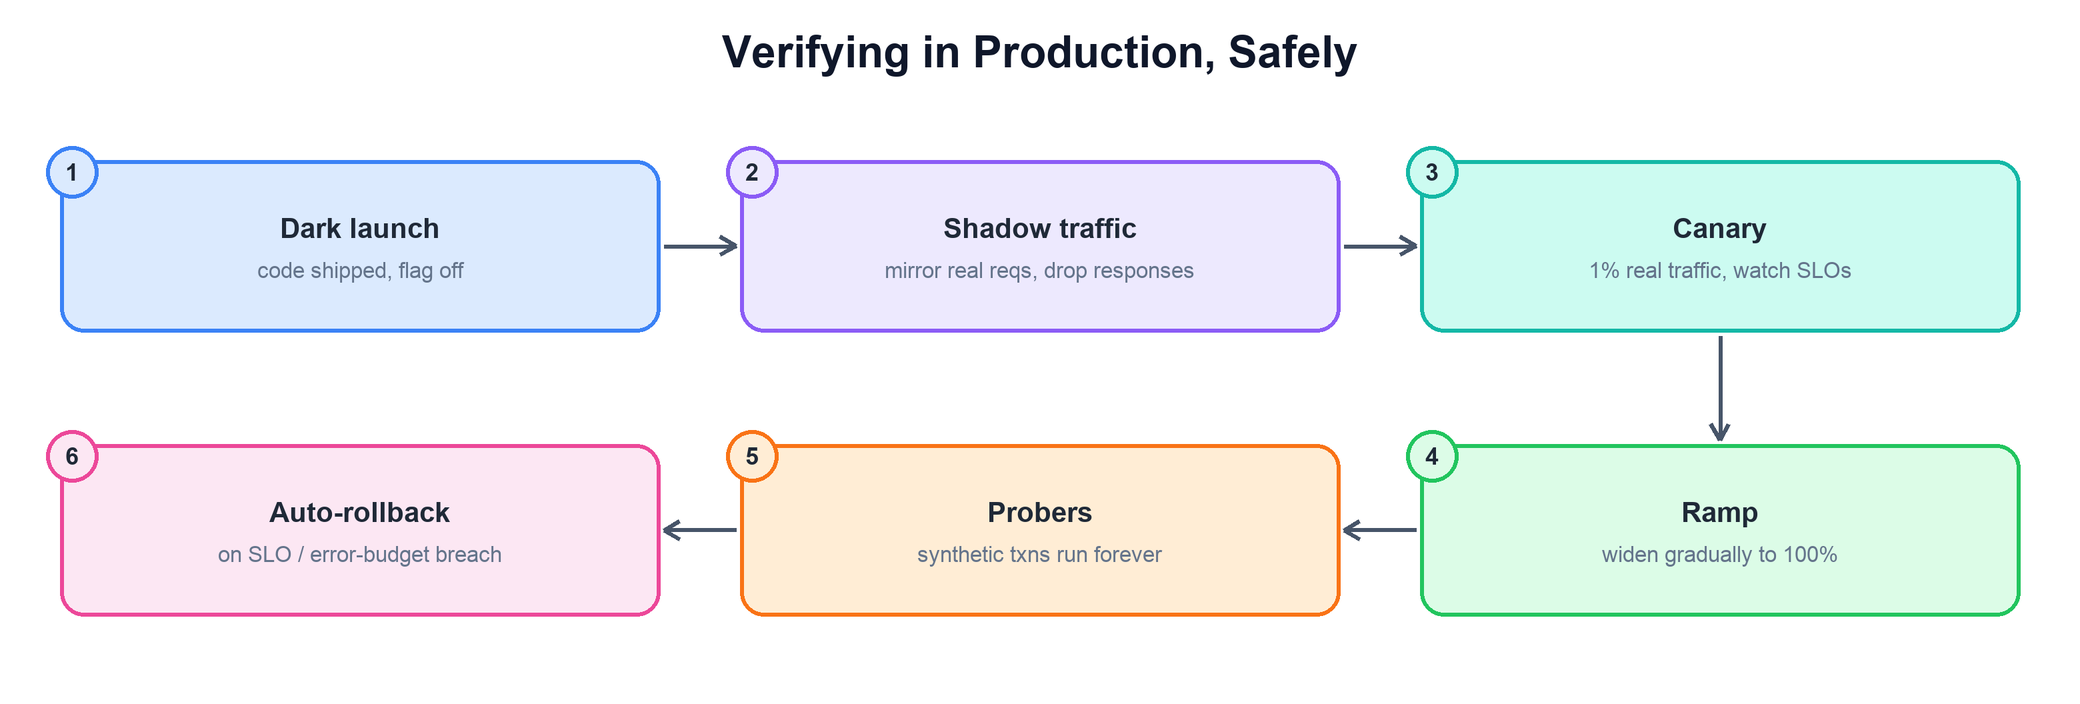
Verifying in production safely: ship dark behind a flag, mirror real traffic in shadow, release to a 1% canary watched against SLOs, ramp gradually, run synthetic probers continuously, and roll back automatically on any SLO or error-budget breach.
Dark launch / feature flags. Deploy the code turned off, then enable it for internal users or a fraction of traffic via a flag. Deploy and release become separate events, so a bad feature is switched off instantly without a redeploy.
Shadow traffic (mirroring). Copy real production requests to the new version and discard its responses. The new code sees real load and real data shapes with zero user impact — ideal for validating a rewrite or a performance change before it serves anyone. The catch is side effects: a mirrored “charge card” or “send email” request must not really run twice. Mirror only reads, or point the shadow at sandboxed downstreams and make its writes go nowhere real.
Canary release. Route a small slice (say 1%) of real traffic to the new version and compare its SLOs against the stable version. If error rate or latency regresses, roll back before the blast radius grows; if it holds, ramp gradually to 100%.
Synthetic transactions / probers. Scripted “fake users” that continuously exercise critical journeys against production and alert on failure. They catch breakage the moment it appears — often before a real user hits it — and double as the health signal that gates canaries and drives auto-rollback.
Observability as the oracle. All of this depends on being able to tell good from bad in production. Distributed tracing ties a request’s path across services into one timeline, making it the primary tool for diagnosing why a canary regressed — see the Distributed Tracing guide.
7. Determinism, Data & Load
Control clocks, RNG, fixtures, network, and scheduling where possible. Hermetic environments remove shared external state but do not automatically eliminate internal races or nondeterministic order. Fakes model behavior only to their declared fidelity; test production isolation/durability separately.
A flaky test needs an owner and diagnosis. Quarantine can unblock work temporarily but must not hide a critical uncovered invariant; keep visible failures and a repair deadline. If independent tests each flake with probability 0.001, a suite of n is green with probability 0.999^n. Correlated flakes change that calculation.
Load and soak tests measure sustained queues, memory, connections, storage, and user outcomes, not merely a short peak. Production snapshots need effective minimization/access controls; hashed identifiers alone do not guarantee anonymization. Shadow traffic must isolate writes and resource/privacy impact before claiming safety.
8. Bottlenecks & Tradeoffs
Testability is a balance of confidence against cost and speed; the tensions are real and worth naming.
Confidence vs speed. End-to-end tests give the most realistic confidence but are the slowest and flakiest; unit tests are fast but miss integration bugs. Resolve it by shape, not by picking one — wide base, narrow tip, contract tests for the seams.
Realism vs isolation. Real dependencies catch real bugs but make tests slow and non-deterministic; mocks and fakes are fast but can drift from reality. Contract tests are the bridge that keeps fakes honest.
Test coverage vs maintenance. More tests catch more bugs but cost more to maintain and slow the pipeline; over-mocked tests especially rot. Aim coverage at behavior and boundaries, not at line counts.
Safety vs realism in production testing. Testing in production gives ultimate realism but risks user impact; shrinking the blast radius (canary %, shadow, flags, auto-rollback) trades a little realism for a lot of safety.
Staging cost vs value. A full staging fleet is expensive and perpetually drifting from production; hermetic per-test environments plus production verification often beat a heavyweight shared staging environment.
Worked example: a window expires without sleeping
The limiter allows two admissions in any trailing 60 seconds.
Read top to bottom. The table below explains the state and guarantee at each step.
Step
State, calculation, and reasoning
1. Inject a controlled clock
Start t=0. Two calls pass; a third is rejected.
2. Advance to t=59
Nothing expires yet, so the next call is rejected. The test runs instantly.
3. Advance to t=60
Under the model's half-open rule (now−60,now], t=0 calls expire. Two new admissions are allowed.
4. Test the production boundary separately
This single-threaded model does not prove Redis atomicity, database isolation, crash durability, or provider idempotency. Integration/fault tests cover those contracts.
Check your understanding: Does a hermetic test prove deterministic production behavior?
No. It controls a test's environment; scheduling, production dependencies, and faults still require targeted evidence. Deterministic simulation is one layer of confidence.
Run a small, testable model
Download concepts.py. It uses only the Python 3.10+ standard library. From the directory where you saved it, run:
python3 concepts.py testing
python3 concepts.py test
The fake-clock model checks exact boundary behavior and invalid clock movement with no real sleep.
The program contains deterministic assertions and failure traces. It is a learning model, not a production service: it does not implement network consensus, distributed durability, authentication, or third-party delivery. Read its contracts and try changing an input before extending it.
Fault injection through the mesh, chaos with a steady-state hypothesis and an abort button, game days.
38–45
Production and tradeoffs
Shadow (reads only), canary, probers, auto-rollback; speed vs confidence, realism vs safety.
10. Common Mistakes
Mistake
Why it hurts
Do this instead
An “ice-cream cone”: mostly E2E and manual tests
Slow, flaky, hard to debug
Push coverage down to unit and contract tests
One shared staging for every team
Constant contention and breakage; nobody trusts it
Hermetic per-test environments plus contracts
Real clocks, sleeps and random seeds in tests
Timing-based flakiness
Inject clocks and seeds; wait on conditions, not sleeps
Auto-retrying flaky tests forever
Hides real races and bugs
Quarantine, file a ticket with an owner, fix
Shadowing write traffic to real systems
Double charges, duplicate emails
Mirror reads, or sandbox all side effects
Chaos experiments without an abort
A test becomes an outage
Small blast radius, SLO-based automatic stop
11. Summary
Testability in distributed microservices is an architectural property, not a phase. The design pushes fast feedback down, covers the seams without a shared environment, provokes the failures that matter, and treats safe production verification as part of the plan.
Concern
Mechanism
What shape should the suite take?
Rebalanced pyramid: wide unit base, contract layer for seams, narrow E2E tip.
How to catch integration breaks early?
Consumer-driven contract tests verified in each provider’s own pipeline.
How to test a service in isolation?
Dependency injection + fakes/stubs in a hermetic, deterministic environment.
How to verify resilience?
Fault injection (latency/error/partition) and disciplined chaos with bounded blast radius.
How to gain confidence at real scale?
Test in production safely: dark launch, shadow traffic, canary, probers, auto-rollback.
How to keep tests trustworthy?
Kill flakiness with isolation and injectable time; manage test data per run.
How to catch slow, scale-only failures?
Load tests for the ceiling, soak tests for leaks over time.
How to tell good from bad?
Observability — distributed tracing as the oracle for every layer.
The recurring theme: make fast feedback cheap and realistic feedback safe. Push testing down the pyramid, keep fakes honest with contracts, provoke real failures deliberately, and treat production as the final — carefully guarded — test environment, all resting on determinism and observability.
12. Check Yourself
What is the difference between a mock, a stub and a fake?
AnswerA stub returns canned answers. A mock also checks how it was called (which method, which arguments). A fake is a small working version, such as an in-memory database.
Who writes a consumer-driven contract, and who runs it?
AnswerThe consumer writes it from its own tests (the requests it sends and the parts of the response it uses). The provider runs it in its own CI, so a breaking change fails the provider’s build before deploy.
A suite of 1,000 tests has a 0.05% flake rate per test. How often is the whole suite green?
Answer0.99951000 ≈ 60.6%. About 4 runs in 10 fail for no code reason.
Why is shadow traffic dangerous for a payment service, and how do you make it safe?
AnswerMirrored requests would charge cards or send receipts a second time. Mirror only reads, or route the shadow to sandboxed downstreams and drop its writes.
What makes a test environment hermetic?
AnswerEverything it needs is inside it (its own DB, cache, fakes), seeded the same way every time, with no shared state and no calls to the outside network. So it gives the same answer on every run and every machine.
State a good chaos experiment hypothesis.
AnswerA measurable steady state plus a fault, for example: “If one of three cache nodes is killed, checkout p99 stays under 300 ms and the error rate stays under 0.1%.” Run it on a small slice with an automatic abort.
13. Key Terms
Test pyramid
Many fast unit tests, fewer integration tests, very few E2E.
Contract test
Checks that a provider still meets what a consumer expects.
Mock
A stand-in that verifies how it was called.
Stub
A stand-in that returns canned answers.
Fake
Pass clocks, stores, and clients into logic instead of constructing them internally. Fakes execute a lightweight model, stubs return preset answers, and mocks verify interactions. A hermetic test controls its inputs and external dependencies. Example and limits above.
Service virtualization
A stub served over the network.
Hermetic
Pass clocks, stores, and clients into logic instead of constructing them internally. Fakes execute a lightweight model, stubs return preset answers, and mocks verify interactions. A hermetic test controls its inputs and external dependencies. Example and limits above.
Dependency injection
Pass clocks, stores, and clients into logic instead of constructing them internally. Fakes execute a lightweight model, stubs return preset answers, and mocks verify interactions. A hermetic test controls its inputs and external dependencies. Example and limits above.
Flaky test
Passes or fails with no code change.
Shadow traffic
Copies of real requests sent to a new version; responses discarded.
Prober
A scripted fake user that checks production all the time.