A system design interview guide to a repeatable method for growing a system by orders of magnitude — measure, find what breaks first, fix it with the cheapest change that works, and repeat — without rewriting everything at once.
Student edition · start with the guarantee
Scale the measured bottleneck while preserving data and failure semantics as traffic grows.
Correctness contract: Capacity decisions use measured peak/shape and survivor headroom. Shard/async boundaries have explicit ownership, ordering, transactional, and freshness contracts.
Basic HTTP, databases, and programming are assumed. Specialized terms are explained below. Named products motivate the problem; this is an educational design, not a claim about their current internals. Capacity numbers are illustrative decimal payload estimates, not benchmarks. Add indexes, protocol overhead, replicas, headroom, and failure capacity before provisioning.
“How would you scale this to 10×? To 100×?” is less a question about any one technique than about whether you have a method. The wrong answer is a shopping list — “add caching, sharding, and a queue” — recited without knowing which bottleneck each one relieves. The right answer is a loop: measure the system, find the single resource that saturates first, apply the least invasive fix that removes it, and repeat, because scaling never fails everywhere at once. It fails at one place — the database’s write capacity, a connection pool, a single hot key — and that place moves each time you grow. This guide lays out the loop and then walks the ladder of fixes in the order you actually reach for them, noting what tends to break first at each order of magnitude.
Intuition first
Think of a coffee shop that gets ten times busier. You would not rebuild the shop on day one. First you find what is slow (the one espresso machine), then you apply the cheapest fix (a second machine, pre-made cold brew). Only when the shop is truly full do you open a second location. Scaling software follows the same order: measure, fix the one bottleneck cheaply, and repeat.
Each definition includes a concrete example and the condition under which the mechanism is useful. You can read this guide without opening another guide.
Cache-aside and invalidation
A read checks a cache, reads the authoritative store on a miss, then fills the cache. A write commits to the store and invalidates or refreshes the cached value. TTL means time to live, not a freshness proof.
Example. A reader fetches version 1, a writer commits version 2 and invalidates, then the delayed reader caches version 1. DB-first invalidation alone does not prevent this refill race.
Limit. Use invalidation-aware fill leases or version fences for stronger behavior; a TTL only bounds one entry's residence under additional assumptions. Authorization and revocation need an explicit stale-data policy.
Consistent hashing
A placement algorithm that maps both keys and server tokens into a shared, ordered hash space. A key belongs to the first token clockwise at or after its hash; the end wraps to the start. Adding a token changes only its newly owned interval, rather than most keys.
Example. Tokens at 10, 40, 80 own positions (80,10], (10,40], and (40,80]. Adding token 25 moves positions (10,25] from token 40 to token 25.
Limit. It stabilizes placement, not replica consistency. Expected primary remapping when adding an equally weighted node is 1/(n+1); balance depends on token allocation and workload.
Replication
Maintaining copies of data on independent storage nodes. Synchronous acknowledgement waits for specified durable copies; asynchronous replication sends changes after the client has already received success.
Example. A primary acknowledges after two durable copies in different zones. A follower that applies updates later can serve an old value even though the write is durable.
Limit. Replica count is not a complete durability or availability guarantee. State the failure domains, acknowledgement policy, promotion rules, repair process, and what happens if all copies fail.
Backpressure and load shedding
Backpressure tells an upstream producer that the downstream stage cannot accept more work. Buffering delays that signal; shedding deliberately rejects or drops lower-priority work when a bound is reached.
Example. A sink accepts 100 events/s while input is 150/s. A 1000-event queue fills in 20 seconds. The system must then block, reject, or apply its documented drop policy.
Limit. A finite queue cannot absorb an infinite outage. Prioritized messages still need hard quotas, deadlines, and bounded client queues; otherwise an exemption can exhaust the system.
Failure domains and redundant capacity
A failure domain is a set of components vulnerable to one shared event: process, host, rack, zone, or region. Redundancy must separate domains and leave enough surviving capacity to carry peak demand.
Example. Five replicas placed 2/2/1 across three regions leave at least three after any one region fails. A 3/1/1 layout can lose its quorum with the largest region.
Limit. Independent-failure probability formulas are illustrative assumptions. Shared code/config, dependencies, routing, and control planes can fail all replicas together. N+1 machines does not imply tolerance of a whole zone.
Transactional outbox
A business transaction writes its state change and an event row to the same database. A relay publishes committed event rows later, retrying until the broker durably accepts them.
Example. An order and its OrderCreated outbox row commit together. A relay crash after publish but before marking sent publishes the same event ID again on restart.
Limit. The relay is at-least-once, not magically exactly-once. Consumers dedup transactionally; preserve per-entity sequence when order matters. CDC is change data capture: reading committed database changes.
1. The Method & Scope
Scaling is an iterative process, not a one-shot design. The method is the answer; the techniques are just its steps.
Measure. Instrument first. You cannot scale what you cannot see — find the resource that saturates (CPU, memory, disk I/O, network, database, locks) using latency percentiles and utilization, not guesses.
Find the bottleneck. At any given load, usually one resource saturates first (CPU, DB connections, disk, a hot key). Fixing anything else buys little. Once you fix it, the next bottleneck appears, so measure again after every change.
Apply the cheapest fix that works. Prefer the least invasive change — a bigger box, a cache, a read replica — over the most invasive — sharding, a rewrite. YAGNI: do not shard for a load you do not have.
Repeat. The fix moves the bottleneck somewhere else. Re-measure and go again.
Scope. The goal is to grow throughput by 10× then 100× while holding latency and error rate within SLO and keeping cost sane. Correctness and the multi-region story are assumed handled elsewhere; here it is about capacity.
Questions to ask first
10× or 100× of what: requests per second, users, data size, or all three?
What is the read/write mix, and how skewed is it? (One celebrity key behaves differently from uniform traffic.)
What are the latency and availability targets at the new scale?
How fast is the growth: a launch next week, or steady growth over a year?
What does the current system look like, and where are the metrics?
2. Back-of-the-Envelope
Numbers tell you which order of magnitude breaks which resource, so you can predict the next bottleneck instead of discovering it in production.
Scale
Load (example)
What tends to break first
1×
~1K req/s, one app box + one DB
Fits on a single machine; nothing yet.
10×
~10K req/s
App CPU and DB connections; single box runs out.
100×
~100K req/s
DB write throughput and hot rows; one primary can’t keep up.
Read/write mix
often 90% reads / 10% writes
Reads → caches + replicas; writes → sharding.
Cache hit rate
90% hits
Cuts DB read load ~10× — the biggest single lever.
Connection ceiling
DB caps ~a few hundred connections
Thousands of app threads → pool exhaustion.
The pattern is consistent: reads scale out cheaply with caching and replicas, but writes are the wall. Somewhere around 100× a single write primary cannot keep up, and that is when the expensive fix — sharding — finally earns its cost.
Worked example: sizing the 100× system
Assume 100,000 requests per second, 90% reads, a 90% cache hit rate, a DB node that handles about 5,000 reads/s or 5,000 writes/s, queries that take 5 ms, and app boxes that max out at 1,500 rps. These are round, made-up but realistic numbers. The method is the point.
Quantity
Reasoning
Result
Reads and writes
100K × 0.9 and 100K × 0.1
90K reads/s, 10K writes/s
Reads reaching the DB
90K × (1 − 0.9 hit rate)
9K reads/s
Read replicas (single primary)
9K ÷ 5K, round up, +1 spare
3 replicas
Write shards
10K ÷ (5K × 50% target)
4 shards
App boxes
100K ÷ (1,500 × 60% target)
112 boxes
Connections if each box pools 20
112 × 20
2,240 (DB limit ~500)
Connections actually busy (Little’s law)
(9K + 10K) queries/s × 0.005 s
~95
Two lessons fall out. First, the cache did most of the work: without it the DB would see 90K reads/s, or 18 replicas. Second, only about 95 connections are busy at once, but naive pools would open 2,240. A shared pooler such as PgBouncer closes that gap. Note that replicas do not help writes at all. Every replica still applies every write, so write load is the reason to shard.
import math
rps, read_frac, hit = 100_000, 0.90, 0.90
reads, writes = rps * read_frac, rps * (1 - read_frac)
db_reads = reads * (1 - hit) # cache misses reach the DB
replicas = math.ceil(db_reads / 5_000) + 1 # 5K reads/s each, +1 spare
shards = math.ceil(writes / (5_000 * 0.5)) # 5K writes/s, run at 50%
boxes = math.ceil(rps / (1_500 * 0.6)) # 1.5K rps max, run at 60%# Little's law: connections busy = query rate x query time
db_qps = db_reads + writes
conns_needed = db_qps * 0.005 # 5 ms per query
print(f"DB reads/s {db_reads:,.0f} replicas {replicas} shards {shards}")
print(f"app boxes {boxes} naive pool conns {boxes * 20:,}")
print(f"DB connections actually busy {conns_needed:.0f}")
Common mistake
Multiplying everything by 100 in one step. At 100× the bottleneck is different, not just bigger. A design that scaled from 1× to 10× by adding app boxes will fail at 100× on DB writes and connections. Redo the math at each order of magnitude.
3. The Scaling Ladder
The fixes come in a natural order, cheapest and least invasive first. You climb only as far as the load forces you — most systems never reach the top rungs.
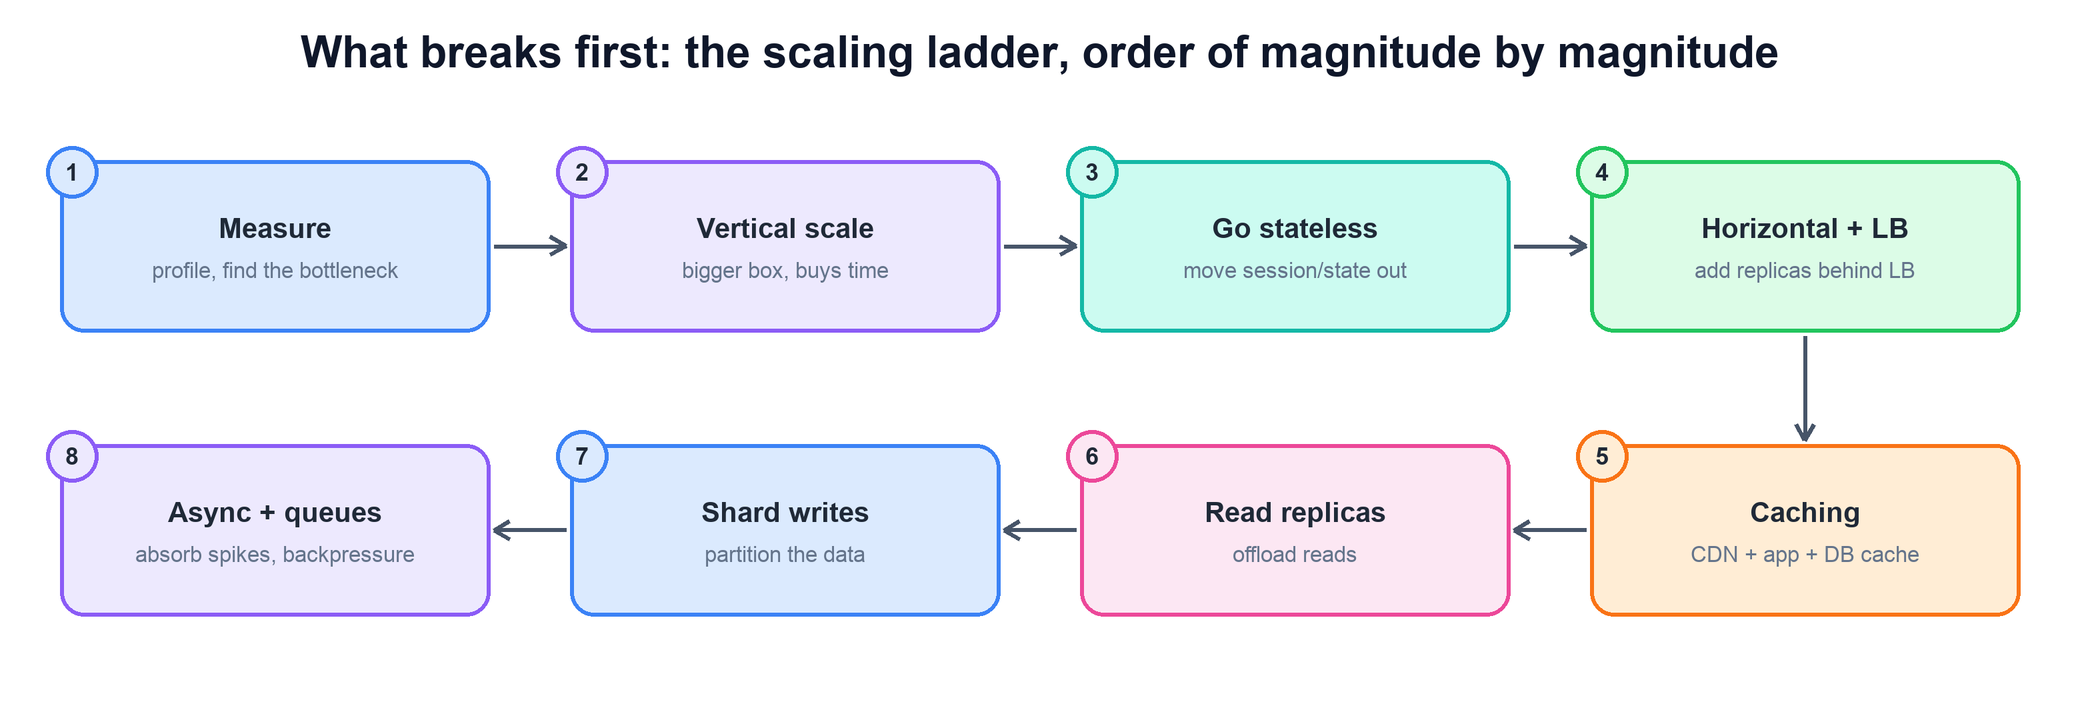
The ladder, cheapest fix first: measure, scale vertically, make the app stateless, scale horizontally behind a load balancer, add caching, add read replicas, shard the writes, and push slow work to async queues. Each rung moves the bottleneck to the next.
Vertical scaling — a bigger box — is the first and simplest move. It buys time with zero architectural change, but hits a ceiling (the biggest machine) and a price cliff, so it is a bridge, not a destination.
Statelessness is the pivot that unlocks everything after it. Once the app holds no per-user state locally — sessions in a shared cache, files in object storage — any instance can serve any request, so you can add and remove instances freely.
Horizontal scaling puts many stateless instances behind a load balancer. This is where growth becomes elastic: add boxes to add capacity.
Everything below the app tier — caching, replicas, sharding, async — addresses the data layer, which is where scaling gets genuinely hard, and which the rest of this guide covers.
4. A Scaled Architecture
Assembled, the rungs form a familiar layered architecture. Each layer absorbs load so the layer below it sees less.
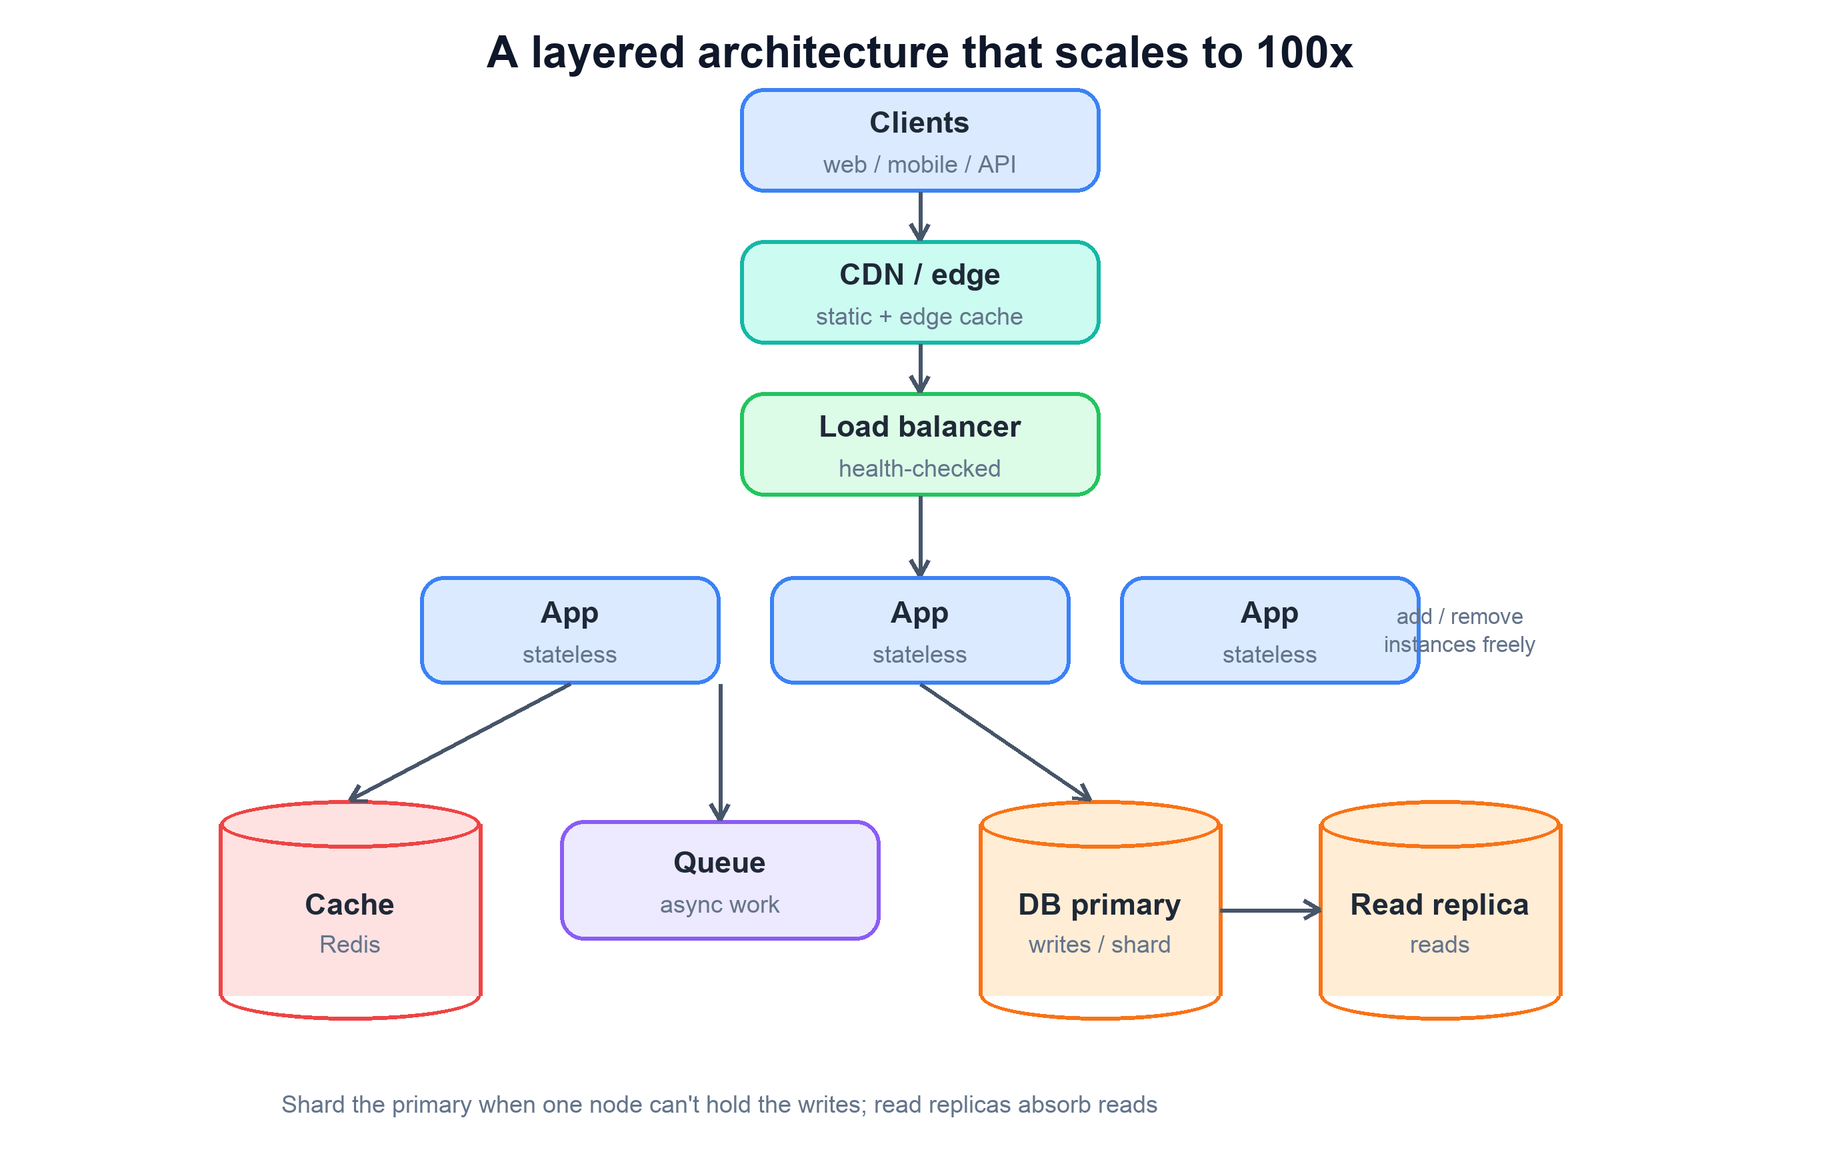
Clients hit a CDN for static and edge-cacheable content; dynamic requests pass a load balancer to a horizontally scaled, stateless app tier; the app tier leans on a distributed cache, a queue for async work, and a database split into a write primary and read replicas (sharded when writes outgrow one node).
CDN / edge. Serves static assets and cacheable responses from points of presence near the user, taking the largest slice of traffic off your origin entirely.
Load balancer. Spreads dynamic traffic across app instances and routes around unhealthy ones.
Stateless app tier. Scales horizontally; because it holds no local state, autoscaling can add or drop instances with the load.
Cache. A distributed cache (Redis/memcached) absorbs repeated reads before they reach the database.
Queue. Moves slow or bursty work off the request path so a spike is absorbed, not dropped.
Database. A write primary with read replicas for read scale, and sharding once the write volume exceeds a single node.
5. Caching Layers
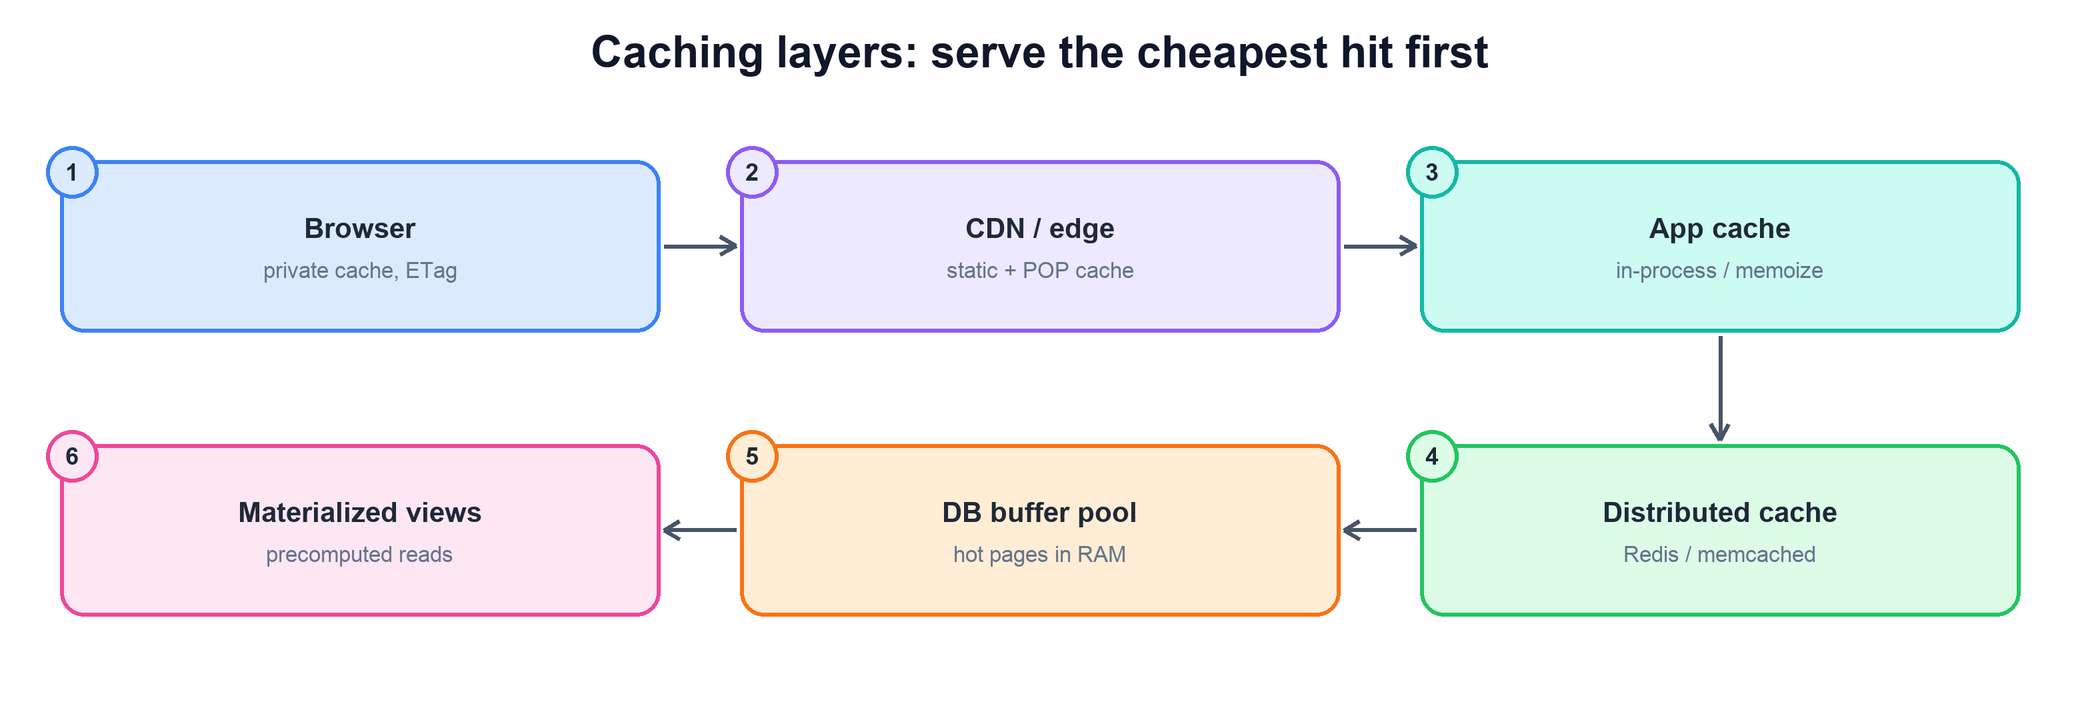
Caching is the highest-leverage move because it removes work rather than adding capacity. It exists at every layer, and the discipline is to serve each request from the cheapest cache that can answer it.
From cheapest to most expensive hit: the browser’s private cache, the CDN edge, an in-process app cache, a shared distributed cache, the database’s own buffer pool, and precomputed materialized views. A request should stop as high up this stack as possible.
A 90% hit rate cuts backend read load roughly tenfold — often the single biggest lever available. But caching adds its own hard problems, and naming them signals maturity:
Invalidation. Stale data is the cost of caching; you need a TTL or explicit invalidation strategy, and to decide how much staleness each read tolerates.
Stampede / thundering herd. When a hot key expires, thousands of requests miss at once and hammer the origin. Mitigate with request coalescing (one fetch fills the cache while others wait), early/jittered expiry, or serving stale while revalidating.
Hot keys. A single wildly popular key can overload one cache node; replicate or locally cache it.
function read(key):
  v = cache.get(key)
  if v is not None:
    return v                          # fast path: the common case
  with single_flight(key):            # coalesce concurrent misses
    v = cache.get(key)                # re-check after acquiring
    if v is None:
      v = db.read(key)                # only one caller hits the DB
      cache.set(key, v, ttl=jitter()) # jitter avoids synchronized expiry
  return v
6. Replicas, Sharding & Async
Read replicas offload selected reads but still apply primary writes. Fresh/session reads need authority/apply barriers or dependency tokens; a primary flag or sticky session alone is not proof after failover. Measure replica lag and freshness failures.
Before sharding, optimize queries/indexes, batching, contention, data lifecycle, and write amplification. Sharding is a major scale lever, not the only possible throughput improvement. High-cardinality keys do not ensure even access; one hot key remains hot. Account for cross-shard transactions, joins, rebalancing, ownership versions, and consistent-hash migration.
Async work needs durable intent/outbox, idempotent effects, ordering, finite queues, deadlines, and recovery capacity. It smooths bursts and moves latency; it does not make total compute free or allow unlimited outages. Scale from measured bottlenecks rather than treating a fixed ladder as compulsory.
7. Connection Limits & Backpressure
Two failure modes bite specifically as you scale out, and both surprise people because they are not about raw compute.
Connection limits. Databases cap concurrent connections at a few hundred, but a horizontally scaled app tier can have thousands of threads each wanting one. Without a bound, the app exhausts the database’s connections and everything stalls. The fix is a connection pool — often a dedicated pooler — that multiplexes many app threads onto a small, bounded set of database connections. The pool size, not the thread count, is the real concurrency limit against the database.
Backpressure. When a downstream component saturates, an unbounded system keeps accepting work it cannot do, queues grow without limit, latency explodes, and it collapses — often taking callers with it in a cascading failure. A well-behaved system pushes back: bounded queues that reject when full, timeouts so callers do not wait forever, load shedding that drops low-priority work early, and circuit breakers that stop hammering a failing dependency. Failing fast under overload is healthier than failing slowly for everyone.
function handle(req):
  if inflight >= max_inflight:
    return 503                         # shed load early, don't queue forever
  with pool.acquire(timeout=50ms) as conn: # bounded DB concurrency
    return conn.query(req, timeout=200ms)  # deadline, don't wait forever
8. Bottlenecks & Tradeoffs
Scaling is a sequence of trades, and the discipline is to make the cheapest one that removes the current bottleneck — no more.
Vertical vs horizontal. Vertical is simple but ceilinged and priced steeply; horizontal is elastic but demands statelessness and a load balancer. Climb vertically to buy time, then go horizontal.
Consistency vs performance. Caches and read replicas trade freshness for throughput. Decide per read how much staleness is acceptable; send the few that must be current to the primary.
Simplicity vs scale. Sharding and async unlock scale but add operational and cognitive cost forever. Defer them until the load is real (YAGNI); premature sharding is a common self-inflicted wound.
Cost awareness. Every rung costs money — more boxes, more replicas, cross-node traffic. Scaling is an economics problem: the goal is the SLO at the lowest total cost, and sometimes the right answer is to make the workload cheaper (a better query, less data) rather than to buy more capacity.
Availability under load. The system must degrade gracefully, not collapse. Backpressure, load shedding, and circuit breakers are what turn an overload into slow-but-alive instead of a cascading outage.
Worked example: more app servers exhaust the database pool
Start with 20 app instances, each configured for 20 DB connections.
Read top to bottom. The table below explains the state and guarantee at each step.
Step
State, calculation, and reasoning
1. Count pooled connections
20×20=400 potential connections before admin/background work.
2. Scale apps tenfold
200×20=4000 connections can overwhelm a DB even if each app remains lightly loaded.
3. Set an aggregate concurrency budget
Use bounded pools/pooler, admission limits, timeouts, and measured DB capacity. Connection limits are configuration/hardware-dependent, not universally a few hundred.
4. Preserve async correctness
Commit DB work and emitted intent through an outbox. A queue shortens the request path but does not remove total work or guarantee eventual completion by itself.
Check your understanding: Does sharding fix a single hot key?
Not automatically. All operations for that key can still land on one authority. Splitting it requires a different correct data/aggregation model.
Run a small, testable model
Download concepts.py. It uses only the Python 3.10+ standard library. From the directory where you saved it, run:
python3 concepts.py capacity
python3 concepts.py test
The model computes safe usable capacity and procurement; adapt its bound to the measured aggregate connection/work budget.
The program contains deterministic assertions and failure traces. It is a learning model, not a production service: it does not implement network consensus, distributed durability, authentication, or third-party delivery. Read its contracts and try changing an input before extending it.
Staleness from caches and replicas, cost, the complexity sharding adds forever.
10. Common Mistakes
Mistake
Why it hurts
Do this instead
Sharding first
Permanent complexity for load you may never have
Exhaust vertical, cache, replicas, async first
Adding replicas to fix write load
Every replica applies every write, so it does nothing
Batch writes, queue them, or shard
Ignoring hot keys
One key overloads one shard or cache node
Local caching, key splitting, request coalescing
Unbounded queues and pools
Latency explodes, then everything times out
Bounded queues, pool limits, load shedding
Autoscaling the app into a fixed DB
More app boxes means more connections and more DB load
Scale the bottleneck, cap the app tier, use a pooler
11. Summary
Scaling from 10× to 100× is a method, not a menu: measure, find the one thing that breaks first, apply the cheapest fix, and repeat. Reads scale out easily; writes are the wall you climb last.
Concern
Mechanism
Where do we start?
Measure and find the single saturating resource — never optimize blind.
What is the first fix?
Vertical scaling to buy time, then statelessness to unlock horizontal scaling.
How do we scale reads?
Caching at every layer (biggest lever) plus read replicas for the rest.
How do we scale writes?
Shard by a high-cardinality, evenly-accessed key — the expensive fix, used last.
How do we handle slow work?
Push it to async queues; absorb spikes and shorten the request path.
Why does scaling out stall?
DB connection limits — bound them with a connection pool, not more threads.
Treat scaling as economics — hit the SLO at the lowest cost, sometimes by shrinking the work.
The recurring theme: scale is a moving bottleneck. Instrument so you can see it, fix the one place that is actually saturated with the least invasive change that works, and defer the expensive moves — sharding, rewrites — until the load genuinely demands them. Method beats menu.
12. Check Yourself
Your cache hit rate drops from 95% to 90%. By how much does DB read load change?
AnswerThe miss rate goes from 5% to 10%, so DB reads double. Small changes in hit rate have large effects near the top.
You add two read replicas and write latency does not improve. Why?
AnswerReplicas only offload reads. Every replica still applies all writes, and the primary still takes them all. Writes need batching, async, or sharding.
An app handles 3,000 rps and each DB query takes 20 ms. About how many DB connections are busy at once?
AnswerLittle’s law: 3,000 × 0.02 = 60 connections (assuming one query per request).
Why must the app tier be stateless before you scale it horizontally?
AnswerIf a box holds session state, requests must stick to that box. Then you can’t freely add, remove or replace boxes, and losing one loses its users’ state. Move state to a shared store.
What is backpressure, and give two ways to apply it?
AnswerPushing back on callers when you are full, instead of accepting work you can’t finish. Examples: bounded queues that reject when full, returning 429/503 early (load shedding), and timeouts.
What makes a good shard key?
AnswerHigh cardinality, even spread of load (no hot shard), and alignment with the most common queries so they hit one shard. User id often works; a timestamp usually makes one hot shard.
13. Key Terms
Bottleneck
The resource that saturates first and caps throughput.
Vertical scaling
A bigger machine.
Horizontal scaling
More machines behind a load balancer.
Stateless
A server that keeps no per-user state between requests.
Cache hit rate
Share of reads served from cache.
Read replica
A copy of the DB that serves reads and lags slightly.
Sharding
Splitting data across nodes by a key.
Hot key
One key that gets far more traffic than others.
Connection pooler
Shares few DB connections among many app threads.
Little’s law
Items in flight = arrival rate × time in system.
Backpressure
Backpressure tells an upstream producer that the downstream stage cannot accept more work. Buffering delays that signal; shedding deliberately rejects or drops lower-priority work when a bound is reached. Example and limits above.
14. Further Reading
Martin Kleppmann, Designing Data-Intensive Applications, chapters 1, 5 (replication) and 6 (partitioning).
Brendan Gregg, “The USE Method” for finding the bottleneck.
Site Reliability Engineering, chapter “Handling Overload”. Free at sre.google.
David Yanacek, “Using load shedding to avoid overload”, Amazon Builders’ Library.
Alex Xu, System Design Interview, chapter 1, “Scale from zero to millions of users”.