A system design interview guide to distributed consensus — how a set of unreliable nodes agree on a single ordered log of commands, why the problem is provably hard, and exactly how Raft and Paxos solve it.
Student edition · start with the guarantee
Understand the state and protocol rules that let crash-recovering nodes preserve one committed history.
Correctness contract: Safety is defined under non-Byzantine faults with durable protocol state; progress requires enough reachable healthy participants and suitable timing. Majority overlap alone is not the whole proof.
Basic HTTP, databases, and programming are assumed. Specialized terms are explained below. Named products motivate the problem; this is an educational design, not a claim about their current internals. Capacity numbers are illustrative decimal payload estimates, not benchmarks. Add indexes, protocol overhead, replicas, headroom, and failure capacity before provisioning.
Consensus is the beating heart of every strongly consistent distributed system. A lock service, a configuration store, a database that promises linearizable writes — underneath each one is a group of nodes that must agree, and keep agreeing, on one authoritative sequence of decisions even as machines crash and networks drop packets. This is the same quorum core that the companion guide Zero Data Loss During a Network Partition leans on to survive a split; here we go one level deeper and open up the algorithms themselves. We will build the replicated-state-machine model, confront the FLP impossibility result that says perfect consensus is unattainable in a fully asynchronous world, and then walk through Raft — election and log replication, line by line — and Paxos — the original single-decree protocol and the Multi-Paxos form that real systems ship. The goal is precision: this is a topic where a hand-wave is instantly visible, and where getting the commit rule, the election restriction, and the two Paxos phases exactly right is the seniority tell.
Each definition includes a concrete example and the condition under which the mechanism is useful. You can read this guide without opening another guide.
Raft terms and commit rules
Raft elects at most one leader per logical term and replicates an ordered log. To advance commit by counting replicas, the leader requires a majority storing an entry from its current term; earlier entries then commit as part of that prefix.
Example. A new leader commits a current-term no-op before relying on old-term prefix entries. Log up-to-date voting and matching rules preserve committed history.
Limit. Terms are not fixed time intervals. Old leaders from earlier terms can remain unaware. Durable term/vote state, membership rules, read barriers, and client-request dedup are required.
Quorum
A set of replicas whose responses are sufficient for an operation. In a fixed set of N replicas, read size R and write size W overlap whenever R+W>N. A majority is one particular quorum, not the definition of every quorum.
Example. With N=3, writes to {A,B} and reads from {B,C} share B. If the write completed durably and replicas preserve a comparable version, B carries that version forward.
Limit. Overlap alone does not provide linearizability: concurrent or failed writes, sloppy replica sets, and version selection matter. Consensus adds protocol rules to preserve decisions.
Write-ahead log and fsync
A WAL records updates before data pages are considered committed. Recovery replays it after a crash. fsync (or an equivalent storage contract) requests that buffered bytes reach durable storage rather than only process/OS memory.
Example. A server acknowledges after its WAL commit and required replica writes are durably accepted. A process crash can then reconstruct the committed update.
Limit. Appending to a file alone does not guarantee power-loss durability. Device behavior, filesystem ordering, replicas, corruption, and the declared fault budget still matter.
Linearizability
Each completed operation appears to occur at one instant between its invocation and response, respecting real-time order. A read that begins after a write finishes cannot return a value older than that write, unless a later write superseded it.
Example. A write x=7 returns success; a later read must return 7 or a value from a later ordered write. A read overlapping that write may return the old or new value.
Limit. Not the same as durability or transaction serializability. A leader may be stale; linearizable leader reads need current authority and an applied-state barrier.
CAP and consistency models
During a network partition, a distributed service cannot offer both linearizable operations and successful completion of every eligible request at nonfailed nodes. CAP consistency is linearizability; it is not durability or 'no bytes lost'.
Example. A minority that cannot contact the authority blocks or rejects a linearizable read/write. A mergeable append log can accept local writes on both sides and preserve both records, while not giving one-copy ordering.
Limit. Causal/session/eventual guarantees are not a universal availability ladder. Sticky routing alone fails after failover unless the new replica has satisfied the client's dependencies.
Fencing tokens
A strictly increasing grant number attached to operations. The protected resource atomically compares it with its durable highest accepted token and rejects older operations, making superseded clients unable to overwrite newer effects.
Example. A has token 33 and pauses. B acquires 34 and writes. When A sends token 33 later, the resource rejects it because its fence is already 34.
Limit. A new grant must be installed at the resource before it promises exclusion there. Token 33 can still pass until 34 is observed. Equal-token operations also need sequence/idempotency rules if they can arrive out of order.
Intuition first
Picture five friends keeping the same diary by text message. Phones die and messages get lost. They agree on one rule: an entry counts once at least three of the five have written it down. Any two groups of three share at least one friend. So two different entries can never both "count" for the same line. One friend acts as the scribe to keep order. If the scribe goes quiet, someone asks for three votes to become the new scribe. That is Raft in one paragraph.
1. What Consensus Is & Why It’s Hard
The clean way to frame consensus is the replicated state machine (RSM). Imagine a deterministic state machine — a key-value store, say — and run an identical copy on each of several nodes. If every copy starts in the same state and applies the same commands in the same order, every copy ends in the same state. That reduces “keep these replicas identical” to one problem: agree on an ordered log of commands. Consensus is the machinery that makes all correct nodes agree on that log, entry by entry, so that a client talking to any replica sees one consistent history.
Formally, a consensus protocol must satisfy three properties:
Agreement. No two correct nodes decide on different values for the same log slot. This is the safety property that must never break.
Validity (integrity). A decided value must be one that was actually proposed by some node — the protocol cannot invent values out of thin air, and a node decides at most once per slot.
Termination. Every correct node eventually decides. This is the liveness property — the system must make progress, not stall forever.
Why is this hard? Because of a deep result: the FLP impossibility (Fischer, Lynch & Paterson, 1985). It proves that in a fully asynchronous system — one with no bound on message delay or relative processor speed — there is no deterministic protocol that guarantees both safety and termination if even a single node may crash. The intuition: you can never distinguish a crashed node from one that is merely slow, so any protocol that waits for it can hang forever, and any protocol that gives up on it can be tricked into disagreeing. FLP does not say consensus is usually impossible — it says you cannot guarantee it will always terminate in a purely async model.
Real systems escape FLP not by breaking it but by weakening its assumptions. They assume partial synchrony: the network is asynchronous during bad periods but eventually behaves well enough (bounded delays) for long enough to make progress. On top of that they add timeouts (to suspect crashed nodes) and a touch of randomization to break symmetry: Raft randomizes election timeouts, and Paxos proposers that keep pre-empting each other retry after a random backoff. The crucial design discipline is this: these mechanisms are used only to preserve liveness. Safety — agreement — never depends on any timing assumption. A slow network or a bad timeout can delay a decision; it can never cause two nodes to decide differently.
Interview tip. State the majority-intersection insight and FLP in one breath — that is the seniority tell. “Any two majorities overlap, so at most one value can win a quorum; and by FLP you can’t guarantee termination in a fully async model, so real systems assume partial synchrony and use timeouts for liveness while keeping safety timing-independent.” That single sentence signals you understand both why consensus works and why it’s fundamentally hard.
2. Safety, Liveness & Majority Quorums
Safety means decided/committed history does not fork under the stated failure model. Liveness means new operations eventually complete under sufficient reachable participants and stable-enough timing. FLP rules out guaranteed deterministic consensus termination in a fully asynchronous model with even one possible crash; practical protocols make timing/partial-synchrony assumptions for progress.
Raft/Paxos normally assume non-Byzantine crash-recovery with durable state, not forgotten votes/promises after restart. Raft persists term, vote, and log as required before responses. Paxos acceptors persist promises and accepted proposal state. Faulty/compromised nodes require a different model; classic partially synchronous Byzantine replication commonly needs 3f+1 participants, but that is not a universal bound for every trust/synchrony model.
Any two majorities of one fixed membership intersect. With 2f+1 replicas, f may be unavailable while a majority remains. The intersection transmits safety information only because the protocol's promise/vote/log rules preserve it. It does not itself prevent every stale leader or decide a value. Safe membership change is part of the protocol.
3. Raft: Leader Election
A follower times out and becomes a candidate, increments/persists its term, votes for itself, and asks for votes. A vote requires no conflicting vote in that term and a candidate log at least as up-to-date (last term, then last index). A majority elects at most one leader per term. Higher-term RPCs update durable term/vote state and demote as required.
Terms are logical integers, not fixed bounded intervals. A stale leader in an older term may still believe it is leader until it hears newer information. It cannot safely commit without quorum/log rules; reads and external effects need authority checks/fences. Randomized timeouts help liveness but do not prove leader failure. The paper's 150–300 ms example is not a universal production setting; tune relative to actual network and storage latency.
4. Worked Trace: A Raft Election with a Split Vote
Five servers S1–S5. S1 is leader in term 1 and crashes. All logs are identical, so every vote check passes. A majority is 3.
Time
Event
Votes
t=0
S1 (leader, term 1) crashes. Heartbeats stop.
–
t=181 ms
S2's timer fires first. It moves to term 2, votes for itself, sends RequestVote.
S2: {S2}
t=183 ms
S4's timer fires before S2's request reaches it. S4 also moves to term 2 and votes for itself.
S4: {S4}
t=184 ms
S3 hears S2 first and votes S2. S5 hears S4 first and votes S4. Each voter has now used its one vote for term 2.
S2: 2, S4: 2
t=184–350 ms
Nobody reaches 3. Term 2 has no leader.
split
t≈350 ms
Each node picked a fresh random timeout. S3's fires first. It moves to term 3 and votes for itself.
S3: {S3}
t≈352 ms
S2, S4 and S5 see term 3 > 2, step down, reset votedFor, and vote S3.
S3: 4
t≈353 ms
S3 is leader of term 3 and sends heartbeats at once.
done
Terms act as a logical clock. A term can end with no leader. A new term begins right away.
Why the timeout range matters
If the random range is narrow compared with the network delay, split votes repeat. The Raft paper uses 150–300 ms with sub-10 ms RPCs, so one node almost always wins in the next round. The rule of thumb is: broadcast time « election timeout « mean time between failures.
5. Raft: Log Replication & Commit
Once a leader is in charge, client commands become log entries and the leader replicates them. This is where the exact rules matter, and where interviews probe hardest.
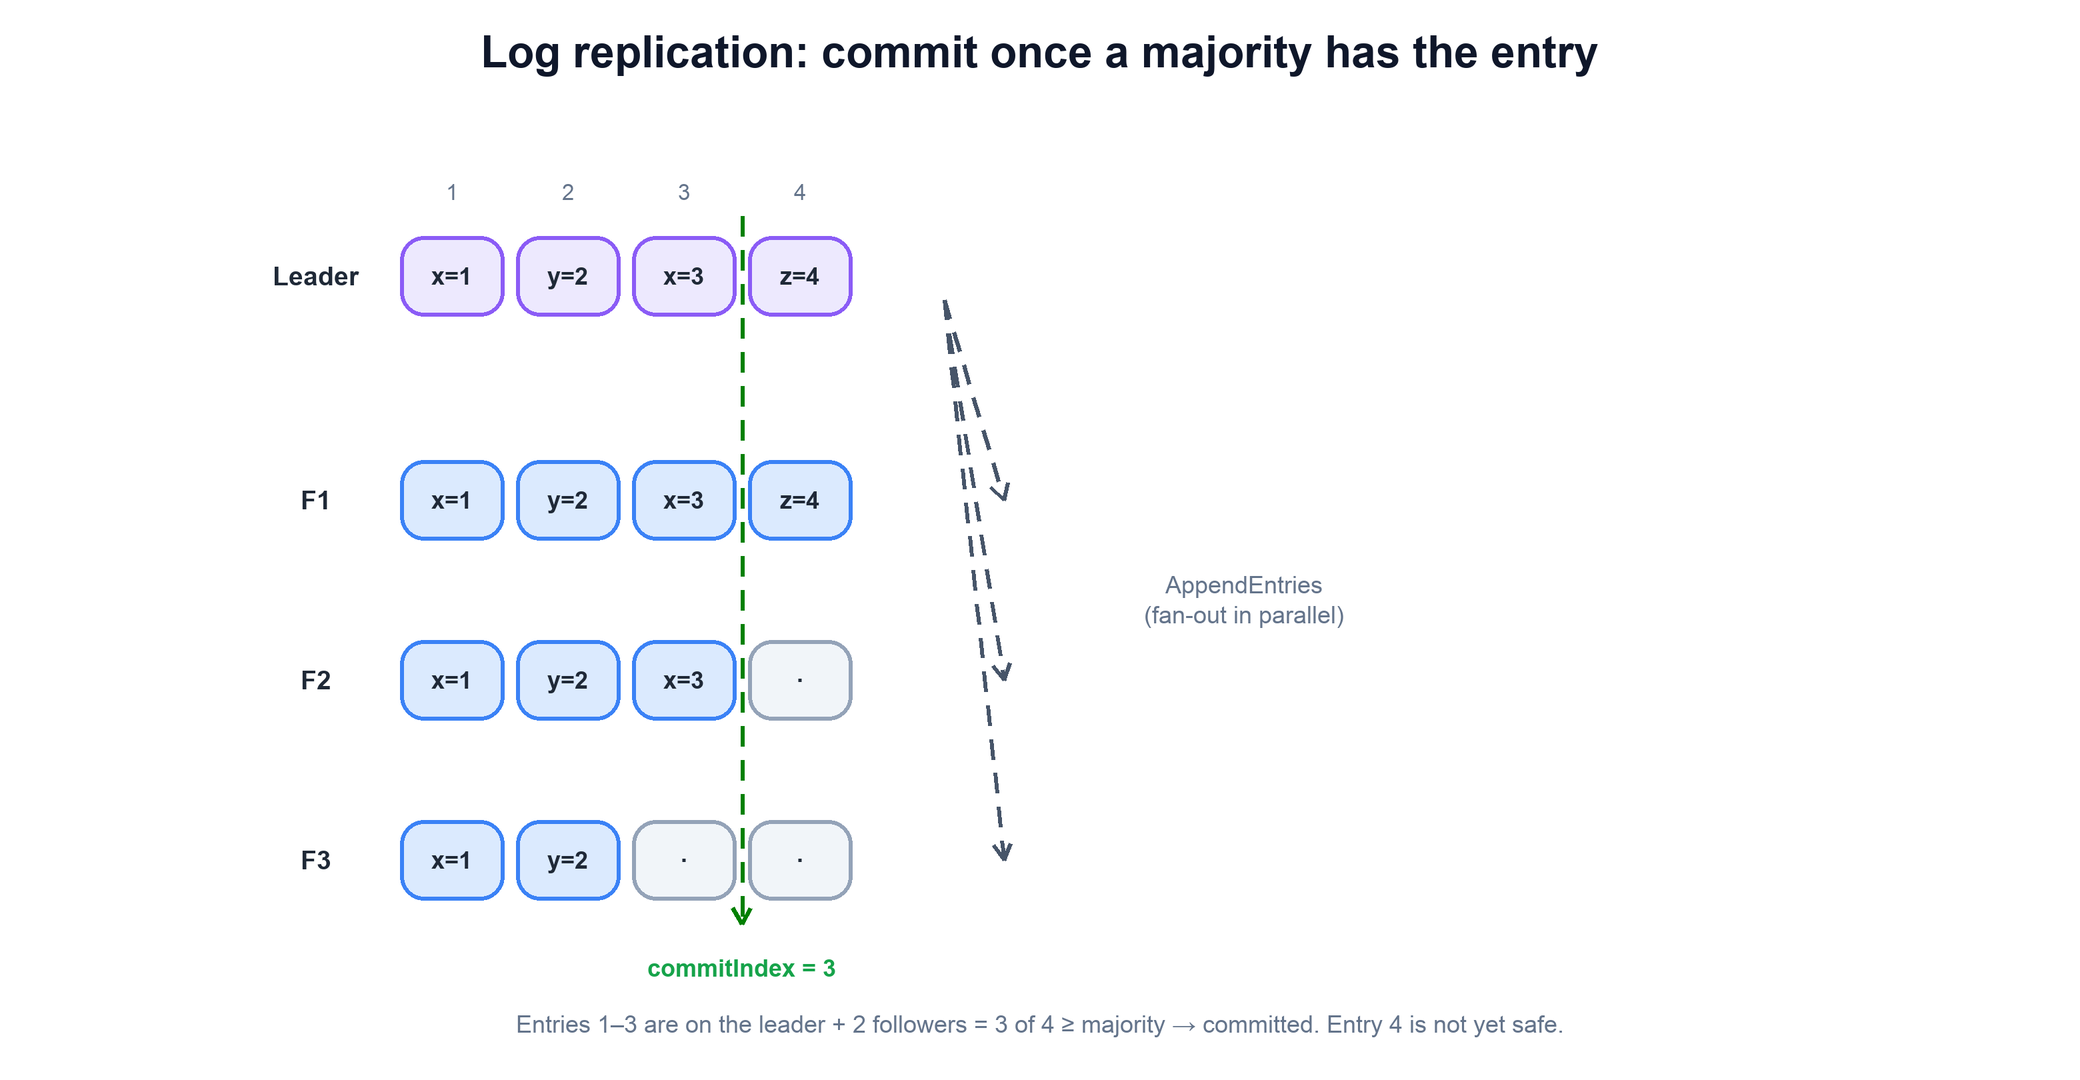
Each entry stores a command, the term in which the leader created it, and its index (position in the log). The leader appends a new entry locally, then sends AppendEntries RPCs to followers to replicate it. An AppendEntries carries not just the new entry but also the index and term of the entry immediately preceding it (prevLogIndex, prevLogTerm), which enables a consistency check.
An entry is committed once it is stored on a majority of nodes and was created in the leader’s current term. Here entries 1–3 are on the leader plus two followers — a majority — so commitIndex = 3; entry 4 is still in flight and not yet safe.
The Log Matching Property
Raft maintains a strong invariant that keeps logs consistent without expensive comparison: if two logs contain an entry with the same index and term, then (a) they store the same command at that index, and (b) all preceding entries are identical. Part (a) holds because a leader creates at most one entry per index per term and never changes it. Part (b) is enforced by the AppendEntries consistency check: a follower rejects the RPC unless its log already contains an entry matching the leader’s prevLogIndex/prevLogTerm. By induction, a successful append implies the logs agree on everything up to that point.
The commit rule (get this exactly right)
An entry is committed — safe to apply to the state machine and acknowledge to the client — when both conditions hold:
The entry is stored on a majority of servers (durably); and
The entry was created in the leader’s current term.
The second clause is subtle and famous. A leader may not conclude that an entry from a previous term is committed merely because it now sits on a majority — doing so can lead to a committed entry being overwritten (the scenario in Figure 8 of the Raft paper). Instead, a new leader commits entries from earlier terms only indirectly: once it commits an entry from its own current term (which is on a majority), the Log Matching Property means all preceding entries are committed too. In practice a new leader appends a no-op entry in its term at the start of its reign precisely to carry older entries across this bar. Once commitIndex advances, each node applies newly committed entries to its state machine in log order.
The election restriction (leader completeness)
How do we guarantee a new leader has every committed entry, so nothing already promised to a client is lost? Through a restriction on voting: a node grants its vote only to a candidate whose log is at least as up-to-date as its own. “Up-to-date” is defined by the last entry: a higher last-term wins; if the last terms tie, the longer log wins. Because a committed entry sits on a majority, and any election-winning candidate also needs a majority, those two majorities intersect — so at least one voter holds every committed entry and would refuse to vote for a candidate missing it. Therefore any candidate that can win an election already contains all committed entries. This is the Leader Completeness property, and it is why Raft never needs to ship committed entries “backward” from followers to a new leader.
Repairing follower logs
Followers can fall behind or hold uncommitted entries from a deposed leader. The leader reconciles each follower with a per-follower nextIndex (the next entry it expects to send). If an AppendEntries is rejected because the consistency check failed, the leader decrements nextIndex and retries, walking backward until it finds the last point where the logs agree; from there it overwrites any conflicting follower entries with its own. Uncommitted entries can be overwritten safely — only committed ones are sacred, and Leader Completeness guarantees the leader has all of those. The pseudocode below is the follower’s side of that handshake.
function handle_append_entries(req):
# 1. Reject anything from a stale leader.
if req.term < currentTerm:
return {term: currentTerm, success: false}
if req.term > currentTerm:
currentTerm = req.term # adopt newer term...
votedFor = null # new term: no vote cast in it yet
role = FOLLOWER # ...and accept this leader
reset_election_timer() # valid RPC = leader is alive# 2. Consistency check: our log must match at prevLogIndex.
if req.prevLogIndex > last_index() or
log[req.prevLogIndex].term != req.prevLogTerm:
return {term: currentTerm, success: false} # leader will back off nextIndex# 3. Append: overwrite conflicts, then add new entries.
for entry in req.entries:
if log[entry.index] exists and log[entry.index].term != entry.term:
truncate_log_from(entry.index) # drop conflicting suffix
if entry.index > last_index():
log.append(entry)
persist(currentTerm, votedFor, log) # fsync BEFORE replying success# 4. Advance commit index, but only over entries this RPC verified.# Entries past prevLogIndex + len(entries) may be stale leftovers# from an old leader (e.g. on a heartbeat), so last_index() is wrong.
if req.leaderCommit > commitIndex:
commitIndex = min(req.leaderCommit, req.prevLogIndex + len(req.entries))
apply_committed_entries_to_state_machine()
return {term: currentTerm, success: true}
6. Worked Traces: Log Repair and Figure 8
Repairing a follower's log
New leader L in term 4 has entry terms [1,1,1,2,4,4] at indexes 1–6. Follower F has [1,1,1,2,2,2,2]. Its entries 5–7 came from a term-2 leader that crashed before committing them.
The discarded entries were never committed, so no promise to a client breaks. Real systems speed this up: the follower replies with the conflicting term and its first index, so the leader skips a whole term per round trip.
Why the "current term" commit rule exists (Figure 8)
Five servers. Follow the steps. They show how an old-term entry on a majority can still be overwritten.
S1 leads term 2. It writes entry X at index 2 and copies it to S2 only.
S1 crashes. S5 wins term 3 with votes from S3, S4, S5. It writes entry Y at index 2, only locally, then crashes.
S1 restarts and wins term 4. It copies X to S3. Now X (term 2) sits on S1, S2, S3, a majority.
Suppose S1 marked X committed and then crashed. S5 could win term 5: its last log term is 3, which beats the term 2 on S2 and S3. It gets votes from S2, S3, S4. It then overwrites index 2 with Y everywhere. A "committed" entry is gone.
The fix: S1 counts replicas only for entries from its current term. Once a term-4 entry reaches a majority, S5 (last term 3) can no longer win an election. That commits X too, indirectly. This is also why a new leader appends a no-op entry right away.
7. Raft: Safety, Membership & Snapshots
The election restriction plus the commit rule together give Raft its central safety guarantee, the State Machine Safety Property: if any node has applied a log entry at a given index to its state machine, no other node will ever apply a different entry for that index. In other words, all state machines execute exactly the same commands in exactly the same order. Everything in §3–§4 exists to uphold this one line.
Membership changes
Adding or removing servers is dangerous because you cannot switch every node’s notion of “the cluster” atomically — during the switch, two different majorities could form (one under the old config, one under the new) and elect two leaders. Raft offers two safe approaches:
Joint consensus (the original). The cluster transitions through an intermediate configuration C<old,new> in which decisions require majorities from both the old and new configurations simultaneously. Because no decision can be made without overlap in both, no two disjoint majorities can form during the change. Once C<old,new> is committed, the cluster moves to C<new>.
Single-server changes (the common simplification). Add or remove exactly one node at a time. Changing membership by a single server can never create two disjoint majorities (the old and new majorities always overlap), so this avoids the joint-consensus machinery and is what most implementations use. One catch, found by Ongaro in 2015 after the paper: a new leader must commit an entry from its own term (the usual no-op) before it starts a configuration change. Without that, two overlapping single-server changes from different terms can still produce two leaders.
Log compaction with snapshots
A log that only ever grows will exhaust disk and make restarts slow. Snapshotting solves this: each node periodically writes its current state-machine state to a snapshot and discards all log entries up to that point. The snapshot records the lastIncludedIndex and lastIncludedTerm so the log-matching check still works at the boundary. If a follower is so far behind that the leader has already discarded the entries it needs, the leader ships the whole snapshot via an InstallSnapshot RPC instead of individual entries. Snapshotting is orthogonal to consensus — it is a space optimization — but it is essential for any long-running system.
8. Basic Paxos: Single-Decree
Basic Paxos decides one slot. A proposal has a globally ordered unique ballot number and a value. In phase 1, a proposer asks a quorum of acceptors to promise not to accept lower ballots; replies include each acceptor's highest accepted ballot/value. If any accepted value is reported, the proposer must carry the value from the highest reported accepted ballot, otherwise it may choose a new value.
In phase 2, acceptors persist an accepted proposal when it satisfies their promise. A value is chosen when a quorum accepts it; one acceptor accepting is not choosing. A learner knowing it is chosen is a separate event, and the original proposer may never receive its reply. Durable promises/accepted state and the phase-1 selection rule preserve chosen values. Multi-Paxos amortizes phase 1 under a stable leader and manages a log of slots; it still needs leadership, recovery, membership, and client dedup rules.
9. Worked Trace: Two Paxos Proposers
Three acceptors A1–A3, so a majority is 2. Proposer P1 wants X. Proposer P2 wants Y.
#
Message
Acceptor state after
1
P1: Prepare(1) → A1, A2. Both promise; nothing accepted yet.
A1, A2 promised 1
2
P1: Accept(1, X) → A1 arrives. The copy to A2 is delayed.
A1 accepted (1, X)
3a
P2: Prepare(2) → A2, A3. Neither has accepted anything.
A2, A3 promised 2
4a
P2 is free to use Y. Accept(2, Y) → A2, A3 both accept.
Now change one thing. In step 3, P2's Prepare(2) reaches A1 and A2 instead (call it 3b). A1 replies "I accepted (1, X)". P2 must propose X, not Y. Here X was never chosen: only A1 accepted it. But P2 cannot tell that apart from a case where it was. So it plays safe. Paxos may throw away your value, but it never picks two values.
10. Multi-Paxos: The Practical Form
Basic Paxos decides one value. A real system needs to decide an endless sequence of values — a replicated log, one Paxos instance per log slot. Running full two-phase Paxos for every entry would cost two round trips per command and invite dueling proposers. Multi-Paxos is the optimization that makes Paxos practical, and it converges on the same shape as Raft.
The key insight: elect a stable leader (a “distinguished proposer”) and let it skip Phase 1 in steady state. Here is why that is sound:
Phase 1 (Prepare/Promise) is fundamentally about acquiring the right to propose and learning about in-flight values. A proposer can run Phase 1 once, for a proposal number n, covering all future log slots at once — effectively “I am the leader for number n; promise me for every slot.”
Having done that, the leader replicates each new command with only Phase 2 (Accept(n, v) → Accepted) — a single round trip to a majority per entry, just like Raft’s AppendEntries.
Phase 1 is re-run only when leadership changes — a new would-be leader picks a higher number and prepares, which fences out the old leader (any acceptor that promised the new number will reject the old leader’s accepts). This is the same “higher number/term wins” fencing that Raft gets from terms.
In this steady state Multi-Paxos and Raft are near-isomorphic: a single leader, a monotonic epoch (proposal number / term), one round trip to a majority per commit, and re-election on leader failure. The historical difference is that Paxos left leader election, log management, and membership changes as exercises for the implementer — which is precisely the gap Raft filled by prescribing them. Production Paxos systems (Chubby, Spanner) build substantial machinery around Basic Paxos to get there; Raft bakes it in.
11. Raft vs Paxos
They solve the identical problem — agreement on a replicated log — with the identical quorum core (majority intersection). The differences are about structure and pedagogy, not power.
Dimension
Raft
(Multi-)Paxos
Design goal
Understandability; a complete, prescriptive spec
Minimal theoretical core; a proven safety kernel
Structure
Decomposed into election + log replication + safety
Single-decree kernel; log/leader left to the implementer
Leader
Strong leader; log flows leader → followers only
Distinguished proposer in Multi-Paxos; Basic Paxos is leaderless
Epoch mechanism
Terms (integer per election)
Proposal numbers (globally ordered)
Log restriction
New leader must have all committed entries (election restriction)
New proposer re-proposes any possibly-chosen value (Phase 1)
Steady-state cost
1 round trip to a majority per commit
1 round trip to a majority per commit (Phase 1 amortized)
A close cousin worth naming is ZAB (ZooKeeper Atomic Broadcast), which powers ZooKeeper. ZAB is not Paxos but solves the same problem with a leader-based, log-replication design very much in Raft’s spirit (a leader broadcasts totally-ordered transactions, epochs fence stale leaders). If asked “which should I use,” the honest answer is: reach for a battle-tested implementation (etcd/ZooKeeper) rather than writing your own — and if you must reason about one in an interview, explain Raft, because its structure maps directly to the guarantees.
12. Failure Modes
Protocol state must be durable even on negative/error reply paths that advanced a term or promise. For Raft AppendEntries, adopt and persist a higher term before replying rejection for a mismatched predecessor; candidates also become followers on valid same-term leader messages. Log conflicts never truncate committed history, and applied commit advancement cannot cover an unverified stale suffix.
Client timeout may leave a command committed even if its response was lost. Dedup client operation identity within the replicated state machine. Snapshots atomically represent committed applied state plus boundary index/term and membership; never compact uncommitted entries as if applied. Use a reviewed implementation rather than relying on illustrative RPC pseudocode as a complete protocol.
13. Tradeoffs
Choice
Gain
Cost
5 nodes instead of 3
Survives 2 failures
Quorum of 3; slightly slower commits; more hardware
Short election timeout
Faster failover
False elections during GC pauses or network blips
Lease reads
No round trip per read
Correctness depends on bounded clock drift
ReadIndex reads
Safe without clock assumptions
One heartbeat round per read batch
Replicas in 3 regions
Survives a region loss
Every commit pays a cross-region RTT
14. Practical Concerns & Summary
Consensus has a few operational realities that separate a textbook answer from a deployable one.
Reads without stale data. Writes go through the log, but naively serving a read from the leader can return stale data if that “leader” was silently deposed during a partition. Two standard fixes: a leader lease (the leader holds a time-bounded lease renewed by heartbeats, and only serves local reads while the lease is valid — correct only under bounded clock drift), or ReadIndex (the leader records its current commitIndex, confirms it is still leader by exchanging a heartbeat round with a majority, then serves the read once it has applied up to that index — safe without clock assumptions, at the cost of one round trip). Reads are otherwise the cheap operation; the write path is where consensus is paid for.
Latency is one round trip to a majority per commit. Every committed entry costs at least one RTT from the leader to the nearest majority (plus a durable write). Within a datacenter that is sub-millisecond; across regions it is tens of milliseconds — the cost detailed in the zero-data-loss guide. You reach the closest majority, so replica placement matters.
Size clusters odd. As §2 showed, an even number of nodes is wasteful — it enlarges the quorum without improving fault tolerance. Use 3, 5, or 7.
Scale by sharding. A single Raft/Paxos group has a single leader and therefore a write ceiling. Horizontal scale comes from partitioning the keyspace into many independent consensus groups (one leader each) — the model used by CockroachDB, TiKV, and Spanner.
Consensus is a coordination primitive, not a database. It is expensive; use it for the few things that truly need agreement (leader election, configuration, the commit order of critical data) and keep it off the bulk data path. This is exactly the distributed lock / leader election use case — a lock service is a thin veneer over a consensus group.
Concern
Mechanism
What is the problem?
Agree on one ordered log of commands across crashing nodes (replicated state machine).
Why is it hard?
FLP: no deterministic async protocol guarantees both safety and termination with one crash.
How do we escape FLP?
Assume partial synchrony; use timeouts/randomization for liveness — never for safety.
How do nodes agree safely?
Majority quorums — any two majorities intersect, so at most one value wins.
How many nodes?
2f + 1 tolerates f failures; use odd sizes (3, 5, 7).
How does Raft pick a leader?
Randomized election timeouts + RequestVote; a majority of votes wins one term.
When is a Raft entry committed?
On a majority and created in the leader’s current term; older entries commit indirectly.
How does a new leader stay safe?
Election restriction: only a candidate with an up-to-date log can win.
What does Basic Paxos do?
Prepare/Promise reserves a number and learns in-flight values; Accept/Accepted commits one value.
Why is Paxos safe?
A new proposer must re-propose any possibly-chosen value, so a decision is irreversible.
What makes Paxos practical?
Multi-Paxos: a stable leader skips Phase 1 in steady state — one round trip per entry.
How do reads avoid staleness?
Leader lease or ReadIndex to confirm leadership before serving.
The recurring theme: consensus is one round trip to a majority, made safe by the fact that any two majorities overlap and by an epoch (Raft term / Paxos number) that fences out stale leaders. Raft and Paxos are two spellings of the same idea — name FLP, name majority intersection, get the commit rule and the two Paxos phases exactly right, and you have said everything that matters.
Worked example: a majority and an old term
Five nodes have quorum size three; a new leader must handle inherited entries carefully.
Read top to bottom. The table below explains the state and guarantee at each step.
Step
State, calculation, and reasoning
1. Persist election state
Each node durably stores term and vote before replying, so reboot cannot let it vote twice in one term.
2. Elect a sufficiently up-to-date candidate
Compare last log term, then last index, under Raft's voting rule. Older leaders can remain unaware in earlier terms.
3. Commit a current-term entry
Advance commit by a durable majority only when the counted entry belongs to the leader's current term. Its preceding prefix commits indirectly.
4. Serve a linearizable read
Establish current leadership/quorum authority and wait for applied state (for example ReadIndex). An is_leader flag alone can serve stale data after partition.
Check your understanding: Does an old-term entry become committed merely because three nodes now store it?
A Raft leader cannot use replica count alone to newly commit an old-term entry. Commit a current-term entry and its prefix, following the full log/election rules.
Run a small, testable model
Download concepts.py. It uses only the Python 3.10+ standard library. From the directory where you saved it, run:
python3 concepts.py quorum
python3 concepts.py test
The finite model enumerates majority overlap and demonstrates how the current-term condition differs from simple replica counting. It is not a Raft implementation.
The program contains deterministic assertions and failure traces. It is a learning model, not a production service: it does not implement network consensus, distributed durability, authentication, or third-party delivery. Read its contracts and try changing an input before extending it.
They rarely want the full algorithm. They want the few ideas that make it safe, and proof that you know where it hurts.
"Why a majority?" Any two majorities overlap, so two leaders or two values cannot both win.
"When is an entry committed?" On a majority and from the leader's current term. Mention Figure 8.
"How do you read safely?" ReadIndex or leases, plus the clock assumption that leases need.
"How do you scale writes?" Shard into many groups (multi-Raft), each with its own leader.
"Where would you use it?" Metadata, locks, leader election and config. Not for bulk data.
16. Common Mistakes
Calling Raft crash-stop. It is crash-recovery, and it needs persisted term, vote and log.
Committing an old-term entry just because it is on a majority. That is the Figure 8 bug.
Serving reads from "the leader" with no check. A deposed leader can serve stale data.
Thinking an even cluster helps. Four nodes tolerate one failure, same as three.
Believing timeouts affect safety. Timing only affects liveness. Bad timeouts slow things down but never cause disagreement.
17. Check Yourself
A 5-node Raft cluster loses 2 nodes. Can it still commit? What about losing 3?
Answer
With 2 lost, 3 remain, which is a majority of 5, so it commits. With 3 lost, only 2 remain. That is not a majority, so it stops accepting writes. It stays safe but is unavailable.
Why must a Raft node write votedFor to disk before replying to RequestVote?
Answer
If it voted, crashed and forgot, it could vote again for a different candidate in the same term. Two candidates could then each reach a majority, giving two leaders in one term.
Only the verified uncommitted conflicting suffix may be removed. Leader completeness ensures a valid elected leader retains all committed entries under the full election/commit rules. A raw majority count or whether this client saw an ACK is not the definition of committed.
Only after collecting a valid phase-1 quorum, propose the value with highest accepted ballot among that quorum's replies; if no accepted value exists, choose a new value. With fewer than a quorum of promises, the proposer cannot safely move to phase 2 merely because one acceptor reported X.
Why is commitIndex = min(leaderCommit, last_index()) wrong on a follower?
Answer
The follower may still hold stale entries past what this RPC checked, for example on an empty heartbeat. Committing up to its own last index could apply entries that differ from the leader's. Use the index of the last entry this RPC verified: prevLogIndex + len(entries).
A network blip lasts 400 ms, and your election timeout is 150–300 ms. What happens, and how would you tune it?
Answer
Followers time out and start elections, so leadership moves for no real reason. Writes pause during each election. Raise the timeout above common blips and GC pauses, and use PreVote and CheckQuorum to avoid disruptive elections.
18. Key Terms
Replicated state machine
Same commands, same order, same state on every node.
Quorum
A set of replicas whose responses are sufficient for an operation. In a fixed set of N replicas, read size R and write size W overlap whenever R+W>N. A majority is one particular quorum, not the definition of every quorum. Example and limits above.
Term / ballot
A rising number that marks the leader's epoch.
commitIndex
The highest log index known to be committed.
nextIndex / matchIndex
The leader's per-follower send and match positions.
Election restriction
Vote only for a candidate whose log is at least as up to date.
FLP
Async consensus cannot guarantee termination with one crash.
ReadIndex
Confirm leadership with a majority before serving a read.
PreVote
A trial election that does not raise the term.
19. Further Reading
Diego Ongaro and John Ousterhout, "In Search of an Understandable Consensus Algorithm", USENIX ATC 2014. The paper and a visual demo are at raft.github.io.
Diego Ongaro, Consensus: Bridging Theory and Practice, PhD thesis, Stanford 2014 (PreVote, membership changes, ReadIndex).
Leslie Lamport, "Paxos Made Simple", ACM SIGACT News, 2001.
Fischer, Lynch and Paterson, "Impossibility of Distributed Consensus with One Faulty Process", Journal of the ACM, 1985.
Chandra, Griesemer and Redstone, "Paxos Made Live: An Engineering Perspective", PODC 2007.
Martin Kleppmann, Designing Data-Intensive Applications, ch. 9 "Consistency and Consensus".