A system design interview guide to handing out identifiers that are unique across every machine in a distributed system, without a central bottleneck, while staying small, numeric, and roughly ordered by time.
Student edition · start with the guarantee
Encode distributed IDs while separating uniqueness, approximate timestamp order, and safe restart behavior.
Correctness contract: No two issued IDs collide within the documented bit horizon and worker-ownership/restart model. A failed wait must not consume or reset generation state.
Basic HTTP, databases, and programming are assumed. Specialized terms are explained below. Named products motivate the problem; this is an educational design, not a claim about their current internals. Capacity numbers are illustrative decimal payload estimates, not benchmarks. Add indexes, protocol overhead, replicas, headroom, and failure capacity before provisioning.
Distributed ID allocation separates uniqueness, ordering, and availability. A counter can use replicated authority and range allocation; it is not inevitably a single point of failure or a per-ID bottleneck. Snowflake trades coordination frequency for strict worker identity, clock, sequence, restart, and horizon requirements.
Each definition includes a concrete example and the condition under which the mechanism is useful. You can read this guide without opening another guide.
Snowflake IDs
An integer encoding of a timestamp, worker identity, and per-timestamp sequence. One common 64-bit layout reserves a sign bit, 41 time bits, 10 worker bits, and 12 sequence bits.
Example. A worker can encode 4096 distinct sequence values in one millisecond. The 41-bit millisecond field spans about 69.7 years from the chosen epoch.
Limit. This is encoding capacity, not measured throughput or global causal order. Unique worker ownership, restart-safe sequence state, clock rollback, horizon checks, and JavaScript integer precision must be handled.
Wall and monotonic clocks
A wall clock maps to civil/epoch time and can jump because of correction. A monotonic clock measures elapsed time locally without wall-clock jumps, but its origin is not a shared global epoch.
Example. Use an epoch timestamp to label an event and a monotonic deadline to bound how long a process waits for the next usable timestamp.
Limit. Neither establishes causal order across machines. Monotonic readings cannot be compared between hosts or assumed to survive reboot with the same origin.
Leases
Time-limited permission issued by an authority. Expiry lets new work proceed after a client stops renewing; it does not prove that the previous holder is dead or unable to act.
Example. A 30-second lease expires while A is paused for 45 seconds. B can acquire a new lease, but A can still wake up and send a delayed write.
Limit. Heartbeats improve recovery time, not safety by themselves. Compare-and-renew/delete must verify a unique acquisition token atomically, and protected effects need fencing or equivalent serialization.
Fencing tokens
A strictly increasing grant number attached to operations. The protected resource atomically compares it with its durable highest accepted token and rejects older operations, making superseded clients unable to overwrite newer effects.
Example. A has token 33 and pauses. B acquires 34 and writes. When A sends token 33 later, the resource rejects it because its fence is already 34.
Limit. A new grant must be installed at the resource before it promises exclusion there. Token 33 can still pass until 34 is observed. Equal-token operations also need sequence/idempotency rules if they can arrive out of order.
Optimistic concurrency and compare-and-set
Update state only if the expected version or status still matches, in the same atomic operation that changes it. A failed comparison means a conflicting operation won; reread or return a conflict.
Example. UPDATE seats SET status='held', version=version+1 WHERE id=? AND status='available' allows only one concurrent claimant to update the row.
Limit. Application-level GET then unconditional SET is not equivalent. Include acquisition identity to reject stale callbacks, and couple related invariants in a transaction.
1. Requirements
Before choosing a design, pin down what an ID actually has to satisfy. In an interview these constraints are what justify ruling out simpler options, so state them explicitly.
Requirement
Why it matters
Unique
No two IDs may ever collide, across all machines and data centers, for the life of the system. This is the non-negotiable property.
Numeric
IDs should be numeric values only. Numeric IDs index efficiently, compare cheaply, and avoid the size and parsing cost of strings.
Fits in 64 bits
An ID must fit in a 64-bit integer. That keeps it compact in storage, in indexes, and on the wire, and it is a natural size for languages and databases to handle.
Sortable by time
Ideally, IDs generated later sort higher than IDs generated earlier. Time-ordered IDs make range scans, pagination, and "most recent" queries cheap.
High throughput
The system should be able to mint a large number of IDs per second (a typical interview number is at least 10,000 per second overall) without coordination on the hot path.
Highly available
If one generator dies, the others keep minting. No single machine can stop the whole system from creating records.
The "sortable by time" requirement is the one that quietly drives the whole design. If you did not care about ordering, a random number might seem enough. But 64 random bits are too few: by the birthday paradox, after one billion IDs the chance that some pair collides is about 2.7%. That is why purely random IDs use 122 bits or more (UUID v4). Wanting IDs to increase with time is what pushes you toward encoding a timestamp directly into the ID.
Clarifying questions to ask first: How many IDs per second at peak? How many data centers and generator machines? Must IDs be strictly increasing, or is “roughly by time” enough? Can an ID reveal anything (creation time, volume)? Will IDs be used in JavaScript clients?
2. Back-of-the-Envelope Estimation
Quantity
Working
Result
Required rate
given in the requirements
10,000 IDs/s
Per-node capacity (12-bit sequence)
4,096 per ms × 1,000 ms
4,096,000 IDs/s
Whole-cluster capacity
4,096,000 × 1,024 nodes
~4.2 billion IDs/s
Timestamp range
241 ms ÷ (1000 × 3600 × 24 × 365.25)
~69.7 years
Overflow date with epoch 2020-01-01
2020-01-01 + 241 ms
2089-09-06
Headroom
One node alone covers the requirement 400× over; extra nodes are for availability, not speed.
>400×
What the numbers tell you
Throughput is not the hard part. The hard parts are keeping IDs unique when clocks misbehave and making sure no two nodes ever share a machine ID.
3. Approaches and Their Drawbacks
There are several well-known ways to generate IDs in a distributed setting. Each makes a different trade, and walking through why the first three fall short is the cleanest way to motivate the fourth.
Approach
How it works
Drawbacks
Multi-master replication
Use several database servers, each with auto_increment, but have each one increment by k (the number of servers) instead of by 1, with a different starting offset per server. Server 1 yields 1, 4, 7, ...; server 2 yields 2, 5, 8, ...; and so on, so no two servers ever produce the same number.
Hard to scale across multiple data centers, since the offsets must be coordinated globally. It does not scale well when servers are added or removed: changing k reshuffles every server's step, and IDs are not sortable by time across servers.
UUID
Each server independently generates a 128-bit Universally Unique Identifier. With enough random bits the chance of a collision is negligible, and no coordination between servers is needed at all.
A UUID is 128 bits, but the requirement is 64 bits, so it does not fit. The common v4 UUID is random, so it is not time-ordered and it scatters inserts across a B-tree index. (The newer UUID v7 from RFC 9562 puts a millisecond timestamp first and is time-ordered, but it is still 128 bits.) UUIDs are usually rendered as a hex string with hyphens.
Ticket server
Run a single, central database whose sole job is to hand out the next number from one auto_increment counter. Every service that needs an ID asks this one server.
The ticket server is a single point of failure: if it goes down, no one can mint IDs anywhere. It is also a central bottleneck for throughput. Running multiple ticket servers to fix this reintroduces the multi-master coordination problem. (Flickr ran exactly this: two ticket servers, one handing out odd numbers and one even.) A common improvement is to hand out ranges: each app server grabs a block of, say, 1,000 IDs in one call and serves them from memory. That cuts load on the ticket server by 1,000×, but IDs from different servers interleave, so they are no longer ordered by time.
Snowflake
Each node generates IDs locally by packing a timestamp, the node's own identity, and a per-millisecond sequence counter into a single 64-bit number. No network call is needed to mint an ID.
Few, for these requirements — which is why it is the chosen approach. It is distributed, time-sortable, and 64-bit. Its one real subtlety is dependence on the node clock, covered later.
The pattern across the first three is a tug-of-war between coordination and independence. Multi-master and the ticket server stay correct by coordinating, which limits scaling and creates bottlenecks. UUIDs avoid coordination entirely but pay for it in size and the loss of ordering. Snowflake threads the needle: it needs no coordination on the hot path, yet still produces compact, ordered, numeric IDs.
4. The Snowflake Approach
The key insight behind Snowflake (originally from Twitter) is to divide and conquer the 64 bits. Instead of treating an ID as one opaque counter, you partition the bits into sections, and let a different source of uniqueness fill in each section. As long as the combination of all sections is unique, the whole ID is unique — and crucially, each section can be filled in locally, with no call to a central server.
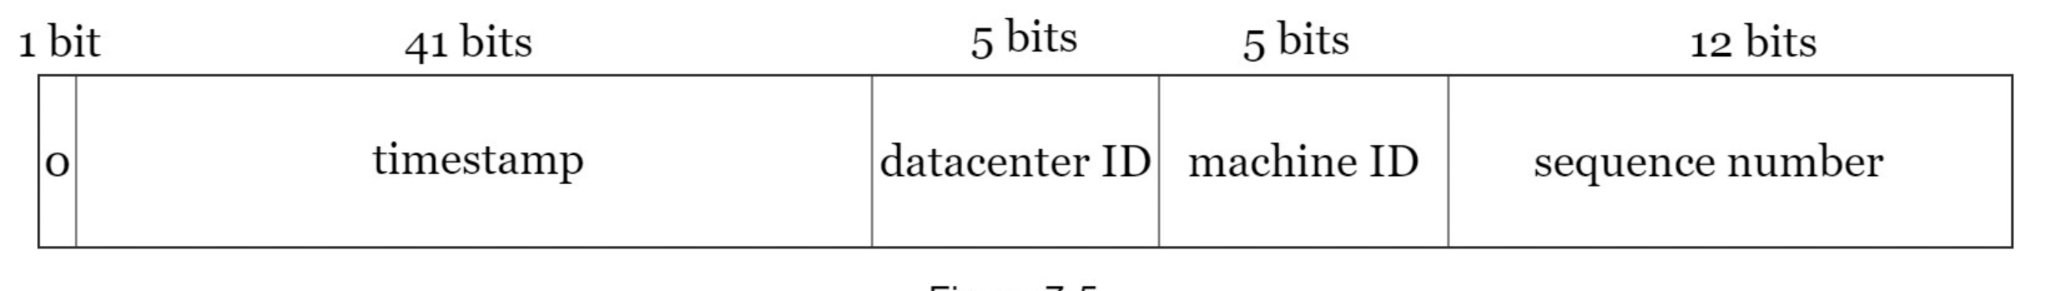
The 64-bit Snowflake layout: 1 sign bit (always 0), 41 bits of timestamp, 5 bits of data center ID, 5 bits of machine ID, and a 12-bit sequence number. The high-order timestamp bits make the ID roughly sortable by time.
Reading the layout from the most significant bit to the least:
A zero sign bit yields a nonnegative signed integer, including zero. The layout's timestamp/worker/sequence combination is unique only if those fields are allocated without reuse under the stated restart and worker-ownership model.
The timestamp (41 bits) sits in the high-order positions. Because it is the most significant field, IDs naturally sort by time: a later timestamp produces a numerically larger ID.
The data center ID (5 bits) and machine ID (5 bits) together identify the exact node that produced the ID. They make IDs from different nodes unique even when those nodes generate at the same millisecond.
The sequence number (12 bits) distinguishes IDs produced by the same node within the same millisecond.
Two correctly allocated timestamp/worker/sequence tuples differ, but duplicated worker assignment, clock/sequence reuse, or unsafe restart can repeat every field. The allocation preconditions, not the encoding alone, guarantee uniqueness.
# Use the complete bounded-wait Python model below.
# Preconditions: exclusive worker identity, safe restart/nonreuse, finite horizon.
value = generator.next_id()
# On rollback/exhaustion timeout, state remains unchanged.
# Approximate timestamp order is not a delivery cursor or global causal order.
Here is a complete, runnable version in Python. It checks for a backward clock, handles the sequence running out, and includes a decoder:
import math, threading, time

def pack_id(elapsed_ms, worker, sequence):
    """Encode the 41/10/12 unsigned fields. Not an allocator: callers must
    ensure exclusive worker ownership and restart-safe nonreuse of field tuples."""
    for value, bits in ((elapsed_ms, 41), (worker, 10), (sequence, 12)):
        if type(value) is not int or not 0 <= value < 1 << bits:
            raise ValueError(f"integer field must fit {bits} bits")
    return (elapsed_ms << 22) | (worker << 12) | sequence

class Snowflake:
    """Bounded-wait, single-process model. Pre: this worker is exclusively
    owned and no previous process used these timestamp/sequence tuples.
    NOT restart-safe: production allocation must enforce those preconditions.
    State changes only after a valid tuple can be returned; failures preserve it.
    """
    def __init__(self, worker, epoch_ms=1577836800000, wall_ms=None,
                 monotonic=time.monotonic, pause=time.sleep, wait_seconds=0.01):
        pack_id(0, worker, 0)  # validate worker, not an optimizable assert
        if type(epoch_ms) is not int or not math.isfinite(wait_seconds) or wait_seconds <= 0:
            raise ValueError("integer epoch and finite positive wait required")
        self.worker, self.epoch = worker, epoch_ms
        self.wall = wall_ms or (lambda: time.time_ns() // 1_000_000)
        self.monotonic, self.pause, self.wait = monotonic, pause, wait_seconds
        self.last, self.sequence = -1, 0
        self.lock = threading.Lock()

    def next_id(self):
        with self.lock:
            deadline = self.monotonic() + self.wait
            target = self.last + (self.sequence == 4095)
            # Invariant: generation state is unchanged until a valid tuple exists.
            # Bound: at most 1000 polls, also bounded by a local elapsed deadline.
            for _ in range(1000):
                timestamp = self.wall() - self.epoch
                pack_id(timestamp, self.worker, 0)  # timestamp horizon/type
                if timestamp >= target:
                    sequence = self.sequence + 1 if timestamp == self.last else 0
                    value = pack_id(timestamp, self.worker, sequence)
                    self.last, self.sequence = timestamp, sequence
                    return value
                remaining = deadline - self.monotonic()
                if remaining <= 0:
                    break
                self.pause(min(remaining, 0.0001))
            raise TimeoutError("clock rollback or exhausted millisecond; state unchanged")

def decode(value):
    if type(value) is not int or not 0 <= value < (1 << 63):
        raise ValueError("nonnegative signed-63-bit ID required")
    return {"ms_since_epoch": value >> 22, "datacenter": (value >> 17) & 31,
            "machine": (value >> 12) & 31, "sequence": value & 4095}

# Demo only: exclusive worker ownership and a fresh process are assumed.
generator = Snowflake(worker=(3 << 5) | 7)
values = [generator.next_id() for _ in range(10_000)]
assert len(set(values)) == len(values) and values == sorted(values)
print("Single-process uniqueness/order checks pass; restarts need durable allocation.")
Decoding by hand: the ID 517815304351786 splits into 517815304351786 >> 22 = 123456789 ms after the epoch, data center 3, machine 7, and sequence 42.
5. Snowflake Fields and the Math
Each field's bit width sets a concrete limit. Working through the arithmetic shows why these particular sizes are a sensible default, and what each one buys you.
Field
Bits
Range and meaning
Sign bit
1
Always zero in this layout, giving a nonnegative signed integer (including zero).
Timestamp
41
Milliseconds since a custom epoch chosen by the system, not the Unix epoch. 41 bits hold 241 milliseconds ≈ 69 years of range, so the generator can run for about 69 years from its epoch before the field overflows.
Data center ID
5
25 = 32 data centers.
Machine ID
5
25 = 32 machines per data center. Combined with the data center ID, that is 32 × 32 = 1024 nodes total.
Sequence number
12
212 = 4096 IDs per millisecond per node. Resets to 0 at the start of each new millisecond.
The layout offers 4096 sequences per millisecond per worker and 1024 workers: a bit-space ceiling of about 4.19 billion encoded tuples/s across workers, not measured throughput. Compute, locks, clock granularity, and allocation safety determine real capacity.
Timestamp-ID order can support approximate chronological range queries, but a highest-seen ID is not a safe delivery/commit cursor: a late commit with a smaller ID may be skipped. Use an ordered committed stream and a contiguous cursor for reliable replay.
If your throughput needs are lower but you have more nodes, you can re-budget the bits — for example, fewer sequence bits and more machine-ID bits. The 41/5/5/12 split is a default, not a law. The only fixed parts are the single sign bit and the total of 64.
6. Assigning Machine IDs Safely
The 10 worker bits in the common layout provide 1024 identities, not automatic allocation. Use a configured exclusive assignment or a durable coordinator. Do not recycle an ID just because its previous lease expired: the old process may be paused and can still generate IDs when it resumes.
A safe allocation scheme needs a documented incarnation/fencing rule plus prevention of timestamp/sequence reuse. Options include a larger incarnation field, durable range reservations, or a persisted high-water mark that the new holder waits strictly beyond. The uniqueness contract must include crash ordering: record a reservation durably before issuing any ID from it. A local saved timestamp without sequence or strict restart waiting is not enough.
A coordinator's lease is a liveness mechanism. It cannot instantly stop local ID issuance by a frozen holder; downstream token checks can reject old effects but cannot erase duplicate IDs that have already escaped.
7. Clock Skew and Rollback
Wall time may move backward, and its millisecond epoch field has a finite horizon. Validate worker fields and 0 ≤ elapsed_ms < 2^41 with explicit exceptions, not assertions that Python can disable. Use a monotonic deadline to bound any waiting; a local monotonic reading is not a globally shared timestamp epoch.
On rollback or sequence exhaustion, either wait within that bound or fail without changing the last issued timestamp/sequence. Never reset the sequence early and then return an error after a timeout. A production implementation must also handle process restart at an already-used timestamp and concurrent calls with serialization.
The sign bit set to zero yields a nonnegative integer, including zero. The 4096 IDs/ms/worker figure is the bit-space ceiling, not measured Python throughput. A finite 64-bit space cannot promise unlimited-lifetime uniqueness. The epoch, timestamp horizon, throughput, and worker reuse policy must be explicit.
8. Tradeoffs and Alternatives
Scheme
Size
Time-ordered?
Coordination
Notes
DB auto-increment
64-bit
Yes (one server)
Every insert
Simple; one database is the limit
Ticket server (with ranges)
64-bit
Only within a range
Once per block
Flickr's approach; simple and compact
UUID v4
128-bit
No
None
Random; bad index locality
UUID v7 / ULID
128-bit
Yes (ms)
None
Timestamp prefix plus random bits; good default if 128 bits is fine
Snowflake
64-bit
Roughly
Only to assign machine IDs
Twitter; also Discord and others use variants
Instagram-style (in the database)
64-bit
Roughly
None beyond sharding
41 bits time + 13 bits logical shard + 10 bits sequence, generated by a stored procedure in each Postgres shard
Worked example: one millisecond, two workers, one restart
Use a small sequence space to make exhaustion and reuse visible.
Read top to bottom. The table below explains the state and guarantee at each step.
Step
State, calculation, and reasoning
1. Allocate a worker identity
Workers 3 and 7 must be exclusively owned. A random worker number without collision handling is not a uniqueness guarantee.
2. Issue IDs within one millisecond
A timestamp and worker pair must use distinct sequence values. Exhaustion waits for a strictly later usable millisecond or returns an explicit bounded-time error.
3. Restart at the same timestamp
Resetting sequence to zero can repeat an already-issued ID. Persist/reserve a safe high-water mark before issue, or delay until beyond it; merely saving the last timestamp after sending is insufficient.
4. Serialize to a browser
An ID above 2^53−1 must not travel as a JavaScript Number if exactness matters. Send a decimal string or use a BigInt-aware protocol.
Check your understanding: Does a time-sortable ID prove that one event caused another?
No. Clock skew, concurrent issuance, and delayed delivery break that interpretation. Use logical dependencies or committed stream sequence for causal/order guarantees.
Run a small, testable model
Download concepts.py. It uses only the Python 3.10+ standard library. From the directory where you saved it, run:
python3 concepts.py ids
python3 concepts.py test
The model checks field bounds and encoding/decoding, and demonstrates why a restarted timestamp/sequence pair repeats an ID. It is not a restart-safe allocator.
The program contains deterministic assertions and failure traces. It is a learning model, not a production service: it does not implement network consensus, distributed durability, authentication, or third-party delivery. Read its contracts and try changing an input before extending it.
Clarify: size limit, ordering, rate, number of data centers, JS clients.
5–15 min
List the approaches and why each simple one fails a requirement.
15–25 min
Draw the 64-bit layout. Do the math: 69 years, 1,024 nodes, 4,096 per ms.
25–35 min
Walk through next_id(): sequence overflow, waiting for the next ms.
35–45 min
Deep dives: clock rollback, machine-ID assignment, restarts, re-budgeting bits.
10. Common Mistakes
Two nodes with the same machine ID. Every other safeguard is useless if this happens.
Using the Unix epoch. It wastes about 50 years of the 41-bit range on the past.
Sending 64-bit IDs to JavaScript as numbers. JS numbers are exact only up to 253 ≈ 9.0 × 10¹⁵. Larger IDs get silently rounded. Send them as strings too (Twitter's API added an id_str field for this reason).
Claiming strict global ordering. Across nodes, IDs are only roughly ordered, and clock skew between nodes makes it rougher.
Forgetting IDs leak information. Anyone can decode the creation time, and sequential IDs reveal how many records you create. If that matters, do not expose raw IDs, or use random IDs for public URLs.
11. Summary
Designing a unique ID generator is an exercise in getting global uniqueness without global coordination. Snowflake achieves it by partitioning 64 bits so each part can be filled in locally.
Concern
How the design addresses it
What must an ID be?
Unique, numeric, 64-bit, sortable by time, mintable at high throughput.
Why not multi-master auto_increment?
Hard to scale across data centers and does not handle servers being added or removed cleanly.
Why not UUID?
128 bits (not 64), not time-ordered, and often non-numeric.
Why not a ticket server?
Single point of failure and a central throughput bottleneck.
Why Snowflake?
Distributed, time-sortable, and fits in 64 bits, with no coordination on the hot path.
How are the 64 bits used?
1 sign + 41 timestamp + 5 data center + 5 machine + 12 sequence.
What do the field sizes buy?
~69 years of timestamps, up to 1024 nodes, and 4096 IDs per millisecond per node.
What is the main risk?
Clock skew or rollback; mitigated by refusing to go backwards, waiting, NTP, and failing loudly on large jumps.
What else can break uniqueness?
Two nodes sharing a machine ID, or a restart that forgets the last timestamp. Assign IDs with leases and persist or wait on startup.
The recurring theme: split the problem so uniqueness comes from a combination of independent fields, encode time in the high bits to get ordering for free, and treat the local clock as the one thing that needs guarding. Everything else follows from those three choices.
12. Check Yourself
How many years does a 41-bit millisecond timestamp last, and why use a custom epoch?
Answer
241 ms ≈ 69.7 years. Counting from a recent date means the whole range lies in the future instead of wasting decades since 1970.
You need 4,000 generator machines but only 500 IDs per millisecond per node. How could you re-budget the 22 non-time bits?
Answer
4,000 nodes need 12 bits (4,096). That leaves 10 bits of sequence = 1,024 per ms, which covers 500. So use 41 time + 12 node + 10 sequence (+1 sign).
Decode the ID (1000 << 22) | (2 << 17) | (5 << 12) | 9.
Answer
Timestamp 1,000 ms after the epoch, data center 2, machine 5, sequence 9.
A node's clock jumps back by 2 seconds while it is running. What should the generator do, and why?
Answer
Refuse to use the old timestamps. 2 s is probably above the tolerance, so raise an error and leave rotation instead of blocking for 2 s or risking duplicates.
Why is a random 64-bit ID risky at one billion IDs, while a 122-bit random UUID is fine?
Answer
Birthday bound: about n²/(2·2b). For b = 64 that is about 2.7% chance of some collision. For b = 122 it is about 10-19.
Why can two IDs made 0.3 ms apart on different nodes sort in the “wrong” order?
Answer
Within one millisecond, the lower bits are ordered by node ID and sequence, not by the true instant. Clock skew between nodes can also shift them by a few ms.
13. Key Terms
Snowflake ID
A 64-bit ID made of timestamp, node ID and sequence number.
Custom epoch
The chosen “time zero” that the timestamp counts from.
Sequence number
A counter that separates IDs made in the same millisecond on one node.
Clock skew
Clocks on different machines disagreeing, or one clock jumping.
NTP
Network Time Protocol, which keeps machine clocks in sync.
Monotonic clock
A clock that never goes backwards, good for measuring intervals.
Ticket server
A central counter service that hands out the next ID or block of IDs.
UUID v4 / v7
128-bit IDs: v4 is random, v7 starts with a millisecond timestamp.
Birthday paradox
Collisions become likely after about √(2b) random b-bit values.
14. Further Reading
Twitter engineering blog, “Announcing Snowflake” (2010), and the original open-source Snowflake repository.
Instagram engineering, “Sharding & IDs at Instagram” (2012).
Flickr (code.flickr.com), “Ticket Servers: Distributed Unique Primary Keys on the Cheap” (2010).