A system design interview guide to counting distinct identifiers — daily and monthly active users, unique ad reach — across billions of events, when keeping the exact set of every id in memory is no longer affordable.
Student edition · start with the guarantee
Estimate distinct active users cheaply and understand why merging sketches is different from adding daily counts.
Correctness contract: Compatible sketch union reproduces the sketch of the combined ID set; the resulting cardinality estimate remains approximate and cannot answer individual membership.
Basic HTTP, databases, and programming are assumed. Specialized terms are explained below. Named products motivate the problem; this is an educational design, not a claim about their current internals. Capacity numbers are illustrative decimal payload estimates, not benchmarks. Add indexes, protocol overhead, replicas, headroom, and failure capacity before provisioning.
"How many distinct users did we see today?" sounds like a one-line question, and at small scale it is: drop every user id into a set and read off its size. The trouble starts when "today" means tens of billions of events and the answer has to cover dozens of audiences, time windows, and breakdowns at once. A set that remembers every id it has ever seen grows in lockstep with the number of distinct ids, and at a billion ids that set is gigabytes — per metric, per window. The interesting design problem is not the counting itself but how to count distinctly without paying for memory that scales with the answer. This guide builds up from the naive set to probabilistic cardinality estimation, the property that makes it composable across shards and time, and the architecture that ties it together.
Each definition includes a concrete example and the condition under which the mechanism is useful. You can read this guide without opening another guide.
HyperLogLog
A fixed-size sketch for estimating distinct values. Hashed IDs select registers; each register retains the largest observed leading-zero rank. A bias-corrected harmonic estimate turns those extrema into a cardinality estimate.
Example. Two compatible sketches merge by element-wise maximum. That produces exactly the sketch of the union, while its final count remains approximate. At 16,384 packed six-bit registers, the relative standard error is about 0.81%.
Limit. Error is statistical, not a hard per-dataset bound. You cannot remove an individual ID or ask membership. Python lists do not actually pack registers into 12 KiB.
Cardinality
The number of distinct identities a store must track. A metric series is its metric name plus the full label combination. The product of label-value counts is an upper bound when not every combination occurs.
Example. 100 hosts × 20 routes × 5 status codes can produce up to 10,000 series. Adding a unique request_id can make every request create a new series.
Limit. Hashing every ID to a distinct digest does not reduce cardinality or guarantee anonymity. Use bounded categories, explicit limits, or intentional fixed-bucket aggregation.
Event time and watermarks
Event time is when the producer says an event happened; processing time is when a consumer handles it. A watermark is the processor's policy-driven estimate of event-time progress, used to emit and eventually clean up window state.
Example. An event for 12:00 arrives at 12:07. A 5-minute allowed-lateness policy may update its window, divert it to correction, or reject it according to the API contract.
Limit. Watermarks are not proof all earlier events arrived. Idle inputs, skew, and unbounded delay require explicit policies; later corrections must propagate to rollups and reports.
Offsets and checkpoints
An offset is a position in one log partition. A checkpoint is a recoverable, consistent record of input positions and processing state. On restart, state must correspond exactly to the input that is considered processed.
Example. If a batch increments a total and crashes before saving its offset, replay increments twice. Commit the total, dedup state, and partition position together, or use a compatible transactional/idempotent sink.
Limit. Saving an offset after a write avoids that specific loss window but can still duplicate; framework checkpoints alone do not make arbitrary external effects transactional.
Deduplication
Recognizing multiple deliveries of one logical event using a stable identity. The same logical event must keep its ID across retries, and claiming the ID must be atomic with the counted or stored effect.
Example. Events e1,e2,e1 should yield a count of 2. An exact seen set plus the increment in one transaction makes the second e1 a no-op.
Limit. A TTL limits the dedup horizon; retries after expiry may count again. Approximate filters may drop new events, and changing the ID or routing a retry to another local seen set defeats dedup.
1. The Distinct-Count Problem
The core operation is cardinality: given a stream of identifiers with arbitrary repeats, report how many different ones appeared. This is fundamentally harder than a plain count, because a plain count just needs a running integer — you never have to remember which ids you have already seen. Distinct counting does: to avoid counting the same user twice, something has to recognise that this id has shown up before.
The metrics that ride on this operation are everywhere in a consumer product:
DAU and MAU — daily and monthly active users, the headline engagement numbers, are distinct counts of user ids over a one-day and a rolling thirty-day window.
Unique reach — how many distinct people an ad or campaign actually touched, as opposed to total impressions, which double-count anyone who saw it more than once.
Distinct visitors per page, per region, per cohort — the same operation sliced many ways, which multiplies the number of independent counts you have to maintain.
Two things make this expensive at scale. First, the stream is enormous and unbounded, so any approach that touches every event has to be cheap per event. Second, you rarely want a single global number; you want the count for many overlapping audiences and windows, and each one is its own distinct-count problem. A solution that costs gigabytes for one metric does not survive being multiplied by hundreds of slices.
The reframing for an interview: you are not asked to count, you are asked to count distinctly — and the cost of distinctness is memory that, done naively, scales with the answer. Every technique below is about breaking that link so memory stays flat while the count grows.
2. Requirements and Clarifying Questions
"Count unique users" sounds like one number. In practice it is thousands of numbers, and the questions below decide whether an exact design is even possible.
Which windows? Day only, or also week, 30-day rolling, and any custom range? (Assume day, week, rolling 30-day, and ad-hoc ranges.)
Which slices? Global only, or by country, platform, app version, campaign? (Assume about 1,000 slices.)
How exact? Is a 1% error OK for dashboards? Is anything billed on it? (Assume dashboards only; 1% is fine.)
How fresh? Is today's DAU needed live, or next morning? (Assume live, within a minute.)
Membership too? Do we ever need "was user X active?" (Assume no; that is a different system.)
Functional
Non-functional
Ingest activity events with a user id and dimensions.
Handle about 870,000 events per second at peak.
Return distinct users for any metric, slice, and time range.
Relative error about 1% or better.
Combine counts across shards and windows without double counting.
Query latency under 100 ms; storage small enough to keep years of history.
3. Back-of-the-Envelope Estimation
Assume 500 million daily active users, each producing about 50 events a day, 1,000 slices, and a 3× peak.
The exact design needs tens of gigabytes per day before hash-table overhead (often 2–4× more), and a 30-day MAU would need a 30-way set union. The sketch design keeps two years of history in the space of one day of exact sets.
4. Why an Exact Set Blows Up
The exact answer is conceptually trivial: maintain a hash set, insert every id, and the cardinality is the set's size. It is also correct to the last unit. The problem is purely one of resources, and it shows up the moment the number of distinct ids gets large.
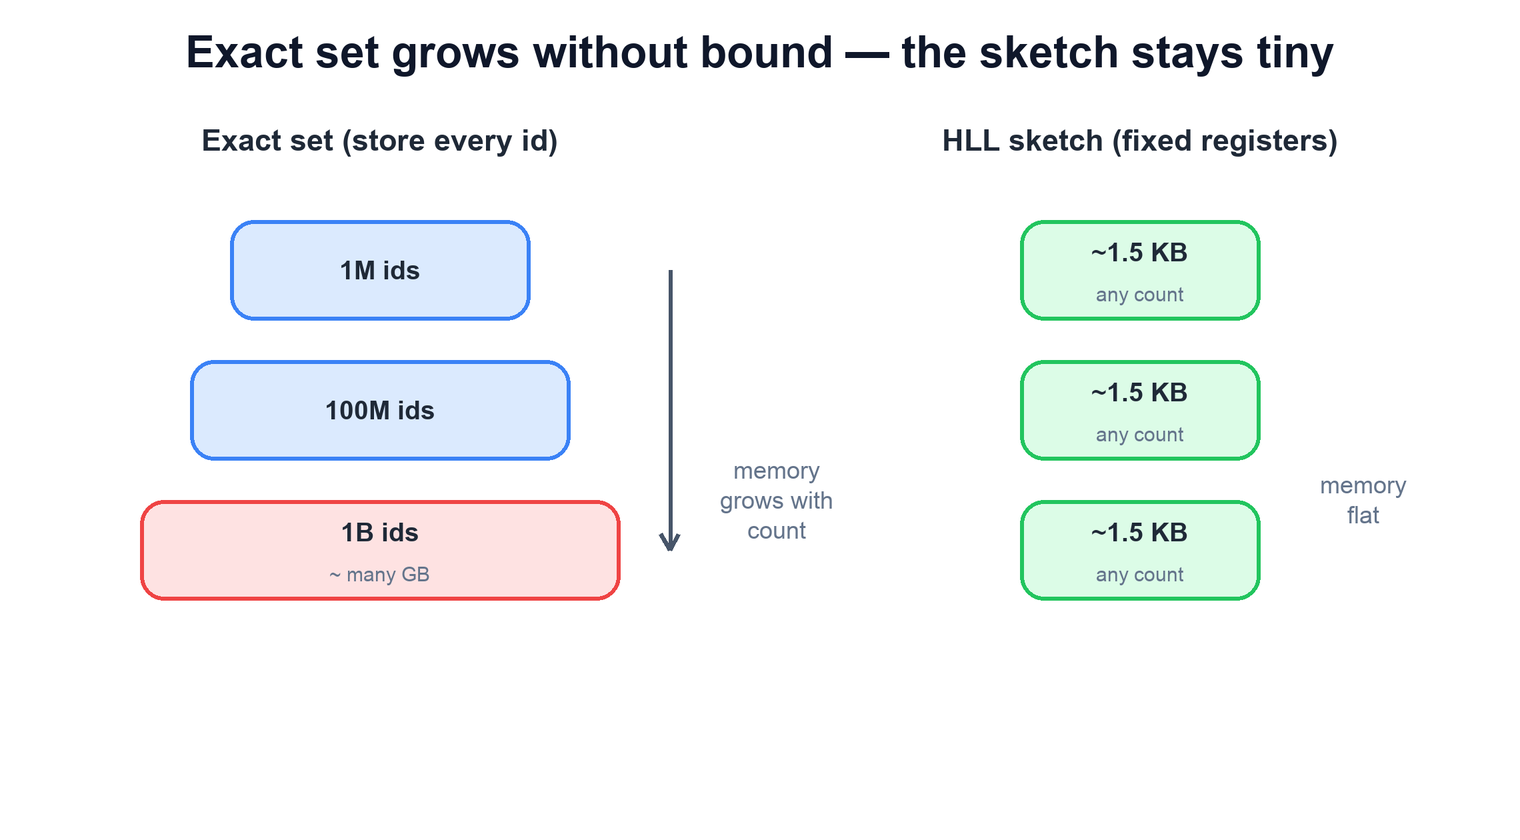
Each distinct id you insert occupies space in the set — the id itself plus the hash-table overhead around it. That space is paid per distinct id, so the set's footprint grows linearly with cardinality. At a million ids it is a few tens of megabytes and nobody notices. At a billion distinct ids it is many gigabytes for a single counter, and you do not have one counter — you have one per metric, per window, per breakdown. The memory bill is the product of all of those, and it grows without bound as your audience and the number of slices grow.
An exact set stores every distinct id, so its memory climbs with the cardinality — from manageable at a million ids to many gigabytes at a billion. A probabilistic sketch occupies the same small, fixed footprint (about 12 KB for 16,384 registers) no matter how many distinct ids it has summarised.
You could push the exact set onto disk or into a distributed store, but that trades a memory problem for a throughput and latency problem: every event now involves a lookup and possible write against external storage, and the storage itself still grows with cardinality. For a high-rate stream feeding many metrics, the exact set is the wrong tool — not because it is incorrect, but because its cost is tied to exactly the quantity you are trying to measure.
The key insight that unlocks a cheaper approach is that most consumers of these numbers do not need the exact figure. Whether daily actives are 41,802,119 or 41,800,000 changes no decision; a count that is within a percent or two, computed in a fixed 12 KB, is far more valuable than an exact one that costs gigabytes. That tolerance is what probabilistic cardinality estimation trades on.
5. HyperLogLog
HyperLogLog (HLL) is the standard answer to large-scale distinct counting. It estimates cardinality from a tiny, fixed-size summary — a few kilobytes that can stand in for billions of distinct ids — by exploiting a statistical property of hashed values rather than remembering the ids themselves.
The intuition is a coin-flip argument. If you hash an id into a uniformly random bit string, then the number of leading zeros in that string behaves like flipping a coin and counting how many heads you get in a row before the first tail. Seeing a run of k leading zeros is roughly a one-in-2k event. So if, across all the ids you have hashed, the longest run of leading zeros you have ever observed is k, that is evidence you have probably seen on the order of 2k distinct values. Crucially, repeats do not move this estimate: hashing the same id again produces the same bit string and the same leading-zero count, so duplicates are silently absorbed — which is exactly the distinctness property we need.
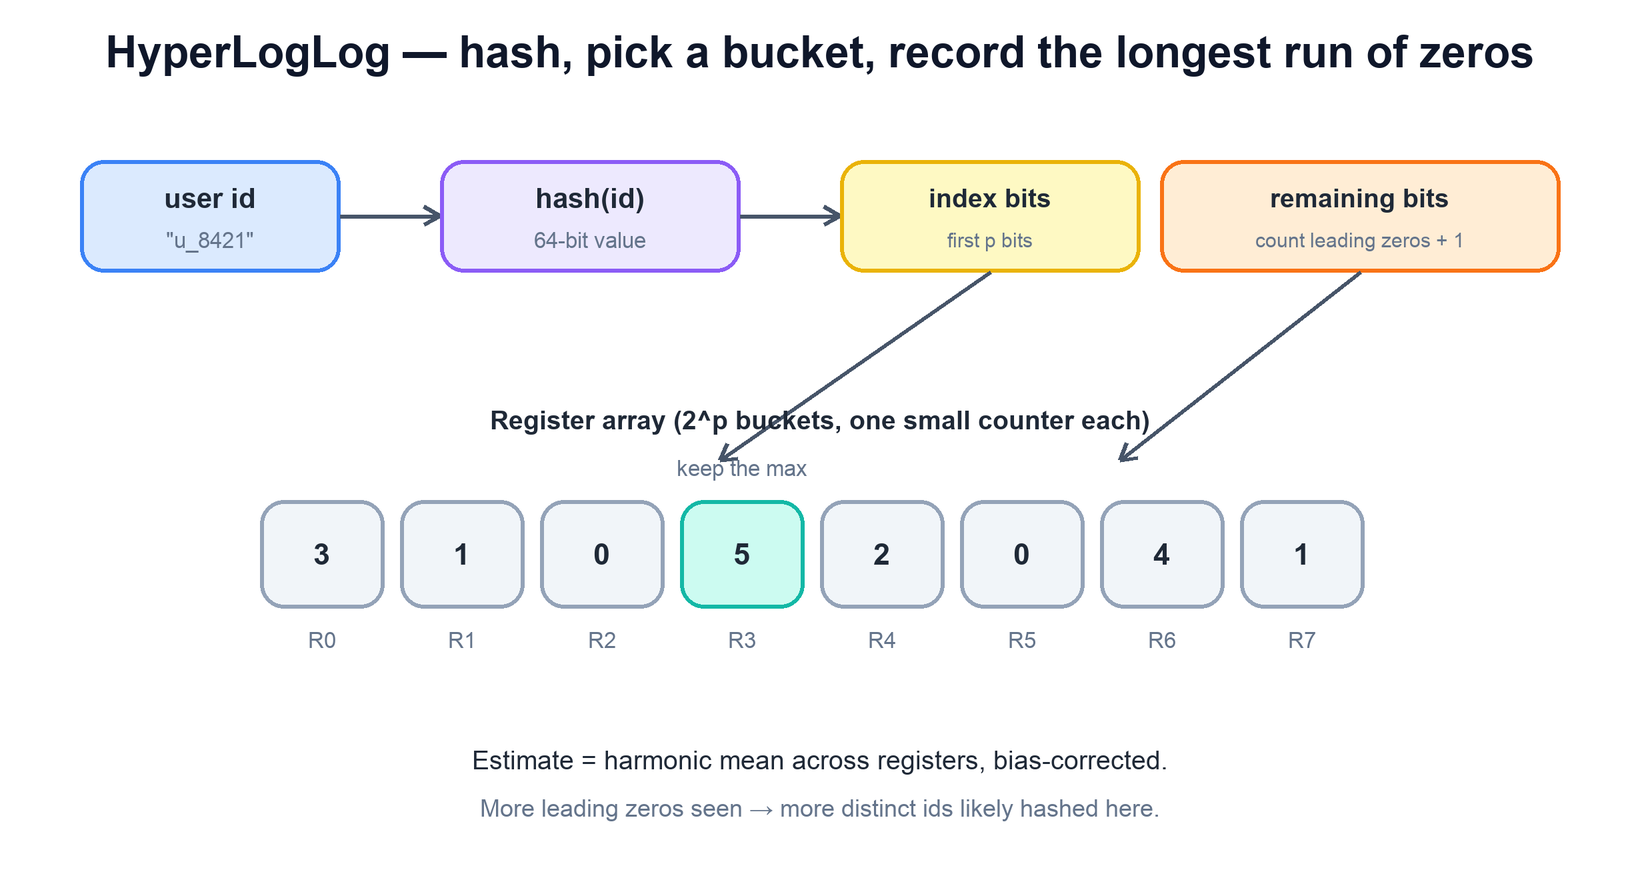
A single longest-run observation is a wildly noisy estimator, so HLL splits the work across many independent registers (also called buckets) and averages them. Each id is hashed once; the first few bits of the hash pick which register the id belongs to, and the remaining bits supply the leading-zero count for that register. Each register keeps only the maximum leading-zero count it has ever seen — a small integer, a handful of bits. The final estimate combines all the registers using a harmonic mean (with a bias correction), which damps the influence of any one unusually long run and gives a stable answer.
Intuition: coin flips
If a friend tells you the longest run of heads they flipped in a row was 10, you would guess they flipped about 210 ≈ 1,000 times. One friend is a noisy witness, so HLL asks 16,384 friends (registers) and combines their answers.
Each id is hashed once. The first p bits select one of 2^p registers; the remaining bits give the position of the first set bit, i.e. one plus the leading-zero count. The register keeps the maximum such value it has seen. The cardinality estimate is a bias-corrected harmonic mean across all registers — more leading zeros seen in a bucket implies more distinct ids likely hashed into it.
# add an id to the sketch
function hll_add(registers, id):
h = hash64(id) # uniform 64-bit value
idx = h >> (64 - p) # first p bits -> register index
rest = h & ((1 << (64 - p)) - 1) # remaining bits
rank = leading_zeros(rest, width=64-p) + 1 # zeros counted inside the 64-p bit field
registers[idx] = max(registers[idx], rank) # keep the longest run# estimate the cardinality from the registers
function hll_estimate(registers):
m = len(registers) # 2^p buckets
raw = alpha(m) * m*m / sum(2 ** -r for r in registers) # harmonic mean
return bias_correct(raw, registers) # small/large-range fixes
The headline result is the memory story. With 2,048 registers (p = 11) of 6 bits each — 1.5 KB total — HLL estimates cardinalities up into the billions with a standard error of about 2.3%. Redis uses 16,384 registers (12 KB) for about 0.81%. That footprint is fixed: it does not grow as the count grows, which is precisely the link that the exact set could not break.
Try it: a 30-line HyperLogLog
This runnable Python sketch uses p = 14 like Redis. Set A adds every id twice to show that duplicates change nothing. B overlaps A by half, and the union is the element-wise max.
import hashlib
import math

P = 14                      # 2^14 = 16384 registers (what Redis uses)
M = 1 << P

def h64(x):
    return int.from_bytes(hashlib.blake2b(str(x).encode(), digest_size=8).digest(), "big")

def add(reg, item):
    h = h64(item)
    idx = h >> (64 - P)                 # first P bits pick the register
    rest = h & ((1 << (64 - P)) - 1)    # the other 64-P bits
    rank = (64 - P) - rest.bit_length() + 1   # leading zeros in 64-P bits, plus 1
    reg[idx] = max(reg[idx], rank)

def estimate(reg):
    alpha = 0.7213 / (1 + 1.079 / M)
    raw = alpha * M * M / sum(2.0 ** -r for r in reg)
    zeros = reg.count(0)
    if raw <= 2.5 * M and zeros:        # small range: linear counting
        return M * math.log(M / zeros)
    return raw

a, b = [0] * M, [0] * M
for i in range(1_000_000):
    add(a, f"user{i}")
    add(a, f"user{i}")                  # duplicates change nothing
for i in range(500_000, 1_500_000):
    add(b, f"user{i}")
union = [max(x, y) for x, y in zip(a, b)]
for name, reg, true in [("A", a, 1_000_000), ("B", b, 1_000_000), ("A∪B", union, 1_500_000)]:
    est = estimate(reg)
    print(f"{name:4} true={true:>9,} est={est:>11,.0f} err={100*(est-true)/true:+.2f}%")
print(f"memory: {M} registers x 6 bits = {M*6//8:,} bytes")
Output:
A    true=1,000,000 est=    995,579 err=-0.44%
B    true=1,000,000 est=    983,043 err=-1.70%
A∪B  true=1,500,000 est=  1,476,860 err=-1.54%
memory: 16384 registers x 6 bits = 12,288 bytes
These are observed seeded errors, not an HLL hard bound. The 0.81% asymptotic relative standard error at p=14 permits occasional larger misses; normal-like confidence approximations are not a guarantee for each dataset.
The whole trick is that HLL never stores ids. It stores a fixed array of small "longest run of zeros" counters, and infers cardinality from how extreme those runs are. Memory is a function of the chosen precision, not of how many distinct ids you have actually seen.
6. Mergeability
The property that makes HLL a system-design building block rather than just a clever counter is that two sketches can be merged into one that represents the union of their inputs — exactly and losslessly, with no double counting and no need to revisit the original ids.
Because each register simply holds the maximum leading-zero run seen for the ids that hashed into it, merging two sketches is element-wise maximum: for each register position, take the larger of the two values. The resulting sketch is identical to one you would have built by feeding it every id from both inputs. This works only when the sketches share the same hash function and the same number of registers, which is why those parameters are fixed and standardised up front.
Merging is element-wise max. Each coloured cell in A or B is the value that wins. The result is exactly the sketch you would get by adding every id from both inputs to one sketch.
# union of two sketches = element-wise max of registers
function hll_merge(a, b):
  return [max(a[i], b[i]) for i in range(len(a))]

# DAU over a week = merge of seven daily sketches, then estimate
weekly = reduce(hll_merge, [daily[d] for d in last_7_days])
dau_week = hll_estimate(weekly)
Mergeability buys two things that the architecture leans on heavily:
Across shards. The event stream is partitioned across many machines, each maintaining its own local sketch over the ids it sees. The global distinct count is the merge of all the per-shard sketches. No machine needs the full set of ids, and no shuffle of raw ids is required — you ship kilobyte-sized sketches, not the stream.
Across time windows. Store one sketch per small window — say one per hour or per day — and you can answer any larger window by merging the relevant pieces. Weekly actives are the merge of seven daily sketches; a rolling thirty-day MAU is the merge of thirty. You never recompute from raw events; you compose pre-built sketches.
This is the property that an exact set cannot match cheaply: unioning two large sets means materialising both and deduplicating across them, whereas merging two sketches is a fixed-size, order-independent maximum. It is also what makes distinct counting feel like ordinary aggregation — the sketch behaves like a number you can add up, except the "addition" is a set union.
7. Accuracy and Error
HLL is an estimator, and its error is a tunable parameter rather than an accident. The single knob is the number of registers, set by the precision p (the sketch has 2p registers). More registers mean more independent observations to average, which means a tighter estimate — at the cost of a larger, though still tiny, sketch.
The relationship is clean: with m = 2p registers, the standard error is about 1.04 / √m. Doubling the registers shrinks the error by about thirty percent. The commonly cited operating point — around 1.5 KB and roughly two percent error — is just one choice on this curve; you can spend a few more kilobytes to push the error well under a percent if a metric warrants it.
Concern
What it means in practice
Tunable error
Pick precision p to trade memory for accuracy. Standard error ≈ 1.04/√(2^p); more registers, tighter estimate, slightly bigger sketch.
Relative, not absolute
The error is a percentage of the true count, so the absolute miss grows with cardinality — fine for large numbers, less ideal for tiny ones.
Small-range behaviour
At very low cardinalities the raw estimate is biased; implementations switch to a more exact mode (e.g. linear counting) below a threshold.
No per-id queries
A sketch answers "how many distinct?" but cannot tell you whether a specific id is in the set — it forgets the ids by design.
Weak at intersections
Merge gives unions. An intersection must be estimated as |A| + |B| − |A ∪ B|, and the errors of all three add up (see the box below).
Precision p
Registers m
Memory (6-bit registers)
Standard error 1.04/√m
11
2,048
1.5 KB
2.30%
12
4,096
3 KB
1.63%
14 (Redis)
16,384
12 KB
0.81%
16
65,536
48 KB
0.41%
"Standard error" is one standard deviation. About two thirds of estimates land within it, and about 95% land within twice it, so an occasional miss of 2× the quoted figure is normal.
Intersections break HLL
Say campaigns A and B each reach 10 million users, and 100,000 people saw both. The union is 19.9 million. At p = 14 its estimate has a standard error of 0.81% × 19.9M ≈ 161,000 — bigger than the 100,000 overlap you are trying to find. Inclusion-exclusion (|A| + |B| − |A∪B|) can then give a negative number. For overlap questions use an exact join, a larger sketch, or a sketch built for set operations such as Theta sketches (Apache DataSketches).
The practical consequence is that HLL is excellent for the large, fuzzy numbers that drive product and business decisions, and a poor fit when you need exactness or per-element membership. Knowing which regime you are in is the judgement call.
8. Exact vs Approximate
Choosing between an exact set and a probabilistic sketch is a question about requirements, not cleverness. The deciding factors are how large the cardinality gets, how much error the consumer can tolerate, and whether anything downstream needs to ask about individual ids.
Use an exact count when cardinalities are modest (thousands to low millions), when the number must be precise — billing, compliance, financial reconciliation, anything audited — or when you also need membership ("has this specific user been seen?"). At small scale the exact set is simple, correct, and cheap enough.
Use an approximate sketch when cardinalities reach the high millions or billions, when a couple of percent of error is invisible to the decision being made, and especially when you need to roll the same metric up across many shards and time windows. This is the regime of DAU, MAU, and unique reach.
A common hybrid is to keep exact counts for small or high-stakes slices and switch to HLL once a slice's cardinality crosses a threshold where the exact set's memory stops being free. Some systems even start a counter as an exact set and promote it to a sketch automatically when it grows past a configured size, getting precision for small audiences and bounded memory for large ones.
9. Real Tools
Redis exposes PFADD, PFCOUNT, and PFMERGE. Commands take explicit key names; PFMERGE dst shard* does not expand a wildcard in Redis. Discover keys with a safe application-maintained list or bounded SCAN, then pass explicit sources. Redis Cluster requires the relevant multi-key command's keys to share a slot (use a deliberate hash tag), or merge exported sketches in an application/backend that supports cross-shard aggregation.
Trino's approx_distinct and Spark's approx_count_distinct expose approximate cardinality with configurable error. Vendor approximate-distinct algorithms vary: do not assume every warehouse uses identical HLL parameters or supports byte-compatible merges. Persist algorithm, precision, hash/normalization version, and window metadata with stored sketches.
10. API and Data Model
# write: activity events (batched, via Kafka)
{ "user_id": "u_8421", "ts": "2026-09-25T14:03:07Z", "country": "BR", "platform": "ios" }

# read: distinct users for a metric, slice and range
GET /v1/uniques?metric=active&slice=country:BR&from=2026-09-01&to=2026-09-30
  → { "estimate": 41802119, "std_error_pct": 0.81, "sketches_merged": 30 }
Table
Key
Value
Notes
sketch_hour
(metric, slice, hour)
HLL bytes, p = 14
Kept a few days for "last N hours" queries.
sketch_day
(metric, slice, day)
HLL bytes, p = 14
Whole retained windows can merge into a larger range. A partial-hour/day boundary requires finer retained sketches or raw/exact boundary handling; one whole-day sketch cannot isolate part of that day.
count_day
(metric, slice, day)
estimate (int)
Optional cache of the single-day number for fast charts.
Store the sketch, not only the number
You cannot add two daily DAU numbers to get a two-day count, because people active on both days would be counted twice. You can merge two daily sketches. Store the sketch bytes so every future range is still answerable.
11. Architecture
Putting the pieces together, a unique-user counting service is a pipeline that turns a firehose of events into a small, mergeable sketch per metric and window, and serves estimates by reading or merging those sketches. The shape follows directly from the two properties established above: a sketch costs fixed memory, and sketches merge.
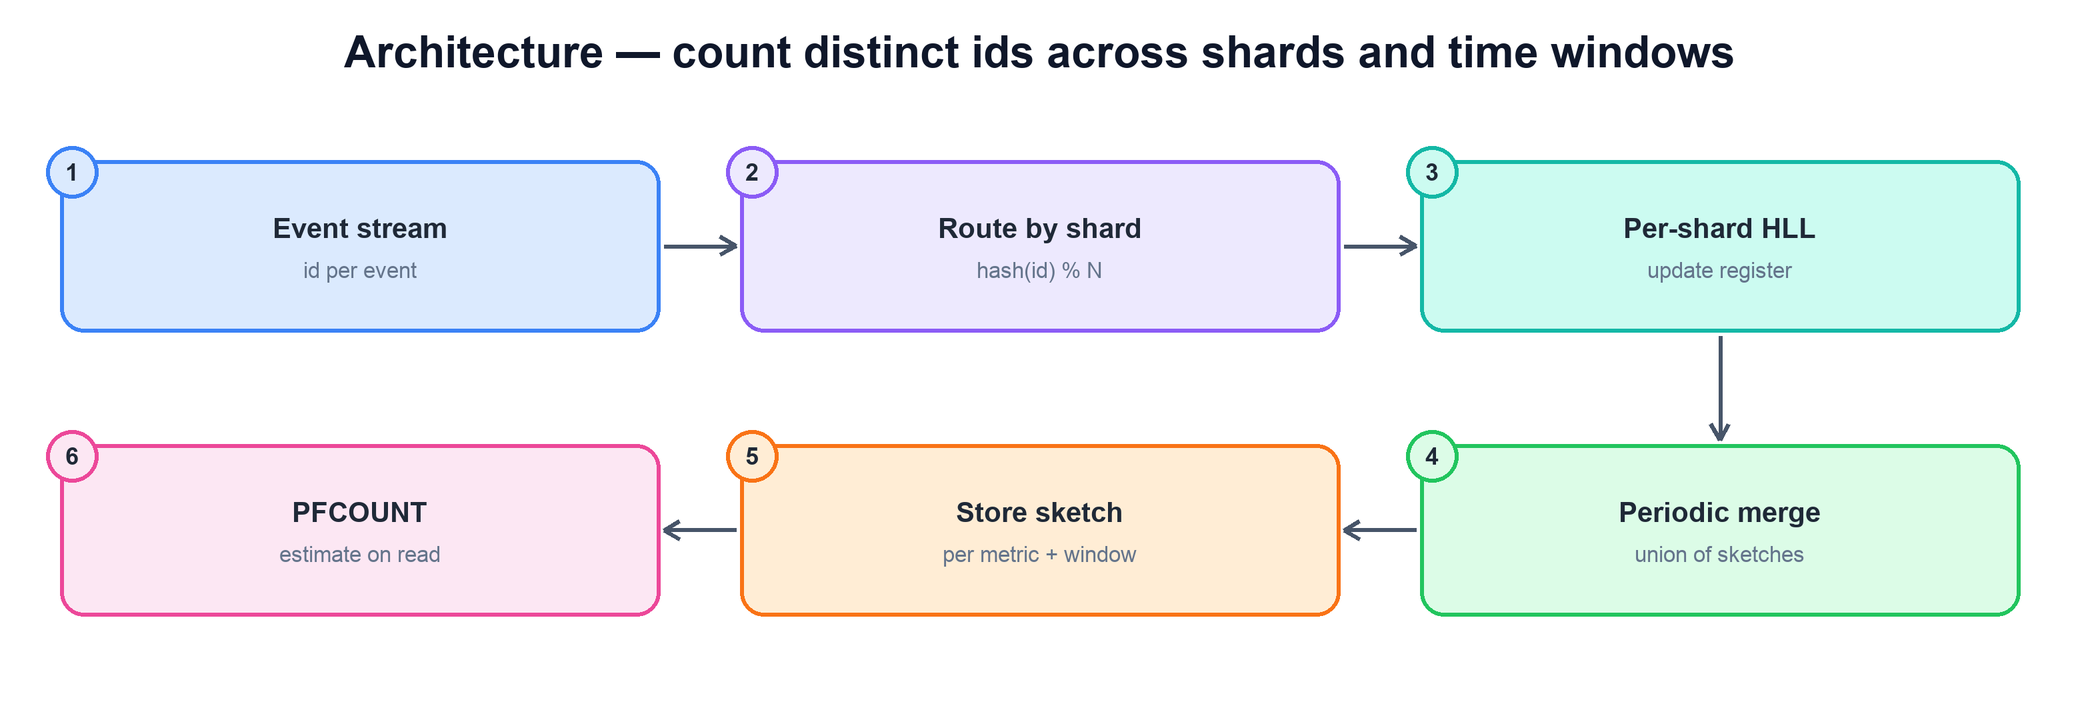
Events flow in carrying an id; each is routed to a shard by hashing the id, and the shard updates its local HLL sketch. A periodic job merges per-shard sketches into a single sketch per metric and time window, which is persisted. Reads estimate cardinality from a stored sketch (or merge several windows on the fly), e.g. via PFCOUNT.
Tracing the flow:
Event stream. Raw events arrive at high rate, each carrying at least a user id and the dimensions you slice on (time, region, campaign). This is the firehose; per-event work has to be cheap.
Routing by shard. Events are partitioned across machines, typically by hashing the id, so each shard maintains an independent sketch over its portion of the stream. Routing by id is not required for correctness — sketches merge regardless — but it keeps each shard's work bounded.
Per-shard HLL update. For each event, the shard hashes the id and updates the relevant register in its in-memory sketch. This is the only per-event cost, and it is a hash plus a max — constant time, constant space.
Periodic merge. On a schedule (or at window boundaries), a job merges the per-shard sketches for each metric and window into a single consolidated sketch via element-wise max. This collapses many partial sketches into the canonical one for that slice.
Store sketch per metric + window. The merged sketches are persisted, keyed by metric and window. Storing the sketch, not just the estimate, preserves mergeability so larger or composite windows can be answered later.
Query. A read either estimates directly from one stored sketch, or merges several stored sketches (e.g. seven dailies for a weekly figure) and then estimates. Either way the read touches kilobytes, not the original stream.
# ingest path: cheap per-event update on the owning shard
function on_event(evt):
shard = pick_shard(evt.user_id) # hash(id) % N
for window in windows_for(evt.timestamp): # e.g. this hour, this day
sketch = shard.sketch(evt.metric, window)
hll_add(sketch.registers, evt.user_id) # hash + max, O(1)# periodic merge: collapse per-shard sketches, then persist
function consolidate(metric, window):
merged = reduce(hll_merge, [s.sketch(metric, window) for s in shards])
store.put(key(metric, window), merged) # keep the sketch itself# read path: estimate, merging windows on the fly if needed
function distinct_count(metric, windows):
sketches = [store.get(key(metric, w)) for w in windows]
return hll_estimate(reduce(hll_merge, sketches))
12. Failure Modes
Failure
What happens
Mitigation
Shard crashes before its sketch is persisted
That shard's ids for the window are missing.
Checkpoint sketches with Kafka offsets and replay. Re-adding ids is harmless because HLL is idempotent.
Duplicate delivery (at-least-once)
Same id added twice.
Nothing to do: max() makes repeats free. This is a big operational win of HLL.
Two sketches built with different p or hash
Merge is meaningless.
Store p and hash version in the sketch header; refuse to merge mismatches.
Late events for a closed day
Day undercounts.
Keep the day sketch writable for a grace period; adds are idempotent so re-opening is safe.
Bot traffic with random ids
Cardinality inflates.
Filter invalid traffic before the sketch; a sketch cannot remove an id once added.
13. Tradeoffs and Alternatives
Representation
Useful operations
Limits
Exact set
Membership, union, intersection, deletion.
Memory depends on identities and runtime/container overhead.
Dense bitmap
Exact set operations over a bounded integer universe.
Universe bits may be huge; compressed formats have data-dependent overhead.
No individual membership/deletion. Statistical error; sketch precision/encoding must match.
Theta/set-operation sketches
Approximate union/intersection/difference with documented accuracy.
Accuracy and memory depend on parameters and result size.
The 12 KiB HLL figure is packed six-bit register payload, not Python list RAM. Standard error is not a hard maximum, nor an exact 95% guarantee for every dataset; normal-like confidence statements are asymptotic approximations. Larger time ranges are answerable only at the granularity of retained sketches; a partial-day interval cannot be reconstructed from a whole-day sketch alone.
Worked example: overlapping daily audiences
Day A contains {u1,u2,u3}; day B contains {u3,u4}.
Read top to bottom. The table below explains the state and guarantee at each step.
Step
State, calculation, and reasoning
1. Count days separately
Exact DAUs are 3 and 2. Adding the numbers gives 5, double-counting u3.
2. Merge identities or sketches
The exact union is {u1,u2,u3,u4}, size 4. Compatible HLL register-wise max creates the same sketch as ingesting that union.
3. Handle duplicate deliveries
Adding u3 repeatedly does not change its maximum register rank. This is sketch idempotency, not proof ingestion never loses an event.
4. Ask about intersections
An HLL union does not recover the individual IDs. Inclusion–exclusion combines noisy estimates and can be useless for a small overlap; use exact sets or a sketch designed for set operations.
Check your understanding: Does 'lossless merge' mean an exact user count?
No. It means no extra information loss beyond the sketch representation: the merged registers are identical to one union sketch. Its estimated count still has statistical error.
Run a small, testable model
Download concepts.py. It uses only the Python 3.10+ standard library. From the directory where you saved it, run:
python3 concepts.py hll
python3 concepts.py test
The model uses packed one-byte registers for a transparent HLL implementation and reports observed error separately from expected standard error.
The program contains deterministic assertions and failure traces. It is a learning model, not a production service: it does not implement network consensus, distributed durability, authentication, or third-party delivery. Read its contracts and try changing an input before extending it.
~870K events/s; exact sets are tens of GB/day; sketches are MB/day.
10–15
Naive design
Exact set per slice per day. Show why it fails for MAU and many slices.
15–30
HLL deep dive
Hash, register index, leading zeros, harmonic mean, 1.04/√m, merge by max.
30–40
Architecture
Kafka → per-shard sketches → merge → sketch store by (metric, slice, window) → merge on read.
40–45
Limits
Intersections, small counts, billing stays exact, bot filtering, failure handling.
15. Common Mistakes
Adding daily uniques to get weekly uniques. A user active on 5 days is counted 5 times. Merge sketches instead.
Quoting "1/√m". The constant is 1.04, and it is a standard error, not a hard bound.
Using HLL for overlaps. Inclusion-exclusion multiplies the error; small overlaps disappear in the noise.
Merging mismatched sketches. Different p or different hash functions cannot be merged.
Using a sketch for billing. Anything audited or charged needs an exact count.
Storing only the final number. Without the sketch you cannot answer new ranges later.
16. Summary
Counting unique users at scale is the problem of measuring cardinality without paying memory proportional to the answer. The design is a small set of decisions that reinforce one another:
Concern
Mechanism
What are we actually computing?
Cardinality — the number of distinct ids in a stream — for metrics like DAU, MAU, and unique reach.
Why not just use a set?
An exact set costs memory proportional to the distinct count — gigabytes at a billion ids, multiplied across every metric and window.
How do we count distinctly in fixed memory?
HyperLogLog: hash each id, track the longest leading-zero run per register, estimate via a bias-corrected harmonic mean.
How do we roll up across shards and time?
Mergeability — the union of two sketches is the element-wise max of their registers, exact and order-independent.
How accurate is it?
Tunable: standard error ≈ 1.04/√(registers); 1.5 KB gives about 2.3%, 12 KB about 0.81%.
When should we stay exact?
Small cardinalities, audited or billed numbers, or when per-id membership is required.
What do we build on?
Redis PFADD/PFCOUNT/PFMERGE, Presto approx_distinct, Spark approx_count_distinct — HLL is built in.
How is it wired together?
Event stream → per-shard sketch → periodic merge → stored sketch per metric and window → estimate on read.
The recurring theme: trade a sliver of accuracy for a fixed, tiny memory footprint and the ability to compose. Once a distinct count is a mergeable kilobyte instead of a growing set, counting unique users becomes ordinary aggregation that scales with your audience instead of fighting it.
17. Check Yourself
You need about 1% standard error. What is the smallest standard precision p, and how much memory does it use?
Answer
1.04/√m ≤ 0.01 needs m ≥ 10,816, so p = 14 (m = 16,384). That is 12 KB with 6-bit registers and gives 0.81%. p = 13 gives 1.15%, just over the target.
Monday's DAU is 40M and Tuesday's is 42M. Can you say the two-day unique count is 82M?
Answer
No. Users active on both days would be counted twice. The true answer is between 42M and 82M. Merge the two daily sketches and estimate the union.
Why does adding the same user id a million times not change an HLL sketch?
Answer
The same id always hashes to the same register and the same rank. max(r, r) = r, so the register is unchanged after the first add.
Doubling the number of registers reduces the error by how much?
Answer
By a factor of √2, so the error drops by about 29%. To halve the error you need 4× the registers.
Campaigns A and B each reach 10M users with 100K overlap. Why is HLL a bad way to measure the overlap?
Answer
The union (19.9M) has a standard error of about 161K at p = 14, which is larger than the 100K overlap. Inclusion-exclusion inherits that error, so the answer is mostly noise.
Your sketches are written by consumers that can replay Kafka after a crash. Do you need exactly-once processing?
Answer
No. HLL adds are idempotent, so replaying the same events leaves the sketch unchanged. At-least-once delivery is enough.
18. Key Terms
Cardinality
The number of distinct identities a store must track. A metric series is its metric name plus the full label combination. The product of label-value counts is an upper bound when not every combination occurs. Example and limits above.
DAU / MAU
Daily / monthly active users: distinct users active in a day / 30 days.
Register
One small counter in an HLL sketch holding the max rank seen.
Precision p
Number of hash bits used to pick a register; m = 2p.
Rank
Position of the first 1-bit in the remaining hash bits (leading zeros + 1).
Harmonic mean
An average that damps outliers: n ÷ ∑(1/x).
Standard error
One standard deviation of the estimate, as a fraction of the true value.
Linear counting
Small-range estimator using the fraction of empty registers.
Merge
Element-wise max of two sketches; gives the sketch of the union.
Theta sketch
A sketch family that supports union, intersection and difference.
Further reading
Flajolet, Fusy, Gandouet, Meunier, "HyperLogLog: the analysis of a near-optimal cardinality estimation algorithm," AofA 2007.
Heule, Nunkesser, Hall, "HyperLogLog in Practice: Algorithmic Engineering of a State of The Art Cardinality Estimation Algorithm," EDBT 2013 (HLL++).