A developer's guide to how Redis actually works under the hood: the single-threaded event loop, the data structures and their encodings, the RESP protocol, expiry and eviction, persistence, replication, and how it scales out with Sentinel and Cluster.
Student edition · understand, apply, verify
Understand isolated commands, in-memory state, expiry, persistence, and asynchronous failover as separate mechanisms.
What you should be able to do: Explain why a Redis operation can be atomic yet lose acknowledged state or fail a multi-step business invariant.
Assumes basic programming and HTTP. This is an architecture-level tutorial, not a release-specific implementation contract. Defaults, file formats, APIs, and guarantees depend on the deployed release and configuration; use the linked product documentation before production changes. Snippets marked pseudocode are not runnable integrations.
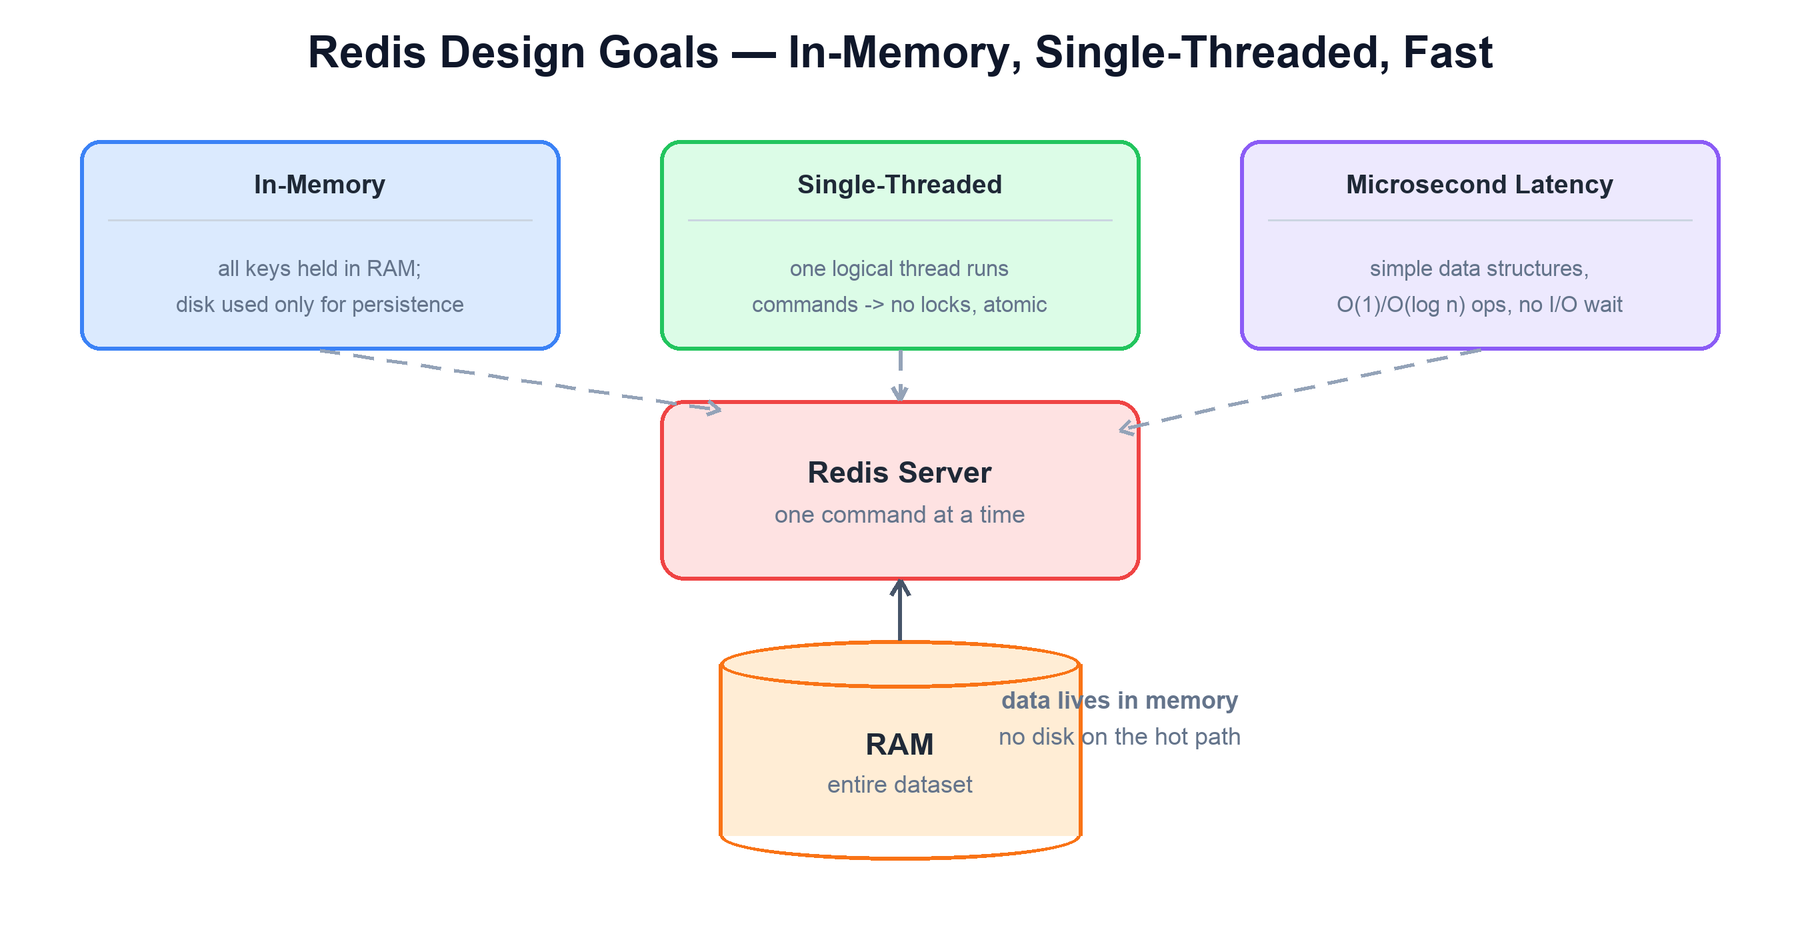
Redis is an in-memory data structure server. Unlike a traditional database that keeps data on disk and caches hot pages in memory, Redis keeps the entire dataset in RAM and treats disk only as a durability backstop. Its second defining choice is that command execution is single-threaded: one logical thread runs commands one at a time, which removes locks and makes every individual command atomic. Those two decisions — memory-resident data and a single-threaded execution model — explain almost everything else about how Redis behaves, from its microsecond latencies to the way it persists, replicates, and shards. This guide walks through the internals a developer needs to reason about Redis confidently.
Read these definitions first, or use the linked terms as you go. The examples and limitations are local to this guide; companion pages are optional.
Isolation is not rollback
Isolation prevents another operation from observing intermediate state. Rollback undoes failed work; durability preserves acknowledged work under specified faults.
Example. Redis MULTI/EXEC may continue after a runtime command error. Script failure can leave earlier writes applied.
Boundary. A read outside MULTI followed by writes is still racy without WATCH/retry or a conditional script. Async failover can lose state.
Snapshots, AOF, and power-loss durability
Snapshots capture recoverable state; an append-only log records later operations. fsync/equivalent and crash-safe ordering define power-loss survival.
Example. An every-second AOF policy targets a small flush gap; disk stalls/delayed flush can make actual risk exceed a strict second.
Boundary. fork/COW can pause and amplify memory. Supporting a format does not mean persistence is enabled by default.
Event loops and nonblocking I/O
One loop handles ready sockets/callbacks instead of one waiting thread per connection. Blocking or long CPU work delays other clients.
Example. Ten thousand sockets share a loop, but their file descriptors, state, and buffers still consume memory.
Boundary. Readiness is not a whole request. Preserve partial read/write parser state; background threads and defaults depend on release/configuration.
Wall and monotonic clocks
A wall clock maps to civil/epoch time and can jump because of correction. A monotonic clock measures elapsed time locally without wall-clock jumps, but its origin is not a shared global epoch.
Example. Use an epoch timestamp to label an event and a monotonic deadline to bound how long a process waits for the next usable timestamp.
Boundary. Neither establishes causal order across machines. Monotonic readings cannot be compared between hosts or assumed to survive reboot with the same origin.
Cache-aside and invalidation
A read checks a cache, reads the authoritative store on a miss, then fills the cache. A write commits to the store and invalidates or refreshes the cached value. TTL means time to live, not a freshness proof.
Example. A reader fetches version 1, a writer commits version 2 and invalidates, then the delayed reader caches version 1. DB-first invalidation alone does not prevent this refill race.
Boundary. Use invalidation-aware fill leases or version fences for stronger behavior; a TTL only bounds one entry's residence under additional assumptions. Authorization and revocation need an explicit stale-data policy.
Quorum
A set of replicas whose responses are sufficient for an operation. In a fixed set of N replicas, read size R and write size W overlap whenever R+W>N. A majority is one particular quorum, not the definition of every quorum.
Example. With N=3, writes to {A,B} and reads from {B,C} share B. If the write completed durably and replicas preserve a comparable version, B carries that version forward.
Boundary. Overlap alone does not provide linearizability: concurrent or failed writes, sloppy replica sets, and version selection matter. Consensus adds protocol rules to preserve decisions.
1. Design Goals and Core Ideas
Every internal decision in Redis traces back to a small set of goals. Keeping them in mind makes the rest of the architecture predictable.
The whole dataset lives in RAM, a single logical thread executes commands one at a time, and the data structures are simple enough to keep operations in the microsecond range.
Goal
How Redis achieves it
Microsecond latency
All data is in memory; operations are O(1) or O(log n) on purpose-built data structures, with no disk seek on the hot path.
Simplicity and atomicity
Ordinary keyspace commands execute under an isolated execution model; separate commands can still race as a sequence, and internal/background work may use synchronization.
Rich data types as a server
Redis is not just a string cache. Lists, hashes, sets, sorted sets, and streams let the server do work that would otherwise round-trip to the client.
Predictable performance
Memory layout and encodings are tuned so common operations cost the same regardless of dataset size.
Optional durability
Persistence (RDB, AOF) is configurable. You choose the trade-off between speed and how many recent writes you can afford to lose.
Single-threaded does not mean slow. A single core doing nothing but in-memory pointer work and avoiding lock contention can serve hundreds of thousands of operations per second. The bottleneck is usually the network and the kernel, not Redis itself — which is exactly why I/O threads (covered next) were added rather than a multi-threaded command executor.
2. Architecture and the Event Loop
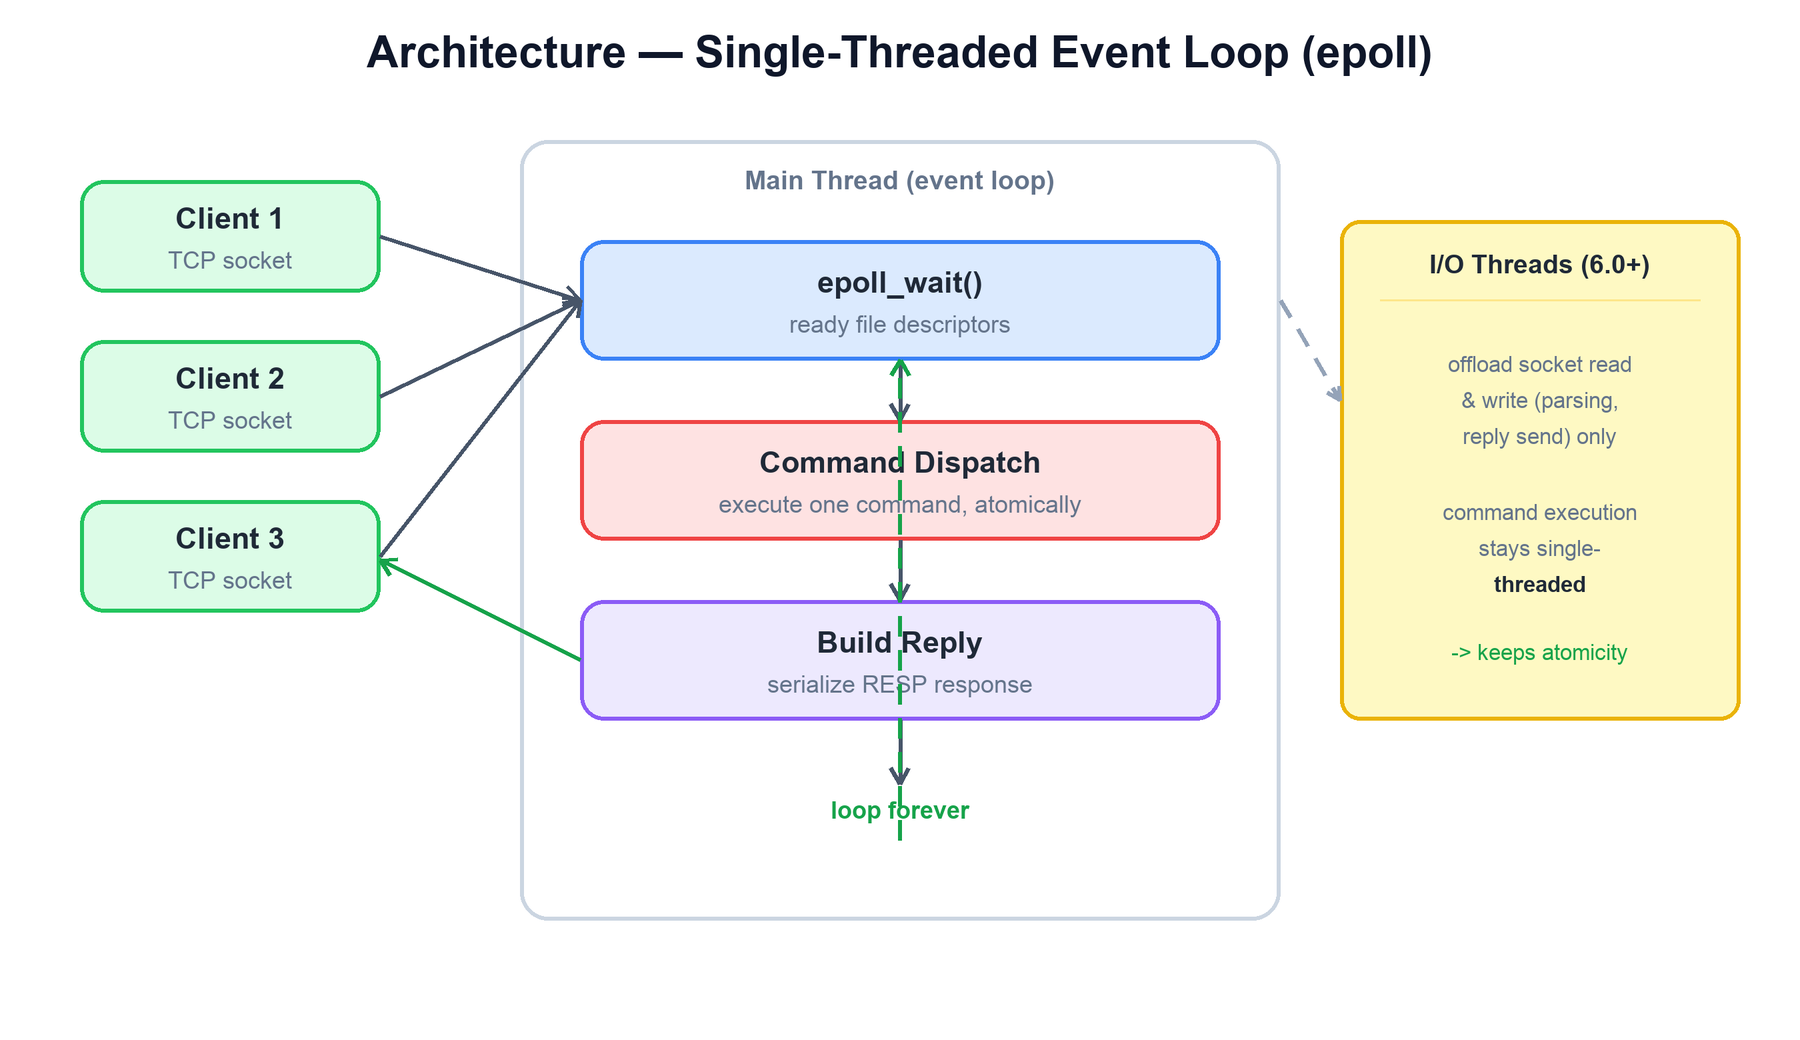
At its core Redis is a single process running an event loop. It uses the operating system's efficient I/O readiness mechanism (epoll on Linux, kqueue on BSD/macOS) to wait for many client sockets at once and wake up only when one of them has data ready. There is no thread per connection; one thread multiplexes thousands of clients.
The main thread waits on epoll, dispatches and executes one command at a time, then builds the reply. I/O threads (6.0+) only offload reading and writing the socket bytes — execution stays single-threaded.
One iteration of the loop does the following:
Poll for readiness:epoll_wait() returns the set of file descriptors that have data to read or room to write. Redis registers a callback per event type.
Read and parse: for a readable client socket, Redis reads the bytes and parses the RESP request into a command plus arguments.
Dispatch and execute: the command name is looked up in the command table and executed against the keyspace. Because this happens on one thread, the command runs to completion with nothing else touching the data — that is the source of atomicity.
Build and queue the reply: the result is serialized into RESP and queued on the client's output buffer, to be written when the socket is writable.
Run background work: the loop also fires time events — active expiration, incremental rehashing, client timeouts, and similar housekeeping.
I/O threads (Redis 6.0+). Profiling showed that on busy servers a large share of CPU was spent in the kernel reading request bytes and writing reply bytes, not in executing commands. Redis 6 added an optional pool of I/O threads that parallelize only the socket read/parse and reply-write steps. The actual command execution remains single-threaded, so atomicity and the no-locks model are preserved while throughput on multi-core machines improves.
while server_running:
  events = epoll_wait(fds)            # block until sockets ready
  for fd in events.readable:
    buf = read(fd)                    # (optionally on an I/O thread)
    cmd, args = parse_resp(buf)
    reply = dispatch(cmd, args)       # executes on the MAIN thread, atomically
    queue_output(fd, reply)
  for fd in events.writable:
    write(fd, output_buffer[fd])      # (optionally on an I/O thread)
  run_time_events()                   # expiry, rehashing, timeouts
3. Data Structures and Internal Encodings
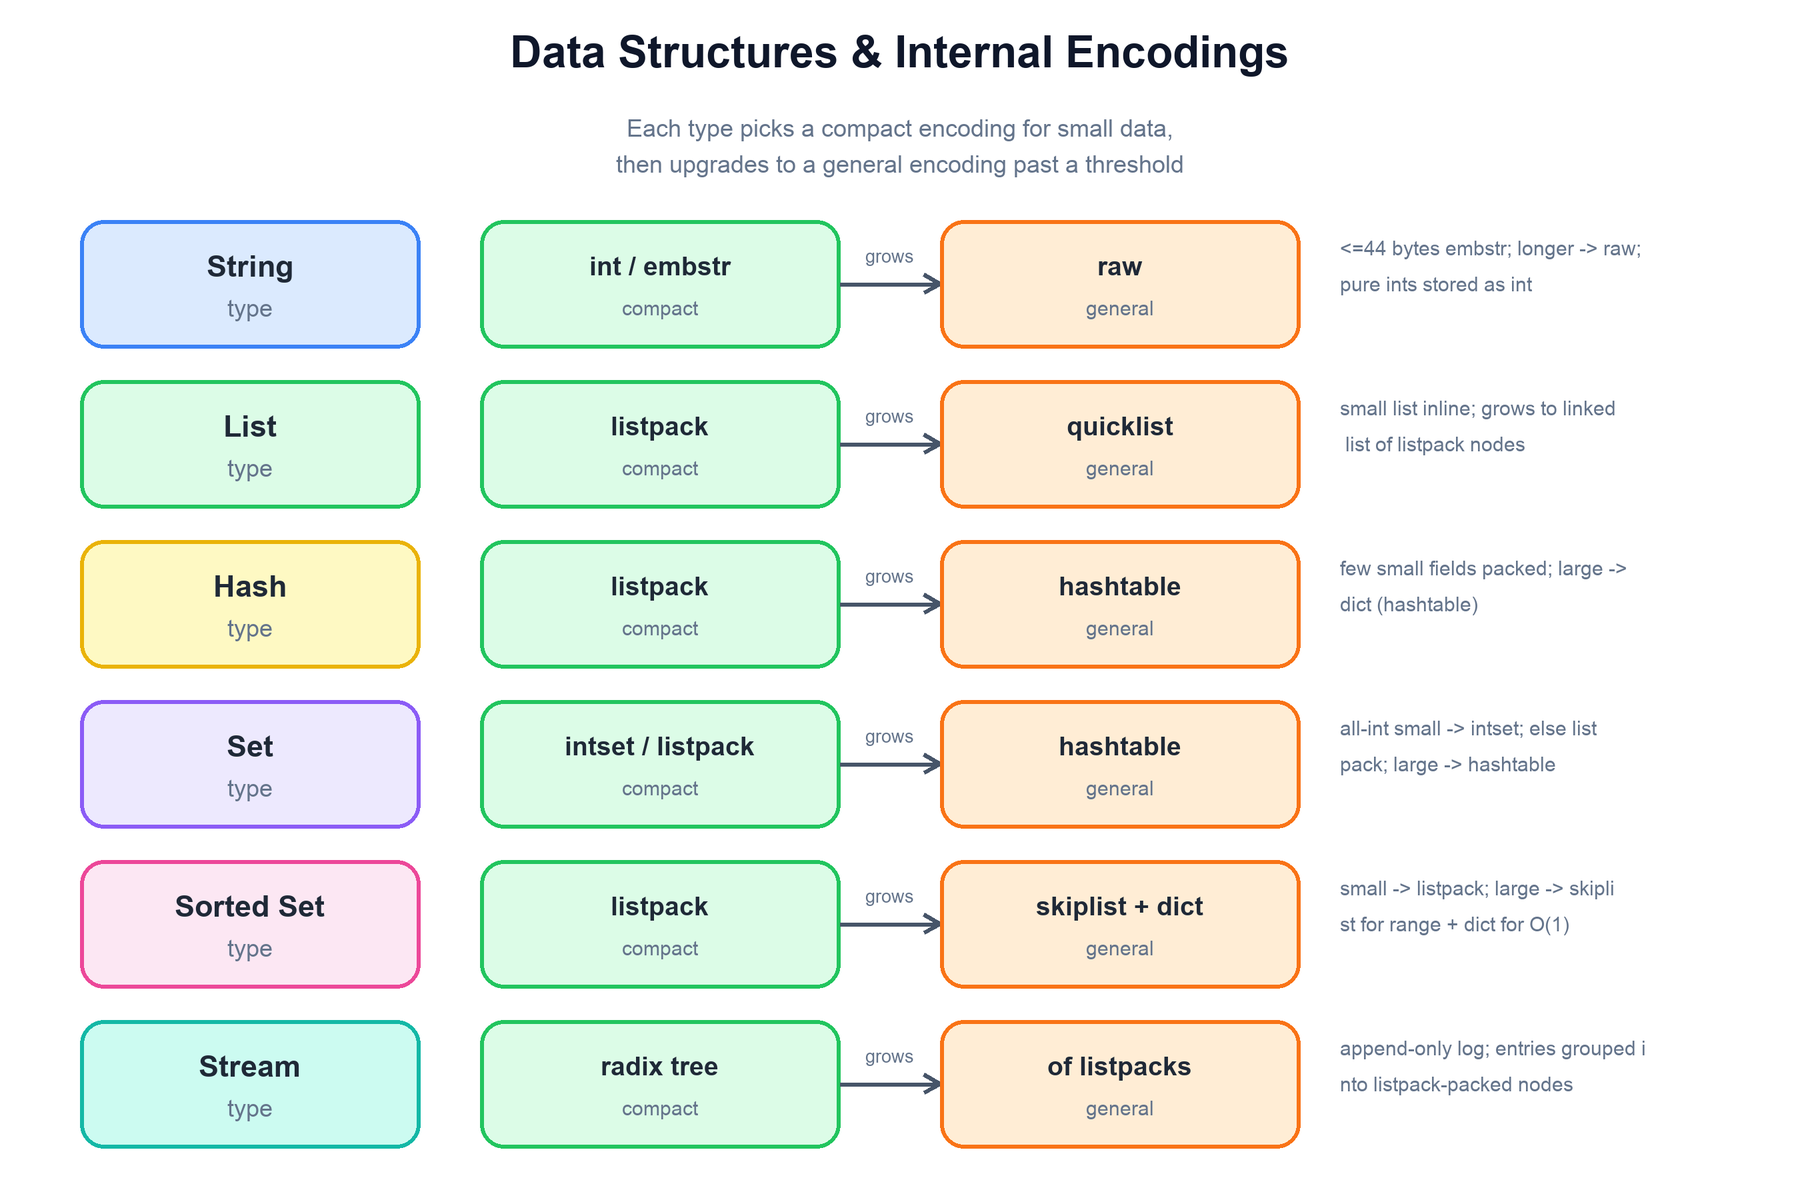
Redis exposes a handful of data types — string, list, hash, set, sorted set, and stream — but each type can be stored internally in more than one way. Redis picks a compact encoding when a value is small and transparently upgrades to a general encoding once it grows past a configurable threshold. The command behavior is identical; only memory layout and performance characteristics change.
Every type starts in a memory-efficient encoding for small data and switches to a general-purpose structure once it crosses a size or element-count threshold.
The key encodings are:
Type
Encodings
How it works
String
int, embstr, raw
A value that is a valid integer is stored as a boxed long (int). Short strings (≤ 44 bytes) use embstr, which allocates the header and the bytes in one contiguous block. Longer or modified strings use raw.
List
listpack → quicklist
A small list is a single listpack (a flat, packed byte array). As it grows it becomes a quicklist: a doubly linked list whose nodes are each a listpack, balancing memory density against fast end operations.
Hash
listpack → hashtable
Few small field/value pairs are packed into one listpack and scanned linearly. Past the threshold it becomes a real hash table (dict) for O(1) field access.
Set
intset / listpack → hashtable
A set of only integers uses a sorted intset. A small mixed set uses a listpack. Large sets become a hash table (keys only).
Sorted Set
listpack → skiplist + dict
Small zsets use a listpack. Large ones combine a skip list (ordered by score, for range queries) with a dict (member → score, for O(1) lookups).
Stream
radix tree of listpacks
An append-only log keyed by time-ordered IDs. Entries are grouped into listpack-packed nodes indexed by a radix tree, with consumer-group state tracked alongside.
The thresholds are tunable (for example hash-max-listpack-entries, set-max-intset-entries). The trade-off is always the same: compact encodings save memory and have great cache locality but are O(n) to scan, so they are only used while n is small. Once a structure is large, Redis pays the per-element overhead of a general structure to keep operations cheap.
4. RESP Protocol and Command Flow
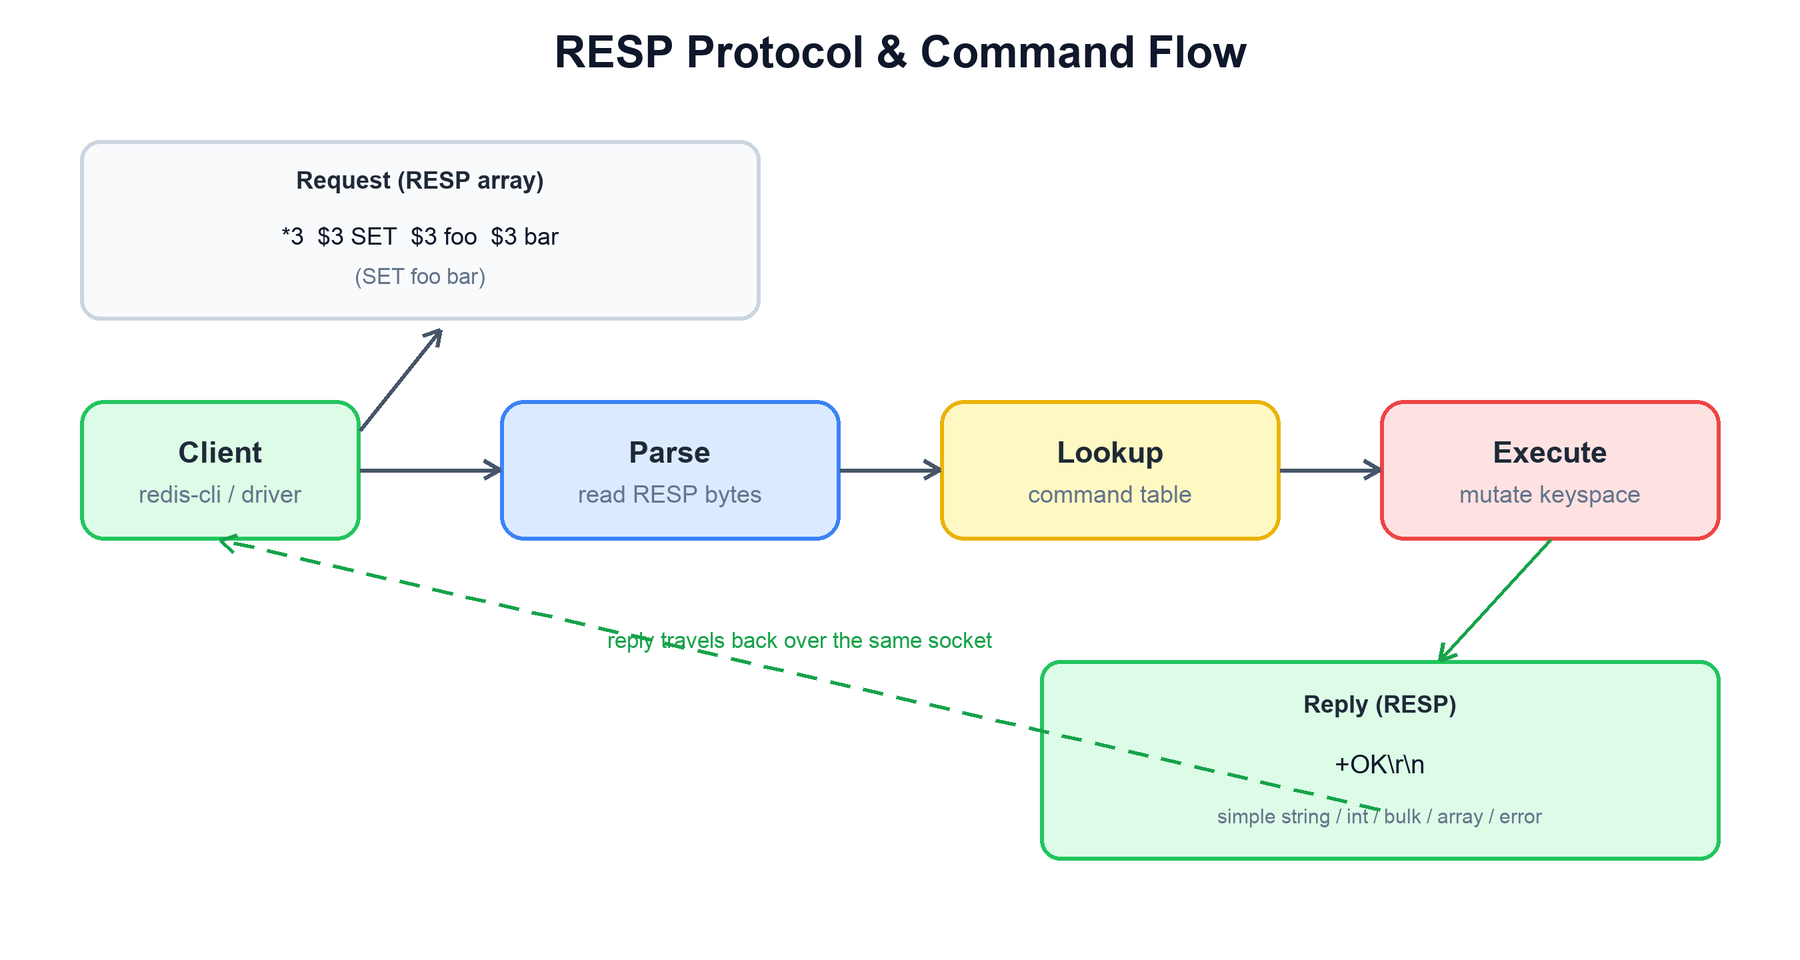
Clients talk to Redis using RESP (REdis Serialization Protocol) — a simple, line-oriented, binary-safe protocol that is easy to parse and human-readable on the wire. A request is an array of bulk strings: the command name followed by its arguments. The reply is a single RESP value whose type depends on the command.
A request arrives as a RESP array, gets parsed, the command is looked up in the command table and executed, and the reply travels back over the same socket as a RESP value.
RESP uses a one-byte type prefix to tell the parser what follows:
Prefix
Type
Example
+
Simple string
+OK\r\n
-
Error
-WRONGTYPE ...\r\n
:
Integer
:1000\r\n
$
Bulk string (length-prefixed, binary-safe)
$3\r\nbar\r\n
*
Array
*2\r\n...\r\n...\r\n
The full flow for a single command is short, which is the point — minimal per-command overhead:
# Client sends: SET foo bar  ->  *3\r\n$3\r\nSET\r\n$3\r\nfoo\r\n$3\r\nbar\r\n
function handle_request(socket):
  bytes = socket.read()
  argv  = parse_resp(bytes)            # ["SET", "foo", "bar"]
  cmd   = command_table.lookup(argv[0])
  if cmd is None:
    return reply_error("unknown command")
  if not cmd.arity_ok(argv):
    return reply_error("wrong number of arguments")
  result = cmd.proc(argv)              # mutate the keyspace, atomically
  return encode_resp(result)           # "+OK\r\n"
Pipelining falls out of this design for free: a client may send many requests back to back without waiting for each reply. Redis reads them all, executes them in order, and sends the replies in order, which amortizes network round-trip time across many commands. MULTI/EXEC transactions go one step further by queuing commands and executing the whole batch as one uninterrupted unit on the single thread.
5. Expiry and Eviction
Expiry removes an entry after its configured time; eviction makes room under a memory policy. These are different. Lazy expiry on access and active sampling reclaim expired keys, but TTL does not prove the underlying source value is fresh. A recently cached stale value can still be within its TTL.
Expiry uses authority clocks/configuration; wall clocks can jump. Replication and command type affect observed behavior. Eviction policies such as approximate LRU/LFU choose candidates under their supported algorithm, not an exact universal ordering. Limits, buffers, overhead, persistence/fork memory, and non-evictable state also affect memory pressure.
noeviction rejects appropriate memory-growing work rather than guaranteeing all commands succeed. Use actual policy and workload measurements; approximate algorithms and defaults depend on release/configuration.
6. Persistence: RDB and AOF
RDB snapshots provide a recoverable point-in-time image. fork/copy-on-write lets a child write while the parent continues, but fork can pause and copied pages can consume substantial extra memory. Writes since the last valid snapshot are not preserved by that snapshot alone.
AOF records operations under its configured flush/sync policy. always requests frequent durable completion; everysec targets periodic fsync, but disk stalls/scheduling/errors can exceed a strict one-second loss bound. no leaves more to operating-system behavior. Persistence may be disabled; format defaults do not imply it is enabled.
Modern AOF designs can use multiple files/manifests and snapshot preambles. Rewrite, file publication, recovery ordering, storage behavior, and backup validation are release-specific. Do not equate 'appended' with power-loss durable or promise zero blocking during rewrite.
7. Replication
Replication is normally asynchronous: acknowledged primary state may be absent from a promoted replica. Backlog/PSYNC handles supported partial resynchronization; falling outside retained history requires a supported full sync. Replication IDs/offsets and the snapshot boundary must agree.
WAIT can wait for replication acknowledgements for prior writes on the relevant connection, reducing some risks. It does not turn Redis into a consensus/linearizable durable store or guarantee the failover procedure selects a copy with every acknowledged write. Durability-related commands/options such as supported AOF-wait policies have their own release-specific scope.
Sentinel coordinates failover; Redis Cluster has its own cluster/failover protocol and is not literally Sentinel wrapped around each shard. Both retain declared failure assumptions. Hard quota/financial invariants need a store/protocol whose loss and ownership contracts actually enforce them.
8. High Availability and Scale
Replication by itself gives you read scaling and a warm copy, but a human still has to react when the master dies, and the whole dataset must fit on one machine. Redis solves the first problem with Sentinel and the second with Cluster.
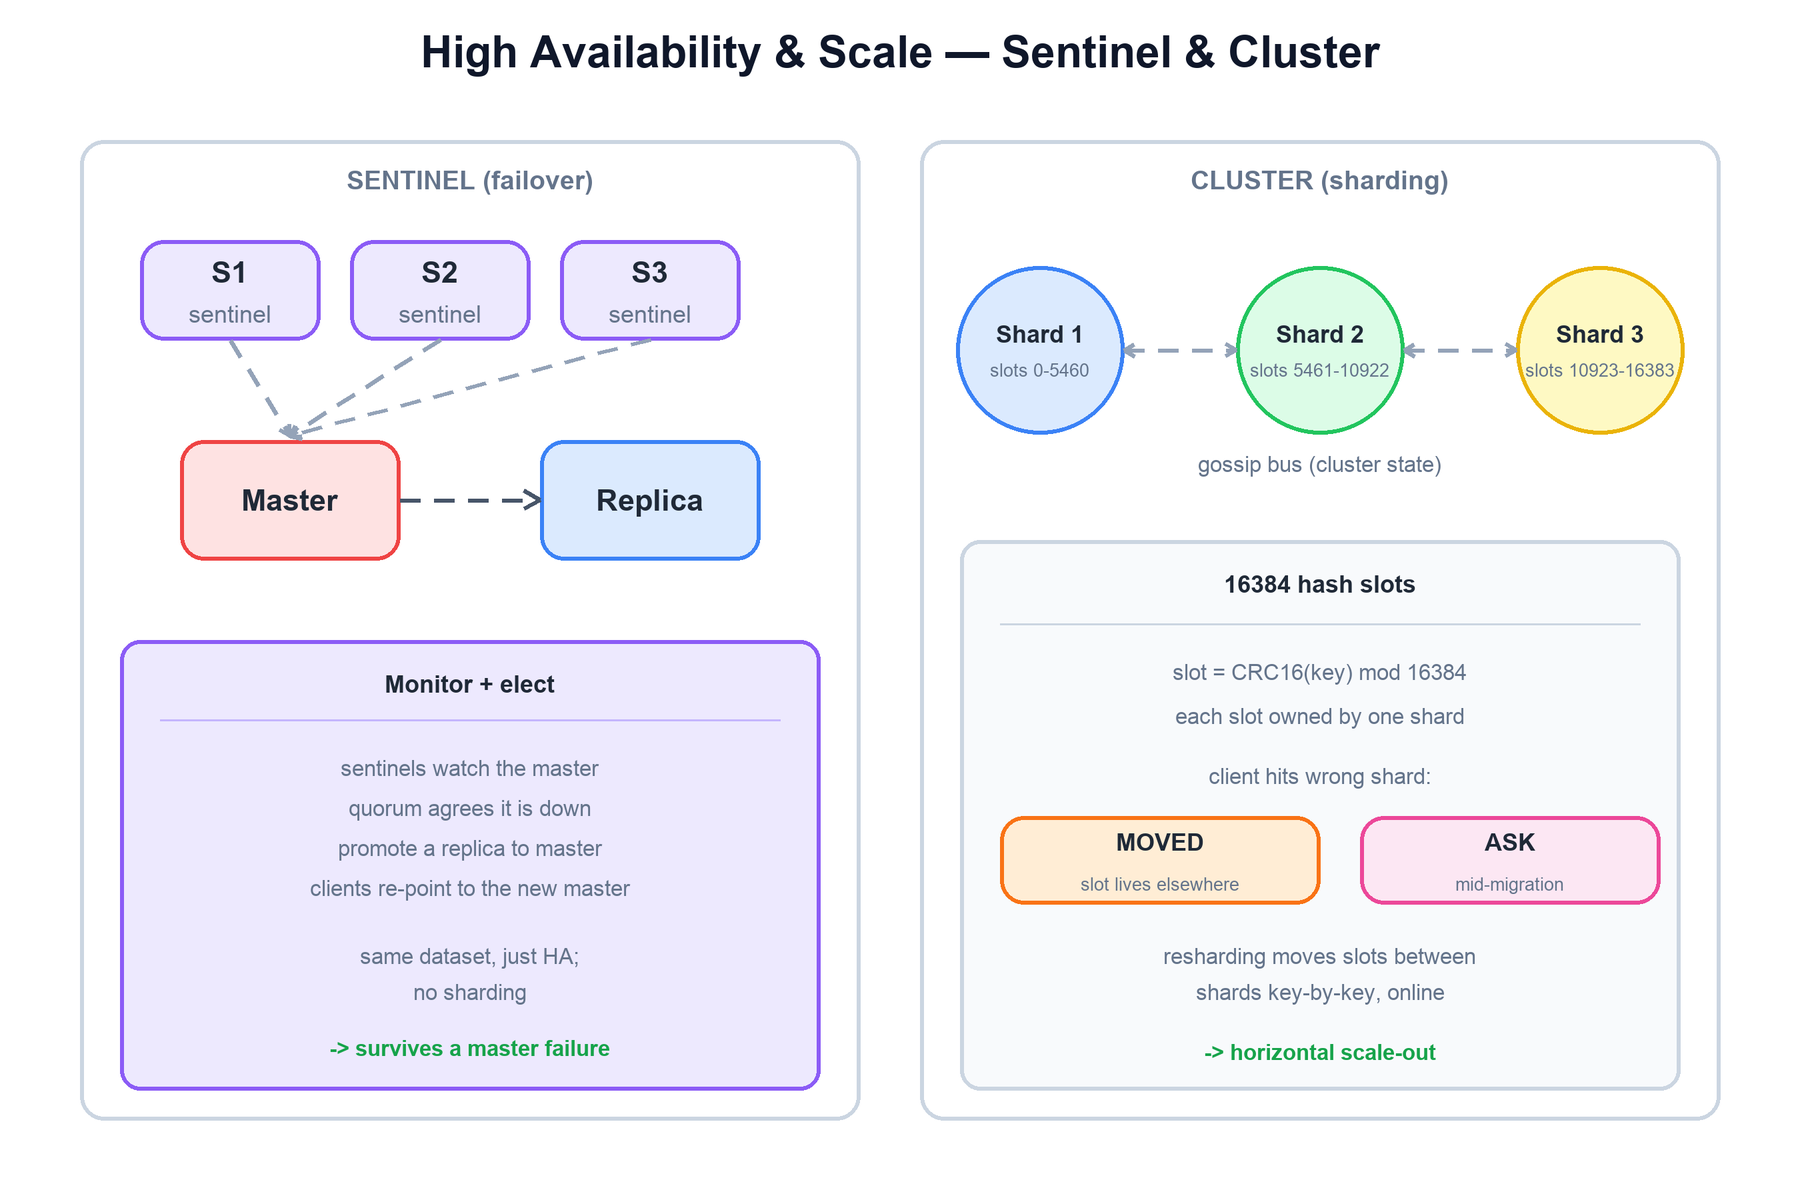
Sentinel adds automatic failover to a single master/replica set. Cluster shards the keyspace across many masters using 16384 hash slots and a gossip bus, redirecting clients with MOVED/ASK.
Sentinel: automatic failover
Sentinel is a separate process (run in odd numbers, typically three or five, for quorum) that monitors a master and its replicas. When enough sentinels agree the master is unreachable, they elect a leader among themselves, promote a suitable replica to master, reconfigure the other replicas to follow it, and tell clients where the new master is. Sentinel provides high availability but not sharding — the entire dataset still lives on one master at a time.
Cluster: sharding the keyspace
Redis Cluster partitions the keyspace across many master shards. The mechanism is a fixed map of 16384 hash slots. Every key is assigned to a slot by CRC16(key) mod 16384, and every slot is owned by exactly one shard. To distribute data you simply distribute slot ownership; each shard typically also has replicas for HA, so Cluster folds in the Sentinel-style failover too.
Concept
What it does
Hash slots (16384)
A coarse, fixed partitioning of the keyspace. Moving data between shards means reassigning slots, not rehashing every key.
CRC16 hashing
slot = CRC16(key) mod 16384 maps a key to a slot deterministically on every client and node.
Gossip bus
Nodes exchange cluster state (who owns which slots, who is up) over a separate cluster bus port, so every node converges on the full topology without a central registry.
MOVED redirect
If a client sends a key to the wrong shard, the node replies MOVED <slot> <addr>; the client retries against the correct shard and caches the mapping.
ASK redirect
During a slot migration, a key may have moved already. The owner replies ASK to send that one request to the new shard without invalidating the client's whole slot map.
Resharding moves slots from one shard to another online, key by key, while the cluster keeps serving traffic. The combination of a fixed slot count, deterministic CRC16 hashing, and MOVED/ASK redirects lets the cluster rebalance without a coordinator and without taking the keyspace offline.
A multi-key command in Cluster only works if all its keys live in the same slot. The hash tag convention — putting a {...} substring in the key, e.g. user:{42}:profile and user:{42}:sessions — makes only the braced part feed CRC16, guaranteeing related keys share a slot and can be operated on together.
Worked example: a command is atomic but a pair is racy
Two clients read the same counter and each then writes an increment.
Sequence for this example. The table explains the evidence and decision at each step.
Step
Evidence, decision, and expected result
Read concurrently
Both GET calls return 10. Each command is isolated; the whole read/decide/write sequence is not.
Write separately
Both SET calls write 11, losing an increment. Use a supported atomic command/script/conditional transaction for that local invariant.
Fail after acknowledgement
An asynchronous replica may not contain the write when promoted. WAIT is not a complete consensus/failover durability protocol.
Expire a cached key
Expiry prevents that key being returned after its authority's TTL rule; it does not prove the cached source data was fresh before expiry.
Check your understanding: Does MULTI/EXEC provide rollback on runtime errors?
No. Distinguish queueing errors from execution errors; some effects may already apply. Validate before mutation and keep durability/failover semantics separate.
Run and change the example
Download guide_labs.py. Python 3.10+, standard library only. In its directory, run:
python3 guide_labs.py transactions
python3 guide_labs.py test
The SQLite teaching model contrasts atomic local effects with a deliberately racy read/modify/write sequence; it is not a Redis server.
The program tests its stated finite contracts. It is an educational model, not an implementation of the named production product or a proof of unmodeled distributed faults.
Compact encodings (listpack, intset, embstr) for small values, upgraded to general structures past a threshold.
How are clients served?
The simple, binary-safe RESP protocol over an epoll event loop, with free pipelining.
How is memory reclaimed?
Lazy + active TTL expiration; sampled LRU/LFU eviction at the maxmemory limit.
How is data made durable?
RDB snapshots (fork + copy-on-write) and the AOF log, combined in a hybrid format.
How does it survive failure?
Async replication (full/partial resync via PSYNC) plus Sentinel for automatic failover.
How does it scale out?
Cluster shards the keyspace into 16384 CRC16 hash slots, redirecting clients with MOVED/ASK.
The recurring theme: keep the execution model dead simple — one thread, in-memory, atomic — and push every source of complexity (durability, replication, sharding) into layers that wrap that core without compromising it.