A developer's guide to how Lucene actually works under the hood: the inverted index, immutable segments, the analyzer pipeline, the indexing and search paths, BM25 scoring, deletes and merging, near-real-time reopen, and the on-disk codec files that engines like Elasticsearch and Solr are built on.
What you should be able to do: Choose field structures and reader/commit behavior while recognizing codec-specific and version-sensitive implementation details.
Assumes basic programming and HTTP. Product defaults, formats, APIs, and guarantees depend on the deployed release/configuration. This is an architecture tutorial; pseudocode and local models are not production integrations.
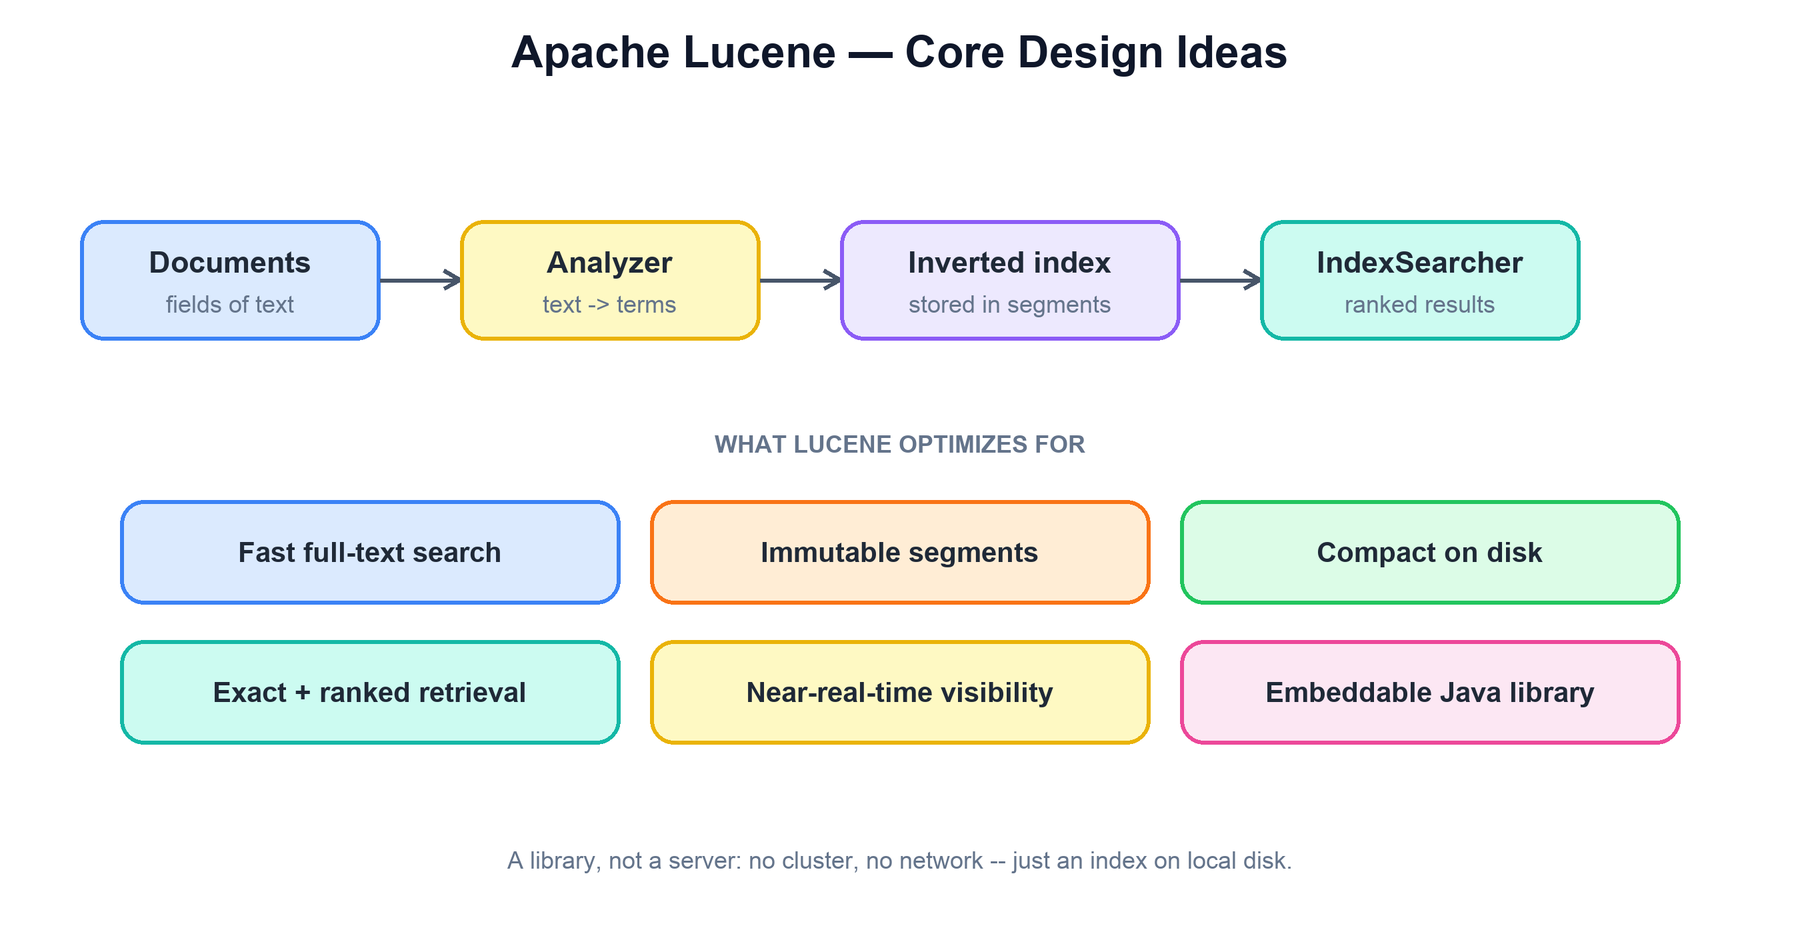
Apache Lucene is a single-machine, embeddable full-text search library written in Java. It is not a server: it has no cluster, no network layer, and no query language of its own — just an API for building an inverted index on local disk and answering ranked queries against it fast. Engines like Elasticsearch and Solr are the distributed half; Lucene is the search engine inside each shard. Almost everything about Lucene follows from two decisions: the core data structure is an inverted index, and that index is stored as a set of immutable segments. Once you understand those two ideas, the indexing path, deletes, merging, and near-real-time search all fall out as consequences.
Read these definitions first, or use the linked terms as you go. The examples and limitations are local to this guide; companion pages are optional.
Analyzers, postings, and doc values
Analysis produces terms/positions; postings map terms to document IDs; doc values organize values by document for sorting/aggregation.
Example. Compatible lowercase analysis matches FOX with fox; phrase matching also needs positions.
Boundary. Index/query analyzers can intentionally differ if compatible. Codec/files/FST details vary by release; field types cannot always vary freely within an index.
BM25 ranking
A ranking heuristic combining term-frequency saturation, rarity, and field-length normalization.
Example. Two matches in a short field may score above two in a long field under the chosen parameters.
Boundary. It is not semantic truth. Analyzer, boosts, shard-local statistics, and similarity implementation affect actual scores.
Refresh, commit, and reader snapshots
Refresh/reopen creates a new searchable view; commit establishes a durable storage boundary. Existing readers keep their snapshot until replaced.
Example. Translog-backed data can be durable yet absent from an old reader. A writer-backed Lucene NRT reader can see uncommitted changes.
Boundary. Flush does not update an existing DirectoryReader. Product WAL/replication policy is distinct from Lucene commit semantics.
Inverted indexes and columnar storage
An inverted index maps searchable terms to document postings. A columnar file groups values by column so analytical scans can read only selected fields. They optimize different access patterns.
Example. 'ERROR' → document IDs {2,7}; 'service=api' → {1,2,7}. Intersection returns {2,7}. A monthly count may instead scan only time, service, and status columns.
Boundary. Tokenization affects meaning, indexes have storage/write cost, and incomplete shard responses must be marked. Search refresh is visibility, not the same as durable commit.
Complexity and workload assumptions
Big-O describes growth with input size under a cost model. Worst-case, expected, amortized, and output-sensitive bounds are distinct promises.
Example. Binary search is O(log n) comparisons on sorted random-access input; printing every subset needs exponential output work.
Boundary. Expected hash-table O(1) is not worst-case O(1). Include output size, recursion space, input assumptions, integer costs, and library operations.
1. Design Goals and Core Ideas
Every internal choice in Lucene serves fast, ranked retrieval over large text collections from a single process. Keeping the goals in mind makes the rest of the design predictable.
Goal
How Lucene achieves it
Fast full-text search
An inverted index maps each term directly to the documents that contain it, so a query reads only the postings for its terms — never the whole collection.
Write-once, read-many storage
Index data lives in immutable segments. Nothing already written is ever modified in place, which makes reads lock-free and files trivially cacheable.
Compact on disk
Terms are stored once in a shared dictionary backed by an FST; postings and doc IDs are delta-encoded and compressed. The index is typically a fraction of the original text size.
Exact and ranked retrieval
Boolean queries find the matching set exactly; a similarity model (BM25 by default) scores and ranks those matches by relevance.
Near-real-time visibility
New documents become searchable by opening a reader over freshly flushed segments — without a full, durable commit.
Embeddable
It is a library you call in-process, not a service you connect to. The distributed concerns (sharding, replication) are left to whoever embeds it.
Documents are analyzed into terms, terms are stored in an inverted index spread across immutable segments, and a searcher answers ranked queries over them.
A useful mental model: Lucene is a library for one index on one machine. If you ever need more than one machine, you do not change Lucene — you run many Lucene indexes and coordinate them above, which is exactly what Elasticsearch and Solr do.
2. The Index Model: Documents & Fields
Documents may omit fields, but field indexing/doc-values/point semantics have compatibility constraints. 'No fixed document schema' does not mean arbitrary type changes are always allowed.
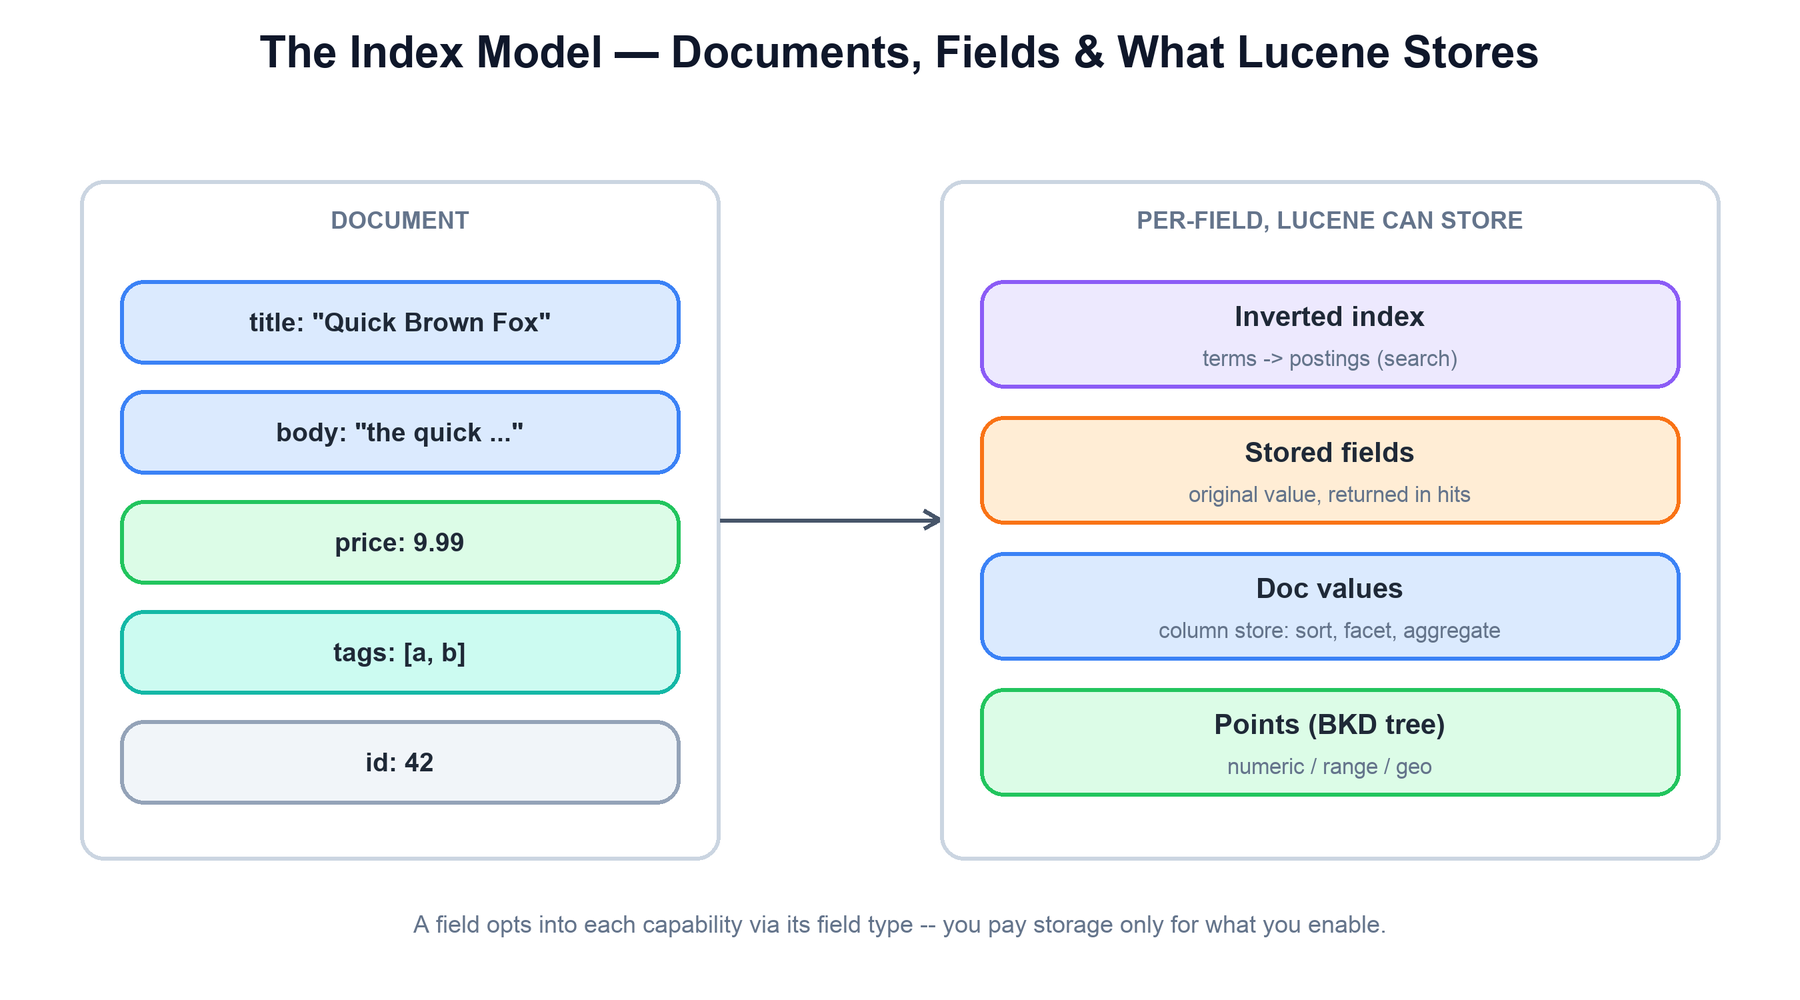
A field can opt into several independent capabilities. You pay storage only for the ones you enable.
A single field can contribute to up to four different structures, each answering a different kind of question:
Indexed (inverted) — the field's text is analyzed into terms and added to the inverted index. This is what makes it searchable.
Stored — the original field value is kept verbatim so it can be returned in a search hit. Storage is for display, not search; stored values are never consulted to match a query.
Doc values — a per-field column store (document → value) used for sorting, faceting, and aggregations, where you need the value for many documents rather than the documents for a value.
Points — numeric, date, and geo fields are indexed in a BKD tree (a disk-friendly k-d tree) for efficient range and nearest-neighbor lookups, which an inverted index handles poorly.
The same logical field, say price, is often configured for several of these at once — a point for range filters, a doc value for sorting, and stored for display — because each backs a different access pattern.
3. Analysis: Text to Terms
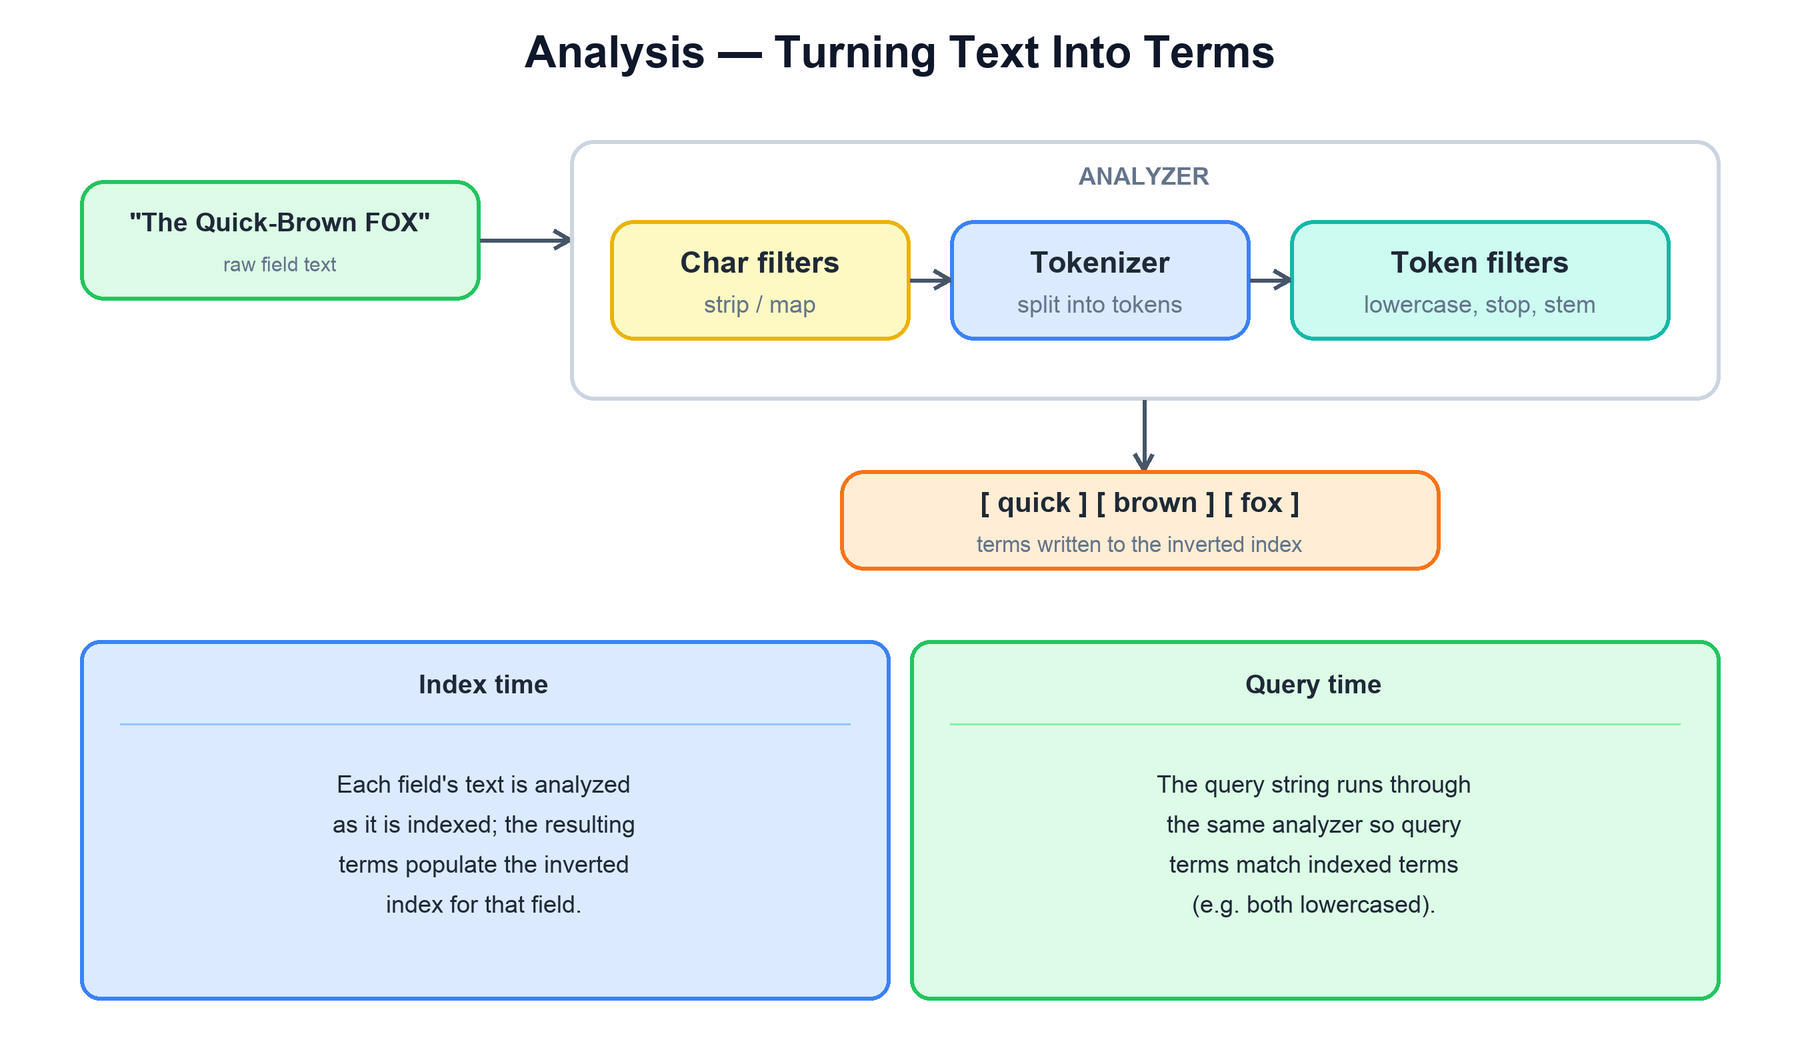
Text is not indexed as-is. Before it reaches the inverted index it passes through an analyzer, a pipeline that turns a raw string into a stream of normalized terms. The analyzer has three stages.
Character filters clean the raw text, the tokenizer splits it into tokens, and token filters normalize each token into the final indexed terms.
Character filters preprocess the raw character stream — for example stripping HTML tags or mapping characters.
The tokenizer splits the stream into tokens, typically on whitespace and punctuation. Each token also carries a position and an offset back into the original text.
Token filters transform the token stream: lowercasing, removing stop words, folding accents, and stemming words to a root form (running → run).
function analyze(text, analyzer):
  text   = analyzer.char_filters.apply(text)   # e.g. strip HTML
  tokens = analyzer.tokenizer.split(text)       # "Quick-Brown" -> Quick, Brown
  for f in analyzer.token_filters:
    tokens = f.apply(tokens)                     # lowercase, stop, stem
  return tokens                                  # -> [quick, brown, fox]
The same analyzer runs at index time and at query time. If "FOX" is indexed as the term fox, then a search for "Fox" must be analyzed to fox too, or it would never match. Mismatched index- and query-time analysis is the single most common cause of "why doesn't my search find anything?".
4. The Inverted Index
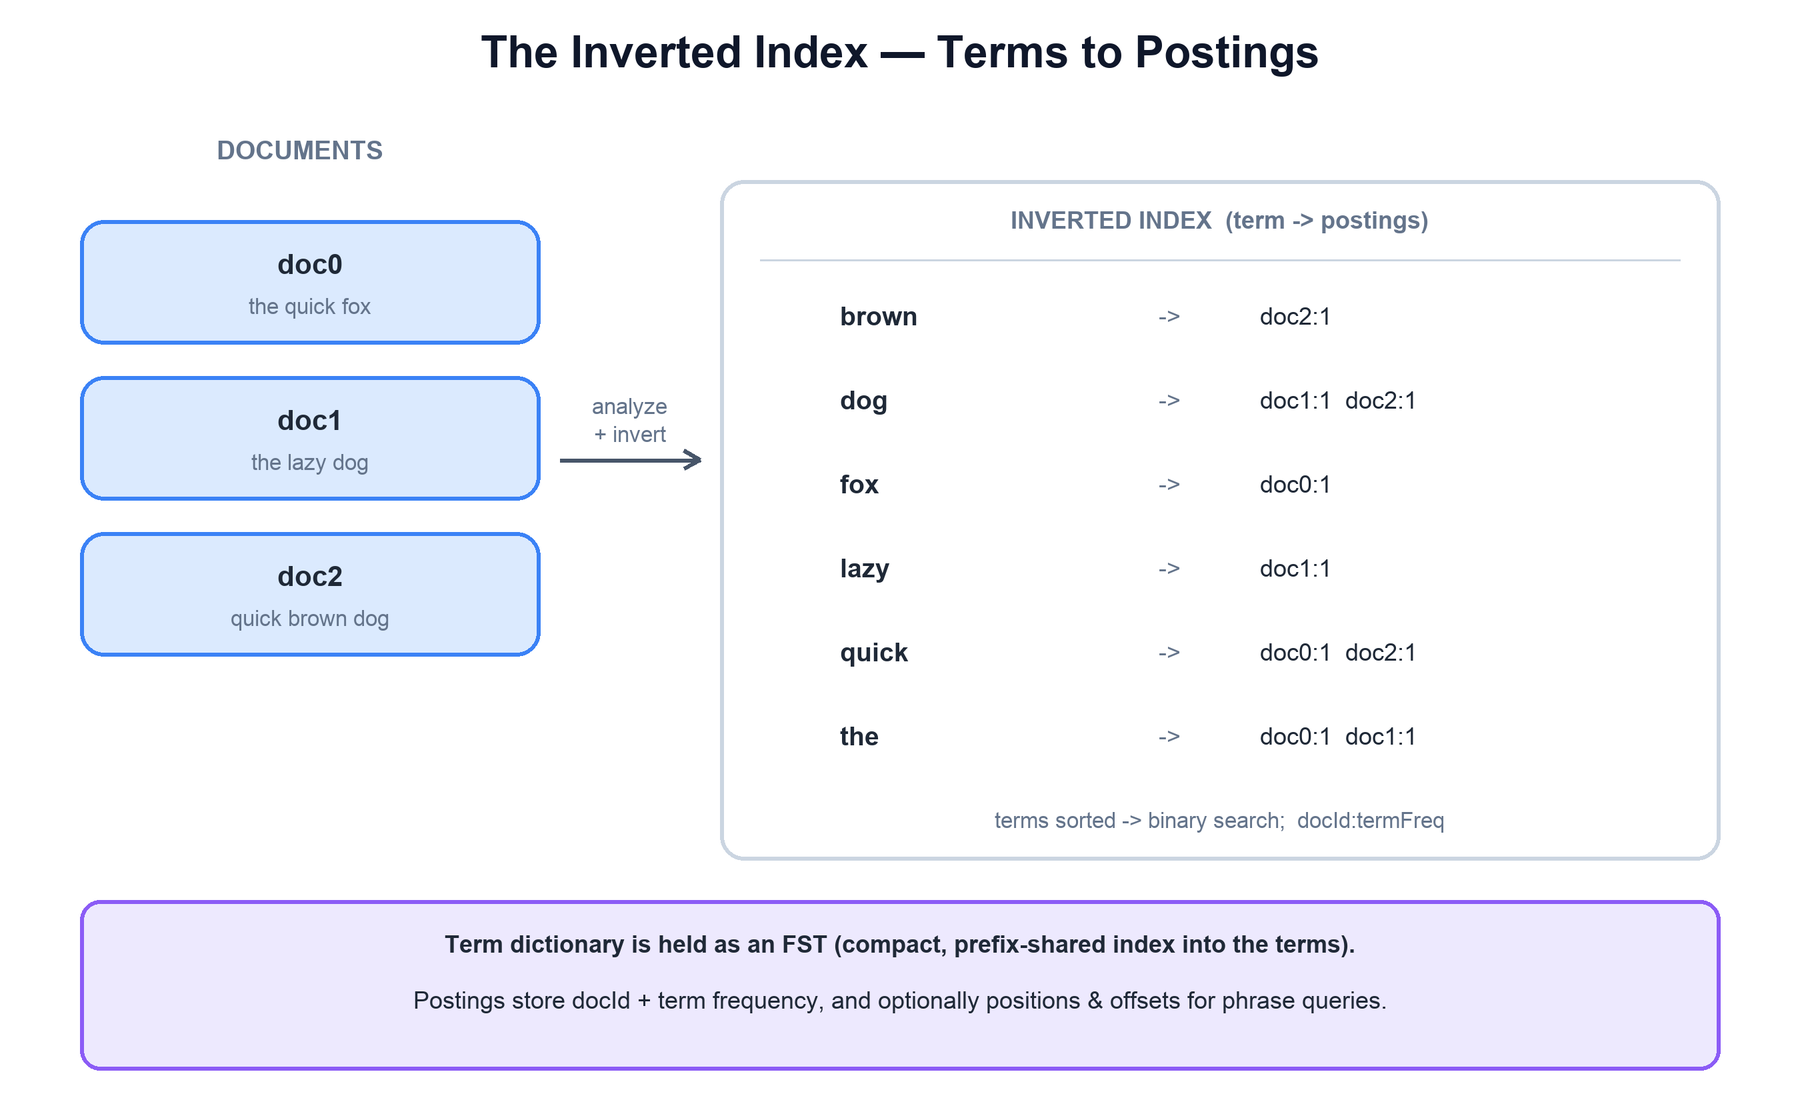
The inverted index is the heart of Lucene. Instead of mapping documents to the terms they contain (a "forward" index), it maps each term to the list of documents that contain it — its postings list. Answering a query then means reading a few short postings lists rather than scanning every document.
Documents are analyzed into terms; each term points to a postings list of the documents that contain it, with term frequencies (and optionally positions).
Lucene codecs use compact term dictionaries/indexes, historically including BlockTree/FST structures. Exact formats and acceleration structures depend on codec/version.
Because the term dictionary is sorted and postings are stored as ascending document IDs, Boolean queries become efficient list operations. An AND of two terms is a merge-intersection that skips through the shorter list:
function intersect(postingsA, postingsB):     # docs containing BOTH terms
  result = []
  a = postingsA.first();  b = postingsB.first()
  while a != END and b != END:
    if a.doc == b.doc:
      result.add(a.doc);  a = postingsA.next();  b = postingsB.next()
    elif a.doc < b.doc:
      a = postingsA.advance(b.doc)            # skip-list jump, not linear scan
    else:
      b = postingsB.advance(a.doc)
  return result
Postings carry skip lists, so advance(target) can jump ahead instead of stepping one document at a time — which is what keeps multi-term queries fast even on long lists.
5. Segments & Commits
Segments hold mostly immutable indexed data; live-doc/deletion and some update state use versioned files/metadata. Immutability simplifies concurrency, but writers, publication, references, and reader lifetimes still require synchronization. Existing readers retain their snapshot.
A commit safely records the live segment set under the Directory/IndexWriter storage protocol. OS cache/flush is not a durable commit, and arbitrary file writes are not equivalent to the API's crash-safe publication. Keep referenced old files until readers/commits release them.
6. The Indexing Path
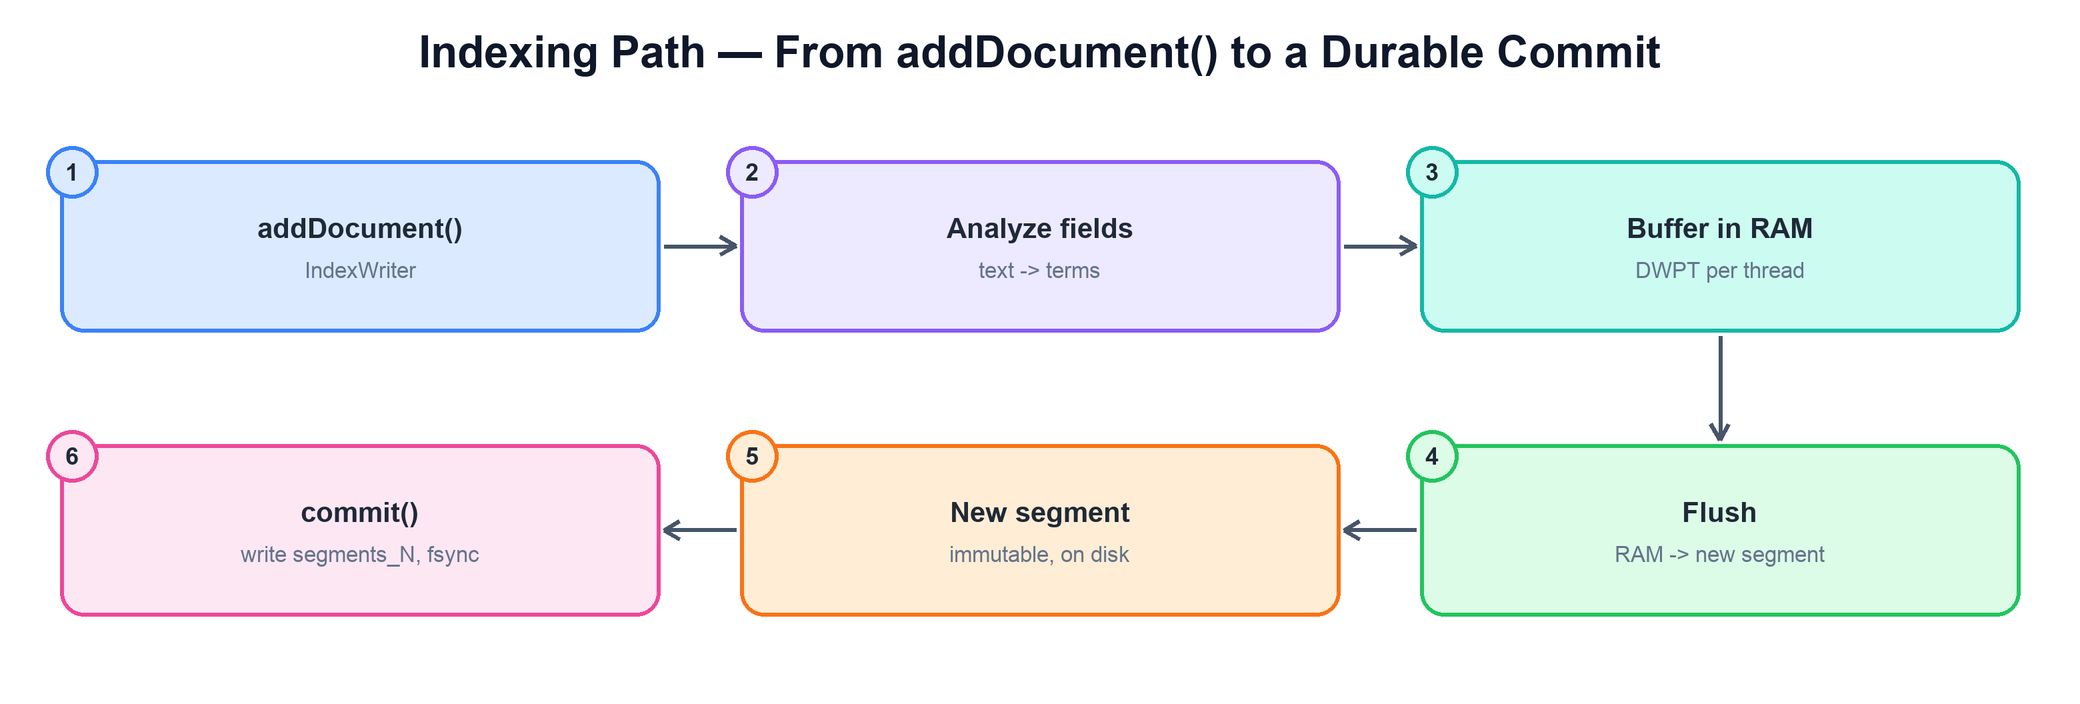
The class that writes to an index is the IndexWriter. Only one may have a given index open for writing at a time (enforced by a write lock). Adding documents flows through an in-memory buffer and out to a new segment.
Documents are analyzed and buffered in RAM per indexing thread, flushed to a new immutable segment, and made durable by a commit.
Step by step:
Buffer. Each indexing thread fills its own DocumentsWriterPerThread (DWPT) — an in-memory mini-index. Per-thread buffers avoid contention so many threads can index in parallel.
Flush. When a buffer fills (by RAM budget or document count), it is flushed: its in-memory inverted index is serialized to disk as a brand-new segment. After a flush the segment exists, but a crash could still lose it.
Commit. A commit fsyncs the flushed segments and writes a new segments_N, making everything since the last commit durable.
writer = IndexWriter(directory, config)
for doc in source:
  writer.addDocument(analyze(doc))   # into this thread's DWPT (RAM)
  if dwpt.ram_used > flush_threshold:
    segment = dwpt.flush_to_disk()   # new immutable segment, not yet durable
writer.commit()                      # fsync + write segments_N (durable)
writer.close()
Flushing and committing are different events. Flush makes documents searchable (a new segment exists); commit makes them durable (survives a crash). Near-real-time search exploits exactly this gap — see §11.
7. The Search Path
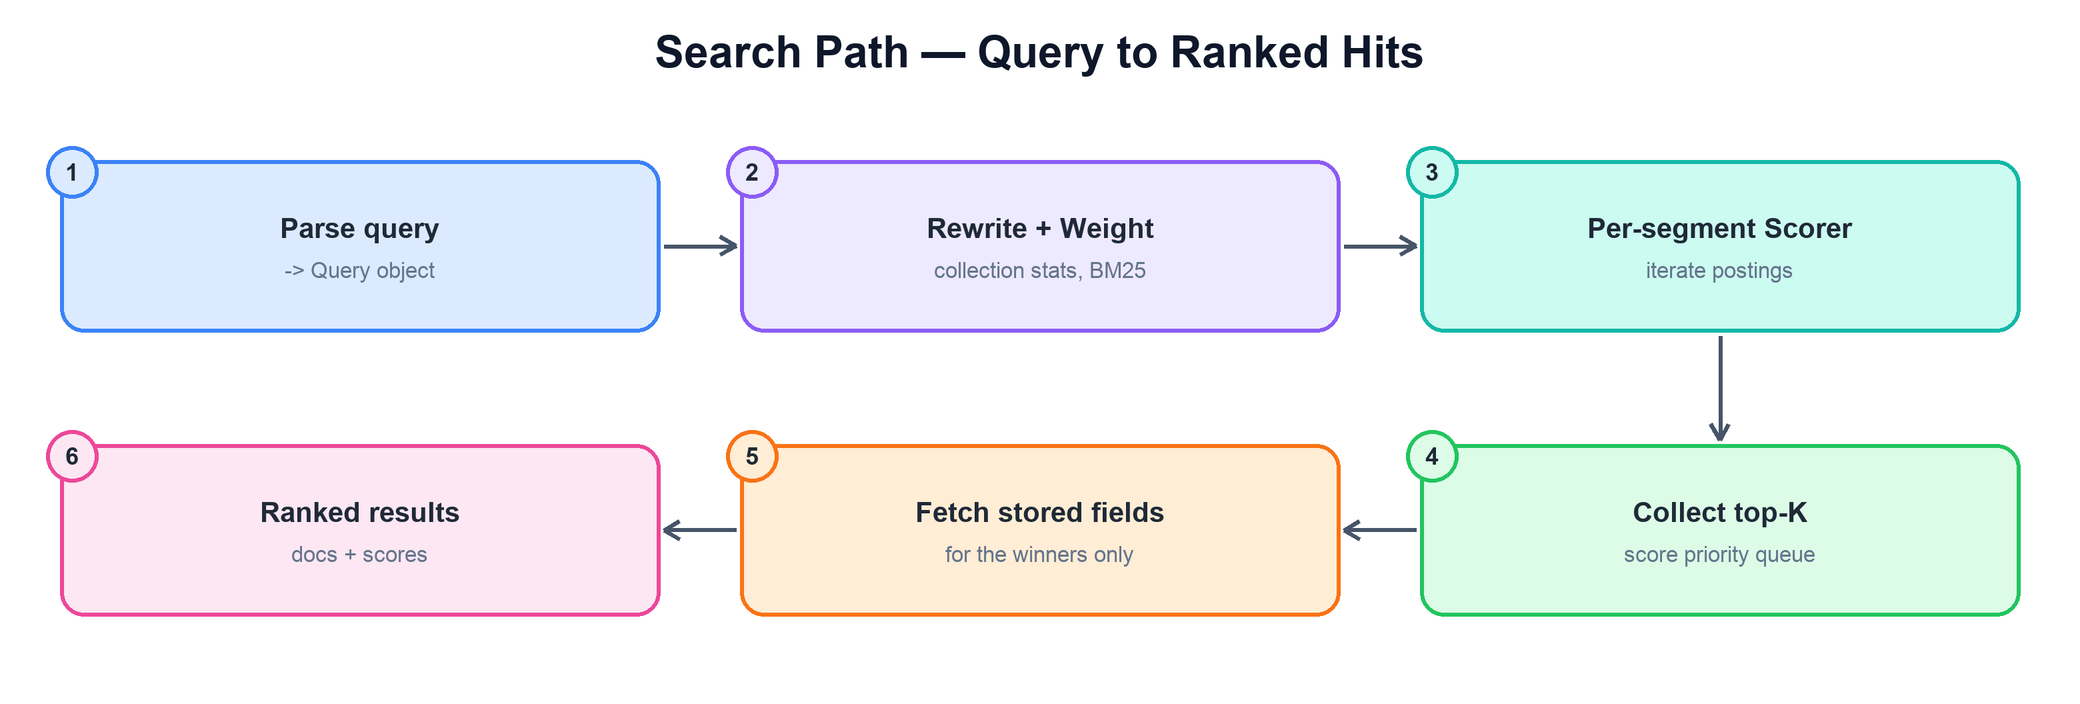
Reading is done through a DirectoryReader, which opens one leaf reader per segment, wrapped by an IndexSearcher. A query is not executed directly; it is compiled into objects that know how to iterate postings and produce scores.
A query is rewritten into a Weight, executed as a per-segment Scorer over postings, collected into a top-K queue, and only the winners have their stored fields fetched.
The pipeline is:
Query → Weight. The Query is rewritten (e.g. a wildcard expands to the terms it matches) and turned into a Weight that captures collection-level statistics for scoring.
Weight → Scorer, per segment. For each segment the Weight produces a Scorer that walks the relevant postings, yielding matching document IDs and their scores. Segments are searched independently — and can be searched concurrently.
Collect. A Collector (typically a bounded min-heap / priority queue) keeps only the top-K highest-scoring hits, so the engine never sorts the full match set.
Fetch. Only for the K winners does Lucene read stored fields to hydrate the result. The expensive disk reads happen for a handful of documents, not the whole match set.
searcher = IndexSearcher(DirectoryReader.open(directory))
weight   = searcher.createWeight(query)        # stats for scoring
topk     = PriorityQueue(maxsize = K)          # keep best K by score

for leaf in searcher.leaves():                 # one per segment
  scorer = weight.scorer(leaf)
  for doc in scorer:                           # skip-list iteration over postings
    if leaf.live_docs.get(doc):                # skip deleted docs
      topk.insert(doc, scorer.score())

return [fetch_stored_fields(hit) for hit in topk.sorted()]   # only the K winners
8. Relevance Scoring (BM25)
Boolean matching decides which documents qualify; a similarity decides their order. Lucene's default is BM25, which scores a document for a query term from three intuitive signals.
Signal
Meaning
Effect on score
Term frequency (tf)
How often the term appears in the document.
More occurrences raise the score, but with diminishing returns — the tenth occurrence adds far less than the second.
Inverse document frequency (idf)
How rare the term is across the whole index.
Rare terms are more discriminating, so they count for more; common terms count for little.
Field length
Length of the field, vs. the average length.
A match in a short field is worth more than the same match buried in a long one (length normalization).
The two tunables are k1 (how quickly extra term occurrences stop helping) and b (how strongly long fields are penalized). The idf values come from the collection statistics captured in the Weight, which is why scoring needs that rewrite step before iteration.
9. Deletes & Updates
Hard deletion marks documents nonlive in the reader's versioned state; physical bytes may remain until merge/cleanup. Soft-delete policies retain selected old versions. Delete visibility follows reader refresh, not necessarily the instant of the write call.
IndexWriter.updateDocument provides supported atomic delete-and-add behavior with respect to readers. Describing it as two independent public calls loses that guarantee. Updates/deletes that match several documents follow their API contract; a field's logical meaning and uniqueness constraints are the application responsibility.
Physical reclamation is affected by merges, retained commits, reader references, and supported cleanup. Do not call merge the only possible route for every obsolete file to leave storage.
10. Segment Merging
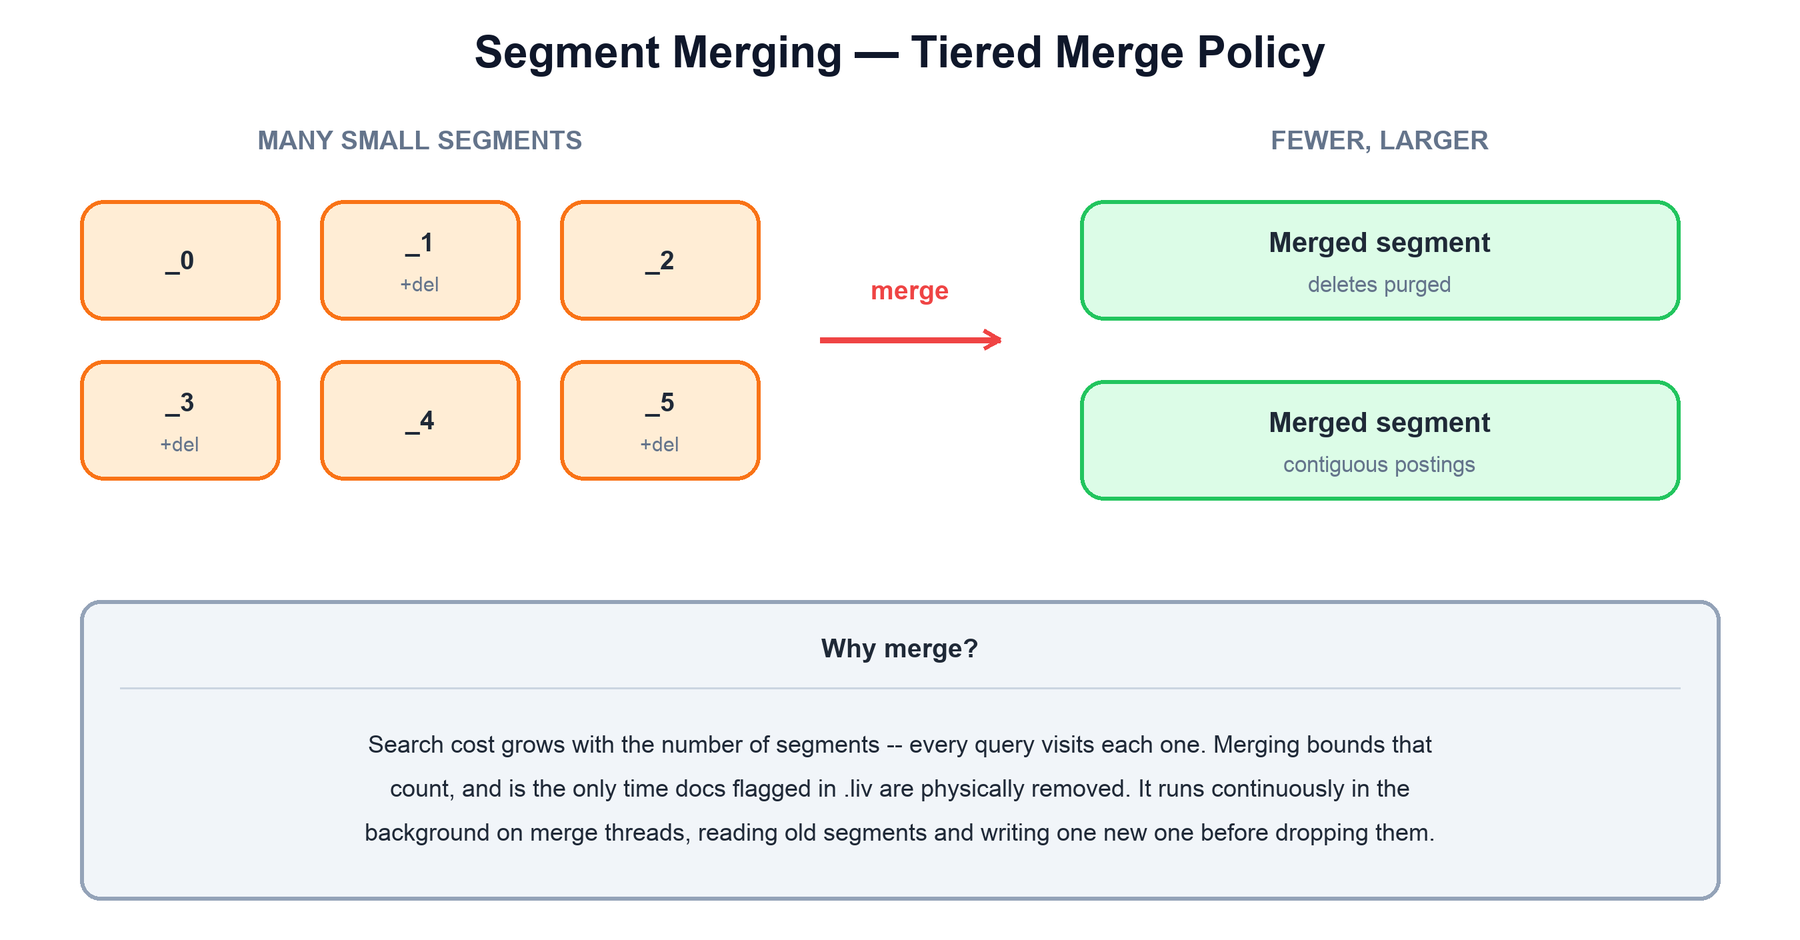
Flushing constantly produces new, small segments, and deletes leave dead documents behind. Left alone, an index would drift toward thousands of tiny segments — and every query has to visit every segment. Merging is the background process that keeps this in check by combining several segments into one larger segment.
Many small segments (some carrying deletes) are merged into fewer, larger ones, and documents tombstoned in .liv are physically dropped in the process.
Merging does two things at once:
Bounds the segment count. Fewer segments means fewer postings lists to open and intersect per query, so search stays fast as the index grows.
Reclaims deleted space. A merge reads only the live documents from the input segments, so tombstoned documents are physically dropped — this is the only time deleted data actually leaves the disk.
A MergePolicy decides which segments to merge and when. The default, TieredMergePolicy, groups segments into size tiers and merges within a tier, preferring segments with many deletes. Merges run on background threads, reading the inputs and writing one new segment before the old ones are dropped at the next commit — so search continues uninterrupted while a merge is in flight.
function maybeMerge(segments, policy):       # runs continuously in background
  candidates = policy.findMerges(segments)   # by size tier + delete ratio
  for group in candidates:
    new_seg = merge(group.live_documents())  # dead docs excluded here
    atomically_replace(group -> new_seg)     # visible at next commit
11. Near-Real-Time Search
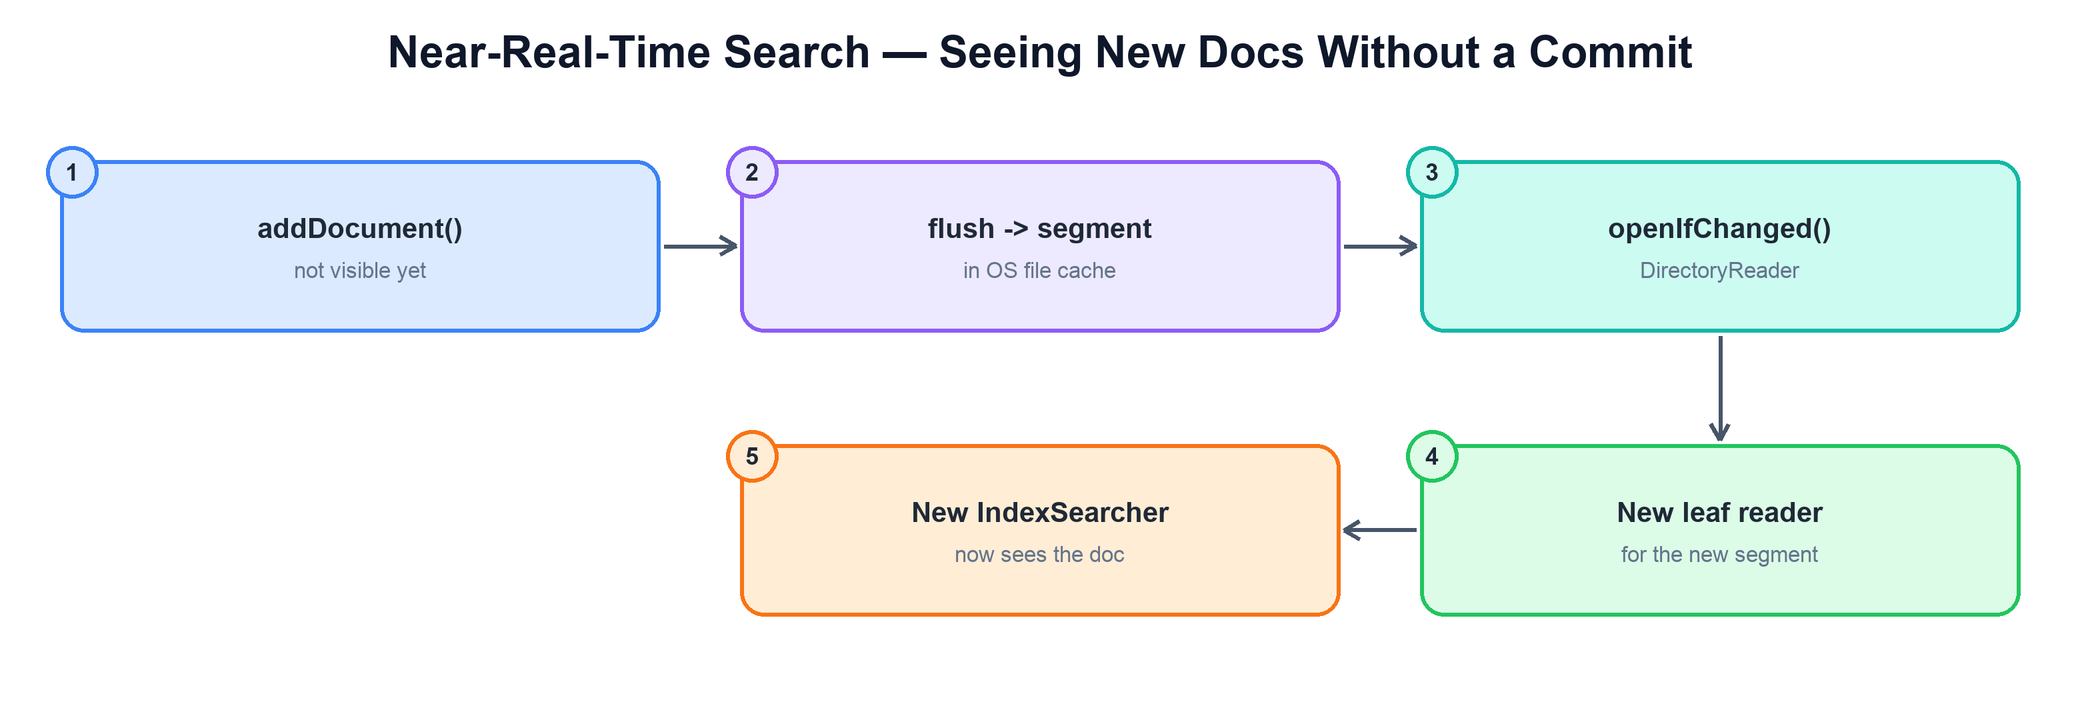
A new document is searchable as soon as it is in a segment — and a flush creates a segment without a durable commit. Near-real-time (NRT) search exploits that gap: instead of committing (an fsync, which is slow), you open a reader over the just-flushed segments straight from the OS file cache.
A flushed segment in the OS cache is picked up by reopening the reader — no durable commit required — so the new document becomes visible in milliseconds.
The mechanism is reader reopen. Rather than building a fresh reader from scratch, DirectoryReader.openIfChanged(oldReader) returns a new reader that reuses the leaf readers for unchanged segments and only opens leaves for the new ones. Because segments are immutable, this sharing is safe and cheap.
reader = DirectoryReader.open(writer)        # NRT reader tied to the writer
... index more documents ...
newReader = DirectoryReader.openIfChanged(reader)   # picks up flushed segments
if newReader != null:
  reader.close()                             # old leaves not reused are released
  reader = newReader
searcher = IndexSearcher(reader)             # now sees the new documents
NRT decouples visibility from durability. Reopening makes documents visible in milliseconds without fsync; a separate, less frequent commit provides crash durability. Engines built on Lucene add a write-ahead log of their own (Elasticsearch's translog) to cover the window between flushes.
12. Segment Files & Codecs
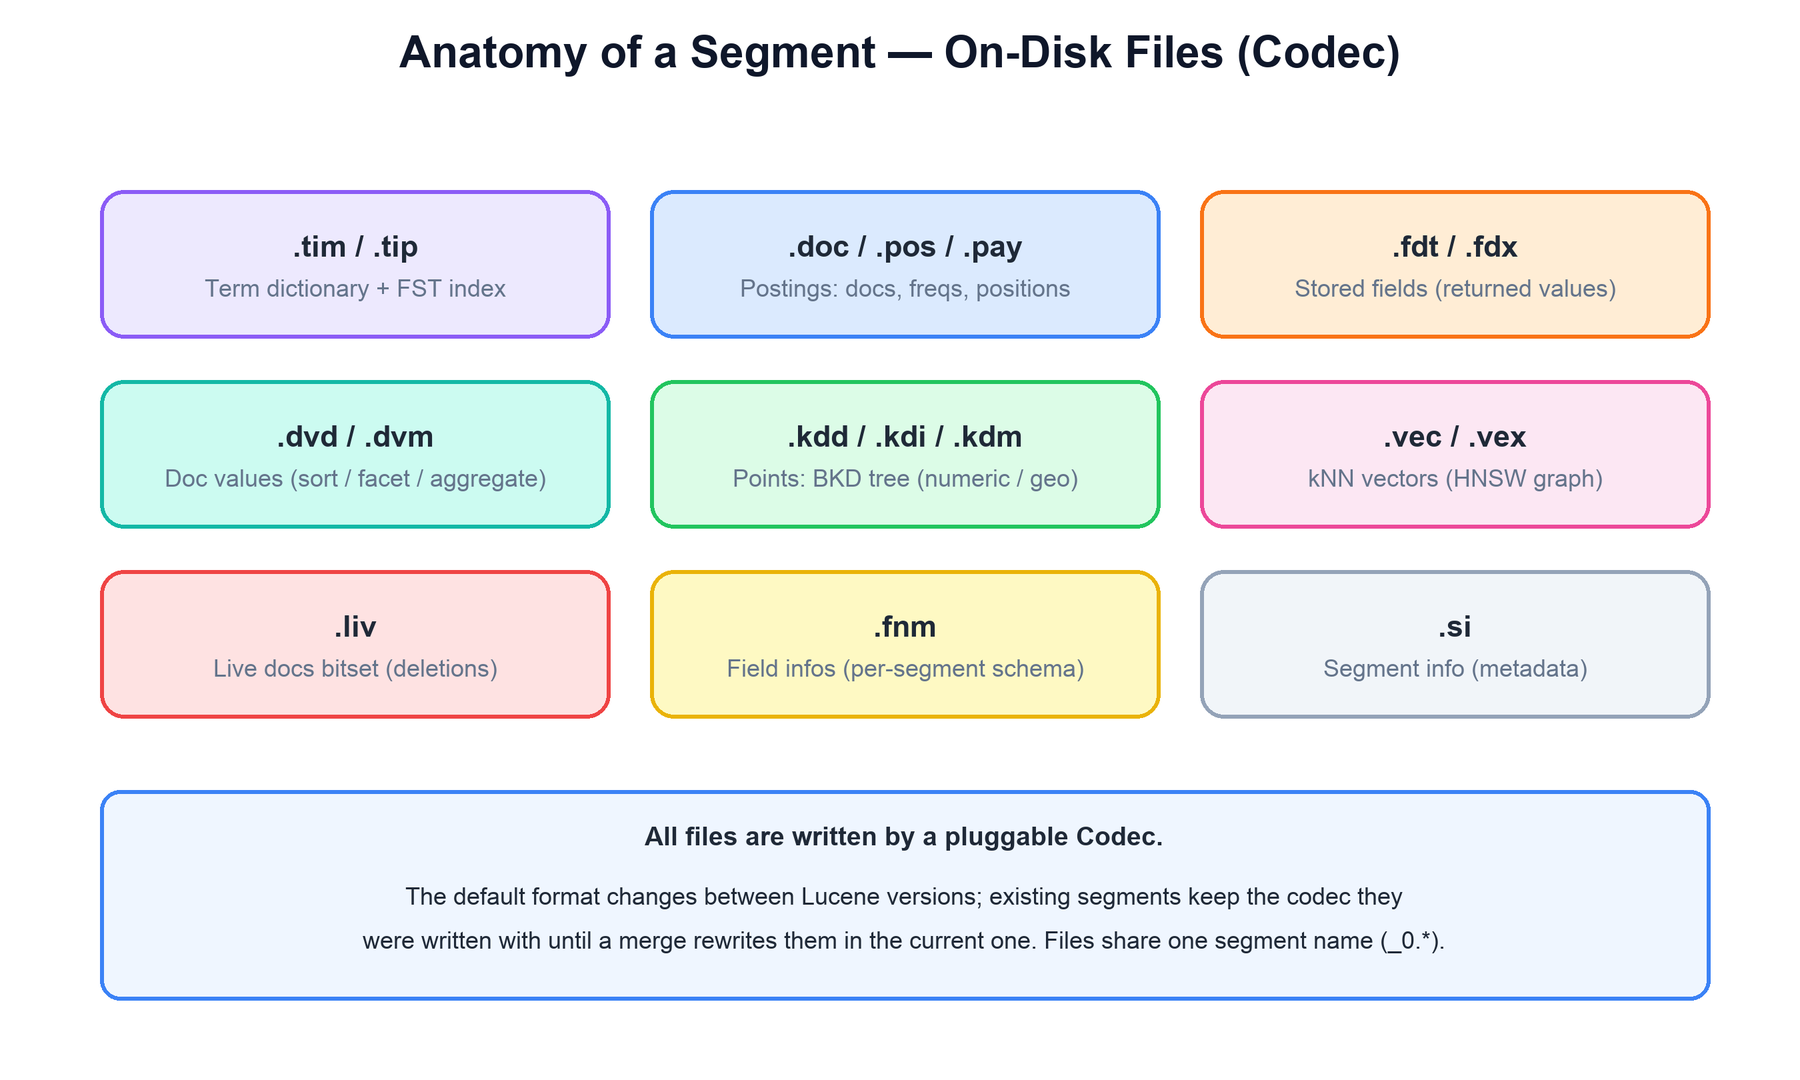
A single segment is physically a group of files that share one base name (_0.tim, _0.doc, …), each holding one part of the inverted index. The component that reads and writes these files is the Codec, and it is pluggable.
The files that make up one segment, each written by the codec for a specific structure.
Files
Hold
.tim / .tip
Term dictionary and its FST term index.
.doc / .pos / .pay
Postings: document IDs and frequencies, term positions, and payloads/offsets.
.fdt / .fdx
Stored field values and their index (returned in hits).
.dvd / .dvm
Doc values: the per-field column store for sort, facet, and aggregate.
.kdd / .kdi / .kdm
Points: the BKD tree for numeric, date, and geo fields.
.vec / .vex
kNN vector values and the HNSW graph for nearest-neighbor search.
.liv
Live-docs bitset recording deletions for this segment.
.fnm
Field infos: the per-segment record of which fields exist and how they were indexed.
.si
Segment info: metadata such as document count and the codec used.
Because the codec is recorded per segment, an index can hold segments written by different codec versions at once. When Lucene upgrades its default format, existing segments keep the codec they were written with until a merge rewrites them in the current one — which is why merging is also how a format upgrade physically happens.
Worked example: two reader snapshots
Work through the following bounded example and its failure boundary.
Sequence for this example. The table explains the evidence and decision at each step.
Step
Evidence, decision, and expected result
Open a reader at commit/view V1
It sees its captured segments/live-document state, not all future writer changes.
Add a new document
The writer buffers/flushes under its policy. Existing reader V1 still sees its earlier view.
Open/reopen a writer-backed NRT reader
It can see eligible uncommitted changes. Durable commit is a separate requirement for crash recovery.
Update a document atomically
Use the API's supported update operation. Two separate public delete/add calls are not automatically one reader-visible atomic update.
Check your understanding: Does flushing update every existing reader?
No. Readers are snapshots. Visibility needs a suitable reopen/new reader; durable commit and physical file cleanup are separate.
Run and change the example
Download guide_labs.py. Python 3.10+, standard library only. In its directory, run:
python3 guide_labs.py index
python3 guide_labs.py test
The model demonstrates stable reader snapshots and mutable writer state; it is not a Lucene codec.
The program tests its stated finite contracts. It is an educational model, not an implementation of the named production product or a proof of unmodeled distributed faults.
Lucene is a small set of ideas that compose into fast, ranked, durable search on a single machine:
Concern
Mechanism
What makes search fast?
An inverted index: each term points straight to a postings list of its documents, read with skip lists.
How is the index stored?
As immutable segments — small, complete sub-indexes — named by an atomic commit point (segments_N).
How does text become searchable?
An analyzer (char filters → tokenizer → token filters) turns it into terms, with the same analysis at index and query time.
How are documents written?
IndexWriter buffers them per thread (DWPT), flushes to a new segment, and commits to make them durable.
How are results ranked?
BM25 scoring from term frequency, inverse document frequency, and field-length normalization.
How do deletes and updates work?
Tombstones in a live-docs bitset; an update is a delete-by-term plus an add. Space is reclaimed only on merge.
How does the index stay fast over time?
Background merging bounds the segment count and physically drops deleted documents.
How are new documents seen quickly?
Near-real-time reopen over flushed segments, reusing unchanged leaf readers — visibility without an fsync.
How is the on-disk format defined?
A pluggable per-segment codec writing one file group per structure (terms, postings, stored, doc values, points, vectors).
The recurring theme: Lucene writes immutable segments and never edits them. Indexing appends new segments, deletes layer a bitset on top, merging rewrites them, and search reads them lock-free. Everything else — durability, near-real-time visibility, even format upgrades — is built on that one decision.