A developer's guide to how Elasticsearch actually works under the hood: the distributed layer over Lucene, node roles and cluster state, shards and routing, the inverted index, the indexing and query paths, and how near-real-time search is achieved.
Student edition · understand, apply, verify
Separate indexed durability, search refresh, replica state, and query completeness.
What you should be able to do: Explain stale search results after a successful write and prevent lost concurrent document updates using version conditions.
Assumes basic programming and HTTP. Product defaults, formats, APIs, and guarantees depend on the deployed release/configuration. This is an architecture tutorial; pseudocode and local models are not production integrations.
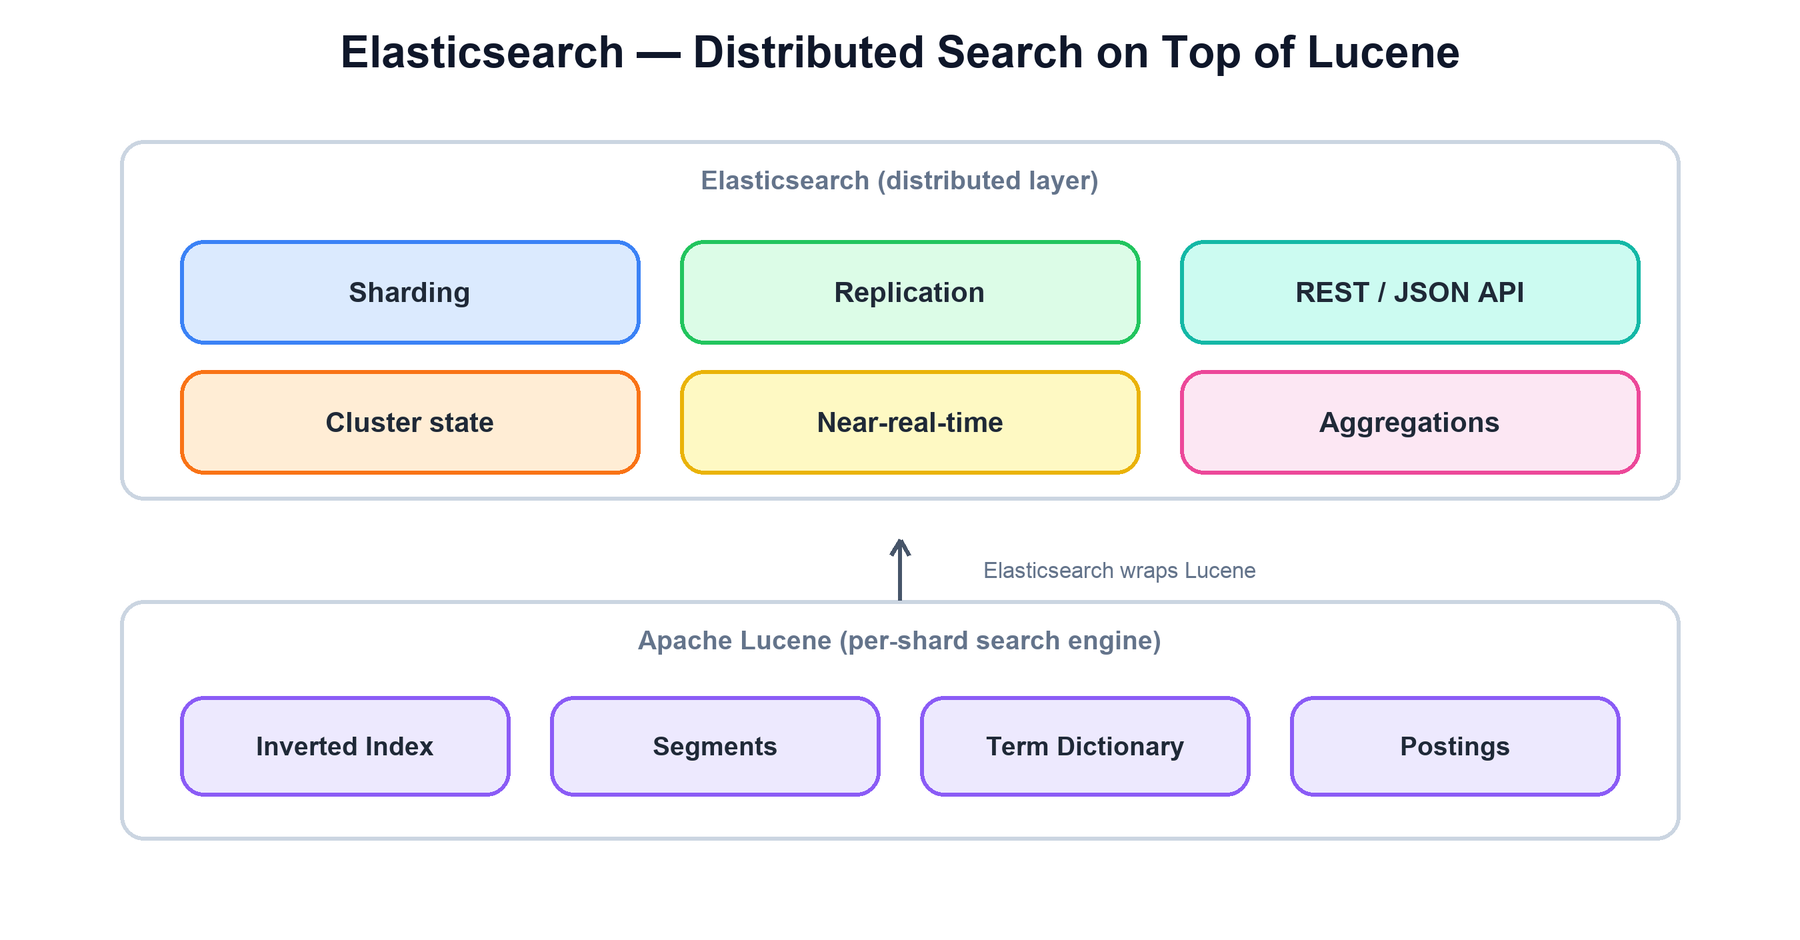
Elasticsearch is a distributed search and analytics engine built on top of Apache Lucene. Lucene is a single-machine, full-text search library: it stores an inverted index and answers term queries fast, but it knows nothing about clusters, networks, or replication. Elasticsearch wraps many Lucene indexes and adds the distributed half: it shards data across nodes, replicates each shard for safety, elects a master to manage cluster state, and exposes everything through a JSON-over-HTTP API. Understanding Elasticsearch means understanding how that distributed layer coordinates a fleet of independent Lucene engines.
Read these definitions first, or use the linked terms as you go. The examples and limitations are local to this guide; companion pages are optional.
Refresh, commit, and reader snapshots
Refresh/reopen creates a new searchable view; commit establishes a durable storage boundary. Existing readers keep their snapshot until replaced.
Example. Translog-backed data can be durable yet absent from an old reader. A writer-backed Lucene NRT reader can see uncommitted changes.
Boundary. Flush does not update an existing DirectoryReader. Product WAL/replication policy is distinct from Lucene commit semantics.
Analyzers, postings, and doc values
Analysis produces terms/positions; postings map terms to document IDs; doc values organize values by document for sorting/aggregation.
Example. Compatible lowercase analysis matches FOX with fox; phrase matching also needs positions.
Boundary. Index/query analyzers can intentionally differ if compatible. Codec/files/FST details vary by release; field types cannot always vary freely within an index.
Inverted indexes and columnar storage
An inverted index maps searchable terms to document postings. A columnar file groups values by column so analytical scans can read only selected fields. They optimize different access patterns.
Example. 'ERROR' → document IDs {2,7}; 'service=api' → {1,2,7}. Intersection returns {2,7}. A monthly count may instead scan only time, service, and status columns.
Boundary. Tokenization affects meaning, indexes have storage/write cost, and incomplete shard responses must be marked. Search refresh is visibility, not the same as durable commit.
Optimistic concurrency and compare-and-set
Update state only if the expected version or status still matches, in the same atomic operation that changes it. A failed comparison means a conflicting operation won; reread or return a conflict.
Example. UPDATE seats SET status='held', version=version+1 WHERE id=? AND status='available' allows only one concurrent claimant to update the row.
Boundary. Application-level GET then unconditional SET is not equivalent. Include acquisition identity to reject stale callbacks, and couple related invariants in a transaction.
Offsets and checkpoints
An offset is a position in one log partition. A checkpoint is a recoverable, consistent record of input positions and processing state. On restart, state must correspond exactly to the input that is considered processed.
Example. If a batch increments a total and crashes before saving its offset, replay increments twice. Commit the total, dedup state, and partition position together, or use a compatible transactional/idempotent sink.
Boundary. Saving an offset after a write avoids that specific loss window but can still duplicate; framework checkpoints alone do not make arbitrary external effects transactional.
Schema compatibility and semantic contracts
Backward compatibility lets new readers read old data; forward lets old readers read new data. Field identity/default rules differ by format.
Example. Milliseconds changed to seconds under an unchanged integer field is a breaking semantic change.
Boundary. Optional is not universally safe. Registry checks are configured structural rules, not business semantics; schema-ID headers are format/vendor conventions, not Kafka itself.
1. Design Goals and Core Ideas
Every design choice in Elasticsearch follows from one ambition: take Lucene's fast single-machine full-text search and make it distributed, horizontally scalable, and near-real-time, without giving up the rich query and aggregation capabilities developers expect.
Goal
How Elasticsearch achieves it
Full-text search at scale
Each shard is a self-contained Lucene index with an inverted index; queries run in parallel across shards.
Horizontal scalability
An index is split into shards spread across data nodes. Add nodes and shards relocate to use the new capacity.
High availability
Every primary shard has one or more replicas on other nodes. Lose a node and a replica is promoted.
Near-real-time
New documents become searchable within a refresh interval (about one second), not instantly, trading a little latency for throughput.
Analytics, not just search
Doc-values columnar storage and aggregations let the same engine compute metrics, histograms, and facets.
Elasticsearch is the distributed layer (sharding, replication, cluster state, REST API) wrapped around per-shard Lucene engines.
2. Cluster Architecture and Node Roles
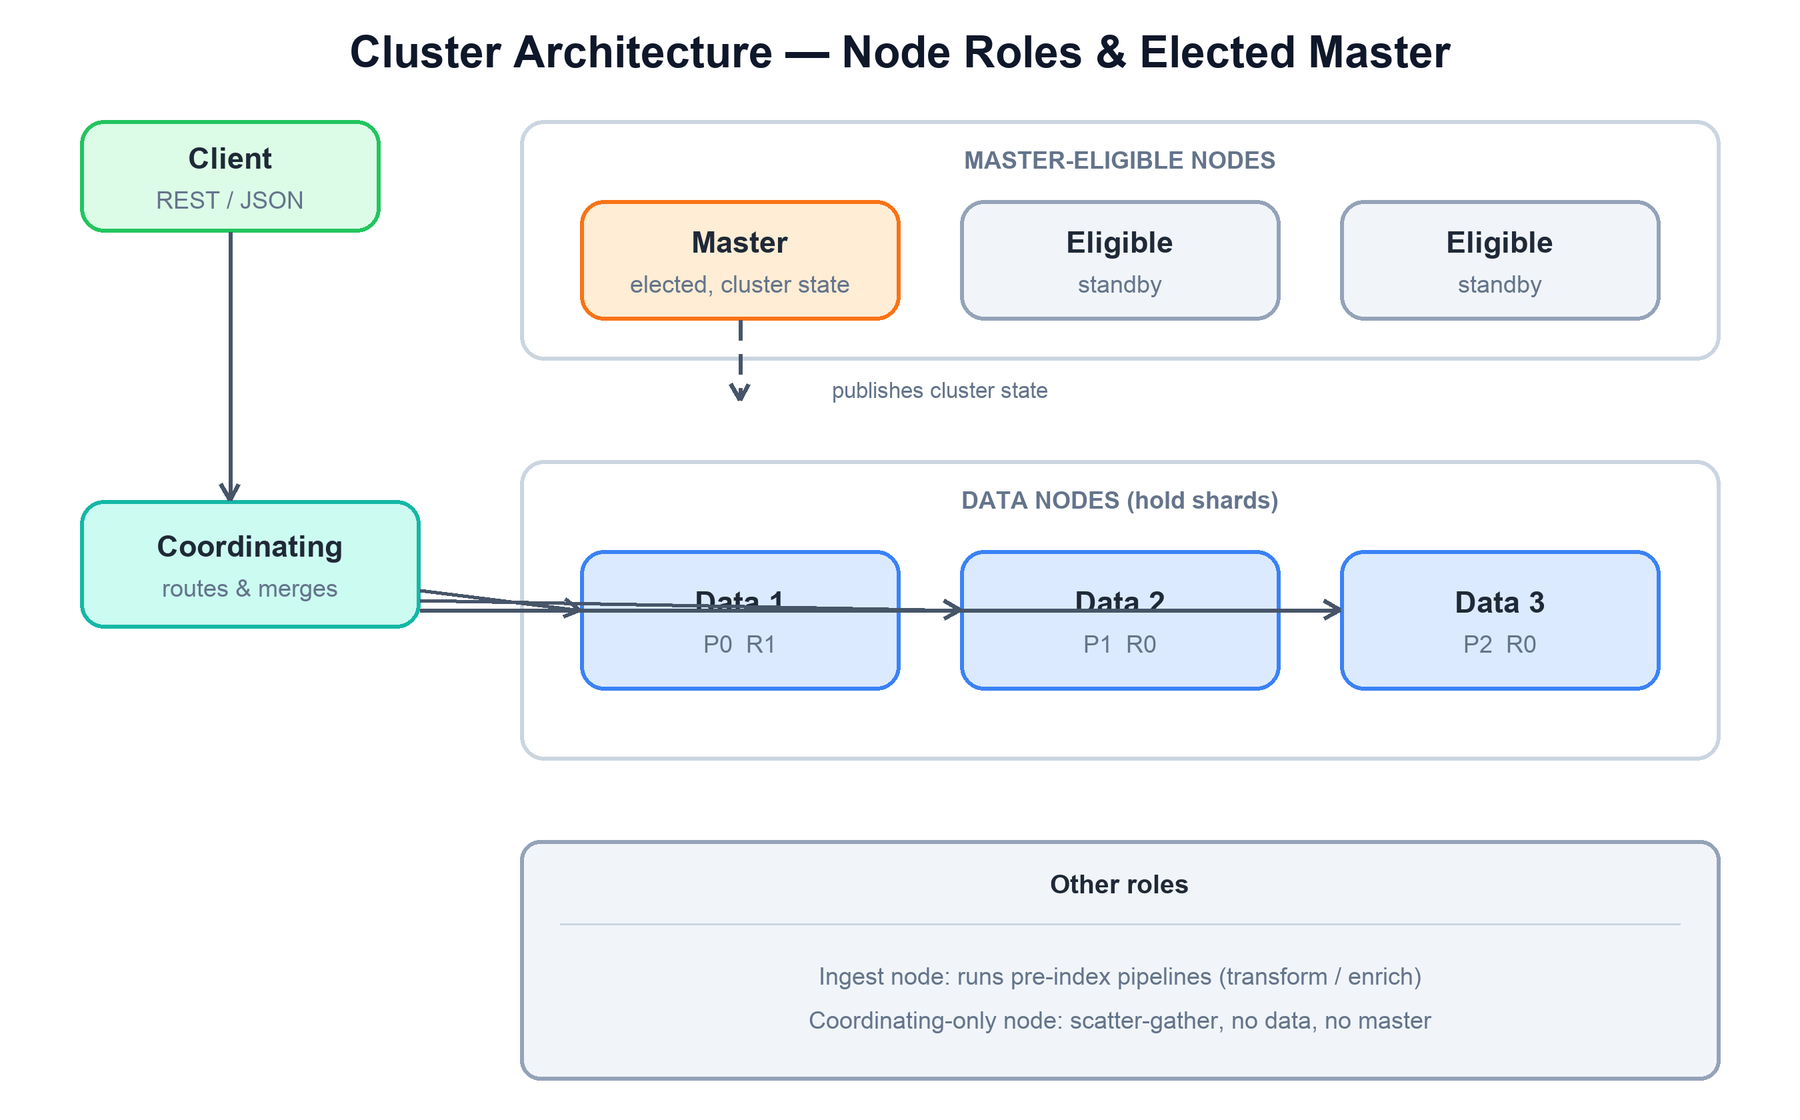
An Elasticsearch cluster is a set of nodes that share a cluster name. Unlike a fully peer-to-peer system, Elasticsearch has an elected master that owns the cluster's metadata. The master does not sit in the data path — it manages the cluster state: the list of nodes, index mappings and settings, and which shard lives on which node. Every node holds a copy of the cluster state, and the master publishes updates to all of them.
The elected master manages cluster state; data nodes hold shards; coordinating nodes scatter and gather requests.
Nodes are configured with one or more roles:
Master-eligible: can be elected master. The cluster elects exactly one active master from this pool. The master applies cluster-state changes — creating indices, allocating shards, processing node joins and departures — and publishes the new state. Master-eligible nodes form a voting configuration; a quorum of them must agree to elect a master and to commit each state change.
Data: holds shards (primaries and replicas) and does the actual indexing and searching. This is where Lucene runs and where disk and memory pressure live.
Coordinating: a role every node can play. The node that receives a client request becomes the coordinating node for it: it routes sub-requests to the right shards, gathers responses, merges them, and replies. A node with no other roles is a dedicated coordinating-only node — a smart load balancer.
Ingest: runs ingest pipelines that transform or enrich documents before they are indexed (parsing, field renaming, lookups), offloading that work from data nodes.
Discovery is how nodes find each other and form the cluster. On startup a node contacts a configured list of seed hosts, learns about other master-eligible nodes, and participates in master election. Once a master is elected, it admits new nodes by adding them to the cluster state and publishing it. Failure detection runs continuously: the master pings the other nodes and they ping the master; a node that stops responding is removed from the cluster state, and the master reallocates its shards.
3. Indices, Shards and Routing
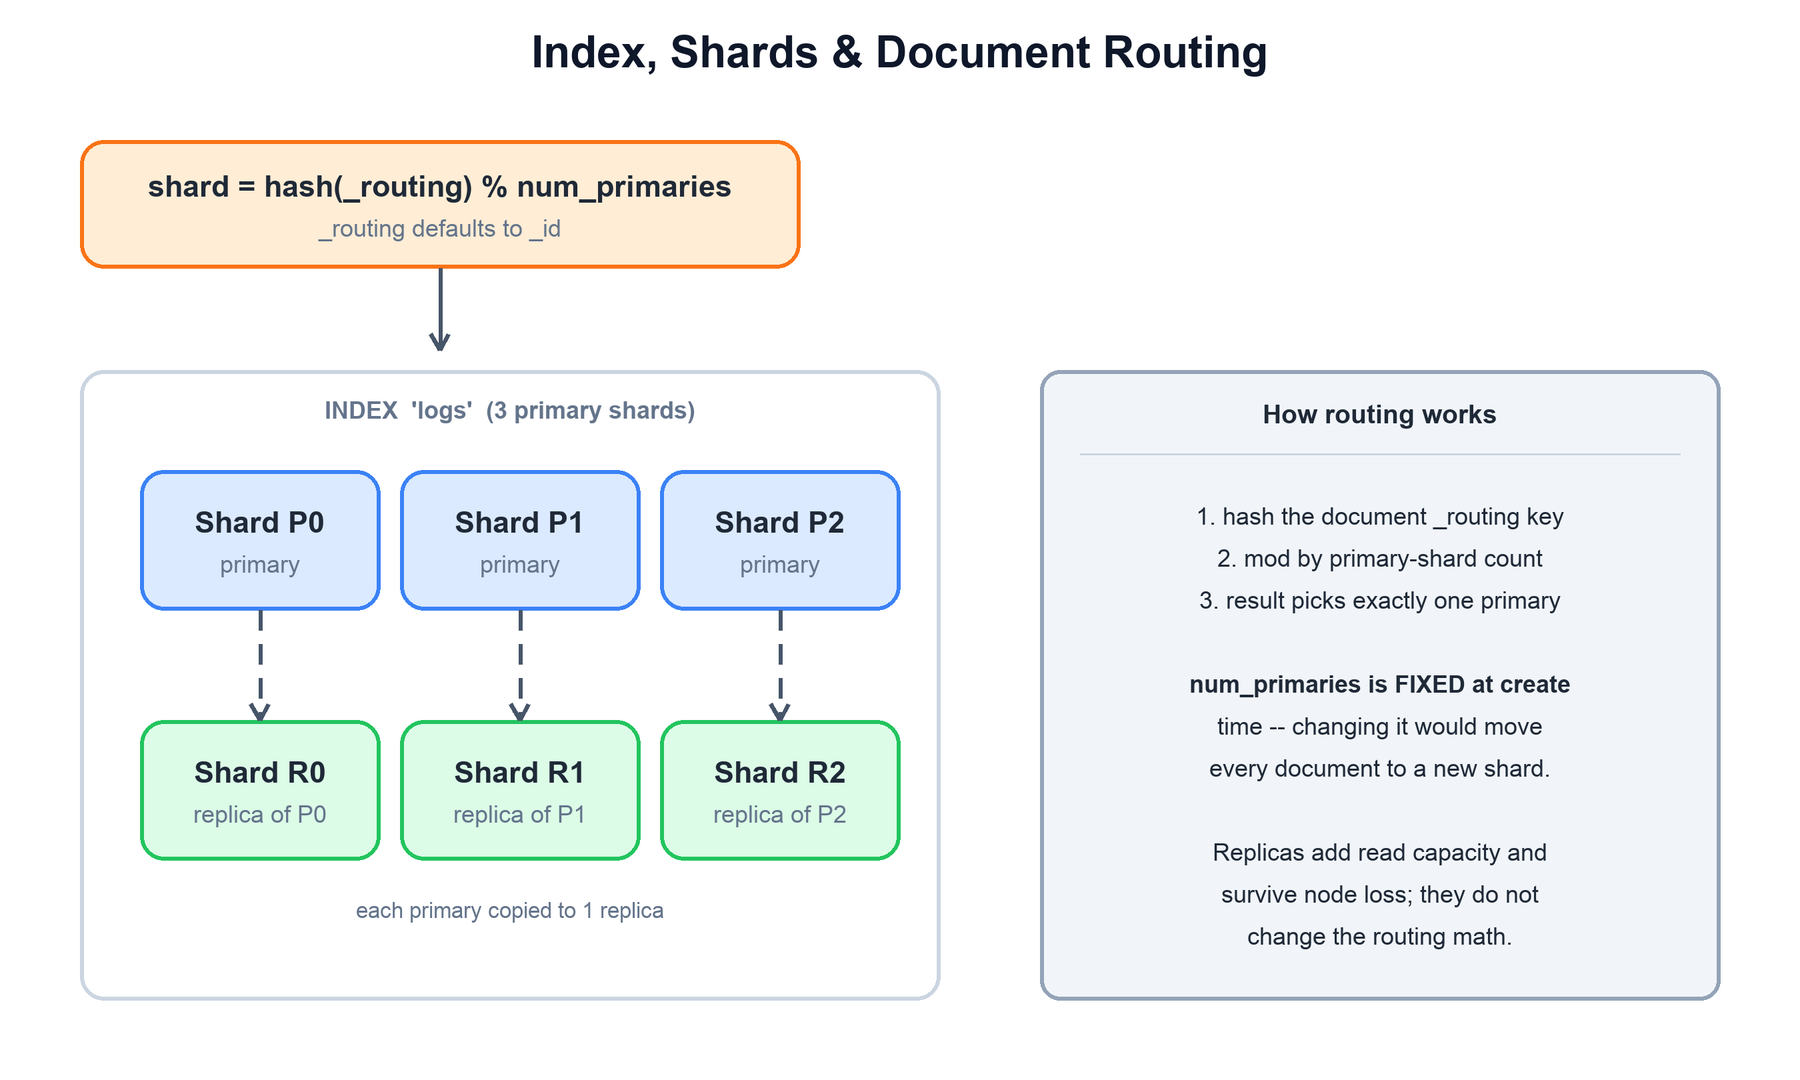
An index is a logical collection of documents (for example, all your logs). Physically, an index is split into primary shards, and each primary can have one or more replica shards. A shard is a complete, independent Lucene index. Splitting an index into shards is what lets a single index outgrow one machine and lets queries run in parallel.
An index of three primaries, each with one replica. A document's _routing key hashes to exactly one primary.
Which shard does a document go to? Elasticsearch routes it deterministically:
function route(document):
  routing = document._routing or document._id   # default routing key is the doc id
  shard   = hash(routing) % num_primary_shards  # pick exactly one primary
  return shard
Stable routing under the configured shard/routing-partition scheme narrows reads. Changing schemes and routed-partition options require supported migration semantics.
A replica maintains compatible logical shard operations/state; segment file layouts may differ under operation-based replication. Its visibility and recovery depend on checkpoints and reader refresh.
A useful mental model: primaries determine how much data you can hold and how parallel writes are; replicas determine how much you can survive losing and how parallel reads are.
4. Lucene Internals: The Inverted Index
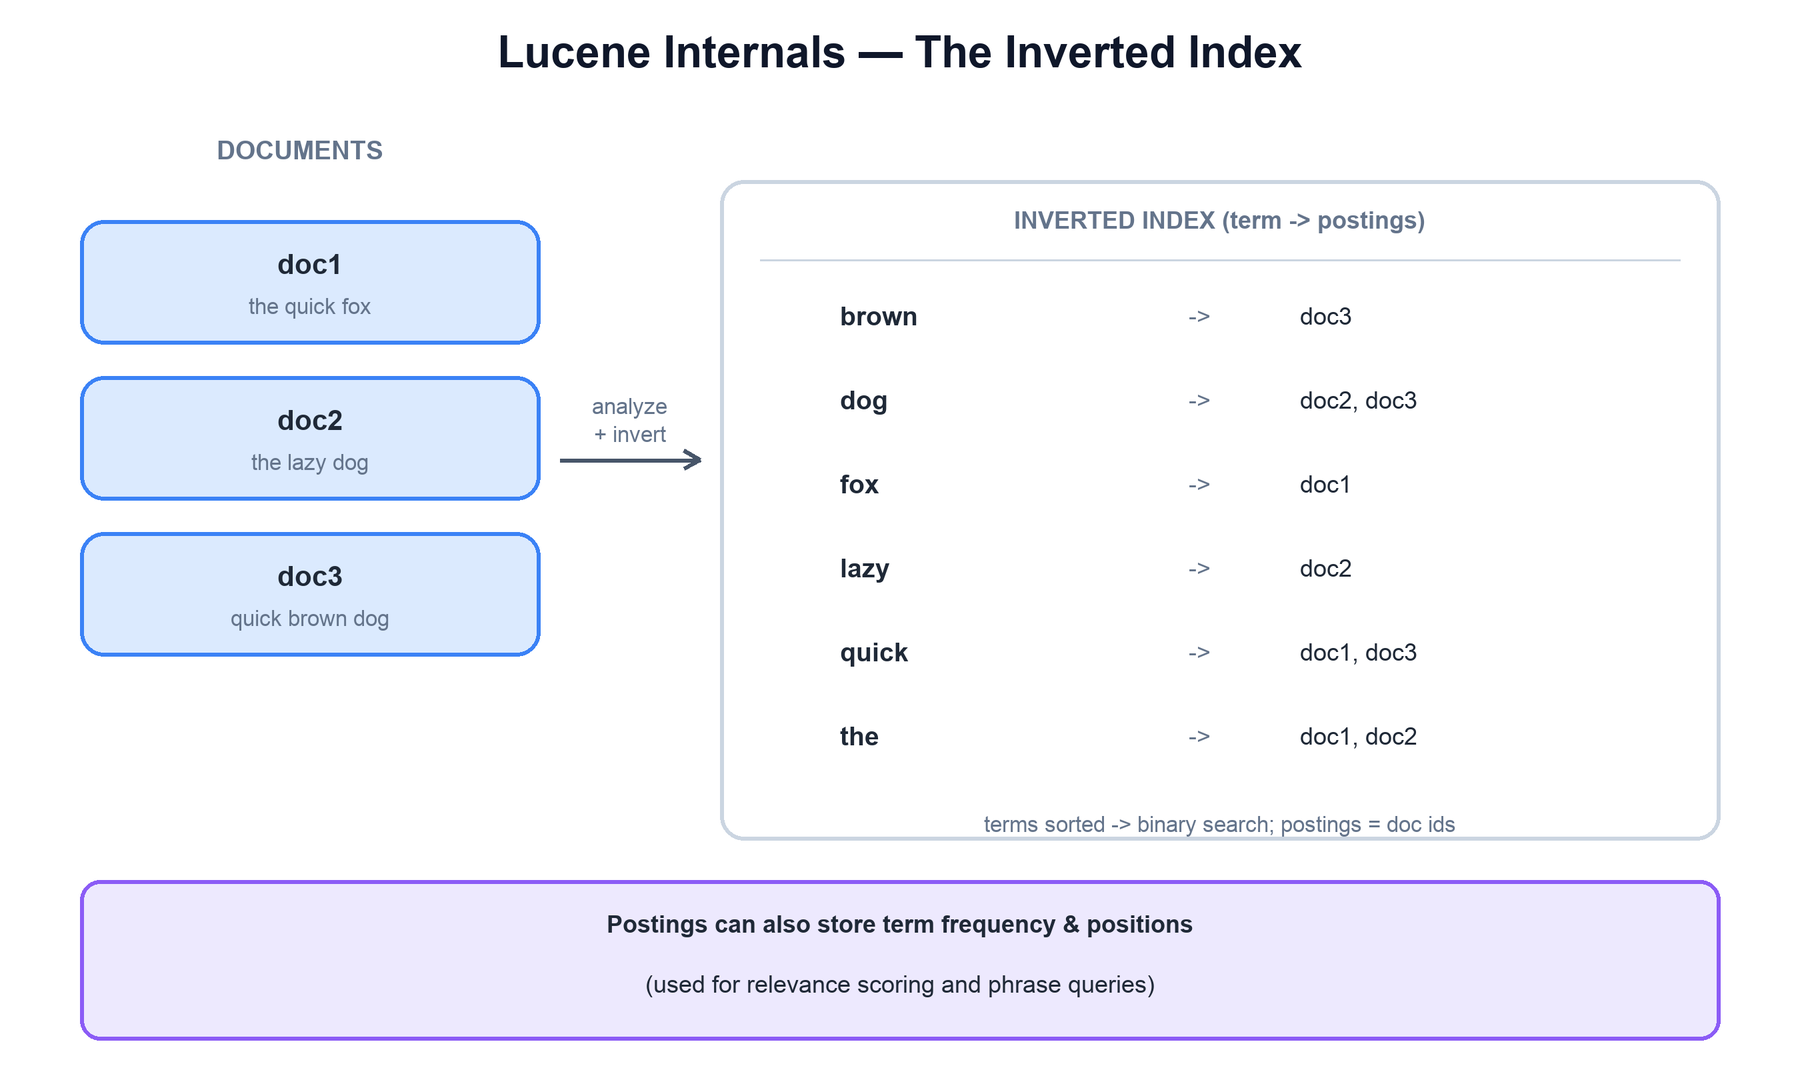
At the bottom of every shard is Lucene, and at the heart of Lucene is the inverted index. A forward index maps a document to its words; an inverted index maps each term to the list of documents that contain it (the postings list). That inversion is what makes "find every document containing fox" a single dictionary lookup instead of a scan.
Documents are analyzed into terms; the inverted index maps each term to the documents (postings) that contain it.
Lucene stores this efficiently:
Term dictionary: the sorted set of all unique terms in a field. Because it is sorted, Lucene can binary-search it and supports range and prefix queries cheaply.
Postings: for each term, the list of document ids that contain it, often with the term frequency and the positions of each occurrence. Frequencies feed relevance scoring; positions enable phrase and proximity queries.
Segments: a Lucene index is not one big file. It is a set of immutable segments, each a small, self-contained inverted index. New documents go into new segments; existing segments are never modified. Immutability is the key trick — a segment needs no locking, can be cached aggressively, and is safe to read concurrently.
Because segments are immutable, a delete cannot remove a document in place. Instead Lucene records the doc id in a per-segment deleted-documents bitset and filters it out of results. An update is just a delete plus a fresh insert. The space is reclaimed later, during merge.
5. Indexing Path
The primary validates/applies a document and records recoverable operation state under configured translog durability and replica acknowledgement. An append alone is not power-loss durability. Request versus asynchronous translog modes and in-sync replica changes affect the fault contract.
Refresh opens a new search view; an old reader does not change automatically. Flush performs a durable Lucene commit and safely advances recovery-log cleanup under engine rules; it is not a blind truncate of all concurrent operations. Merge rewrites segments and preserves readers' old file lifetimes.
Successful indexing does not universally mean immediate search visibility. GET can use a different real-time path. Use refresh=wait_for or another supported policy when search visibility after a write is required, and state the latency/load cost.
6. Near-Real-Time Search
Search readers are snapshots. New indexed state becomes searchable through the supported refresh/reopen path, while configured translog/replica durability can be established separately. An old reader can still return prior state; GET-by-ID may use a different real-time path.
refresh_interval and explicit/wait-for refresh policies trade freshness against segment/merge costs, and defaults can depend on deployment/activity/release. Do not promise exactly one second or immediate power-loss durability for every write. Asynchronous translog policies can have a loss window.
Use the actual durability, replica, search visibility, and concurrent-version conditions required by the API. Retained reader lifetimes and partial shard responses remain part of the query contract.
7. Replication Model
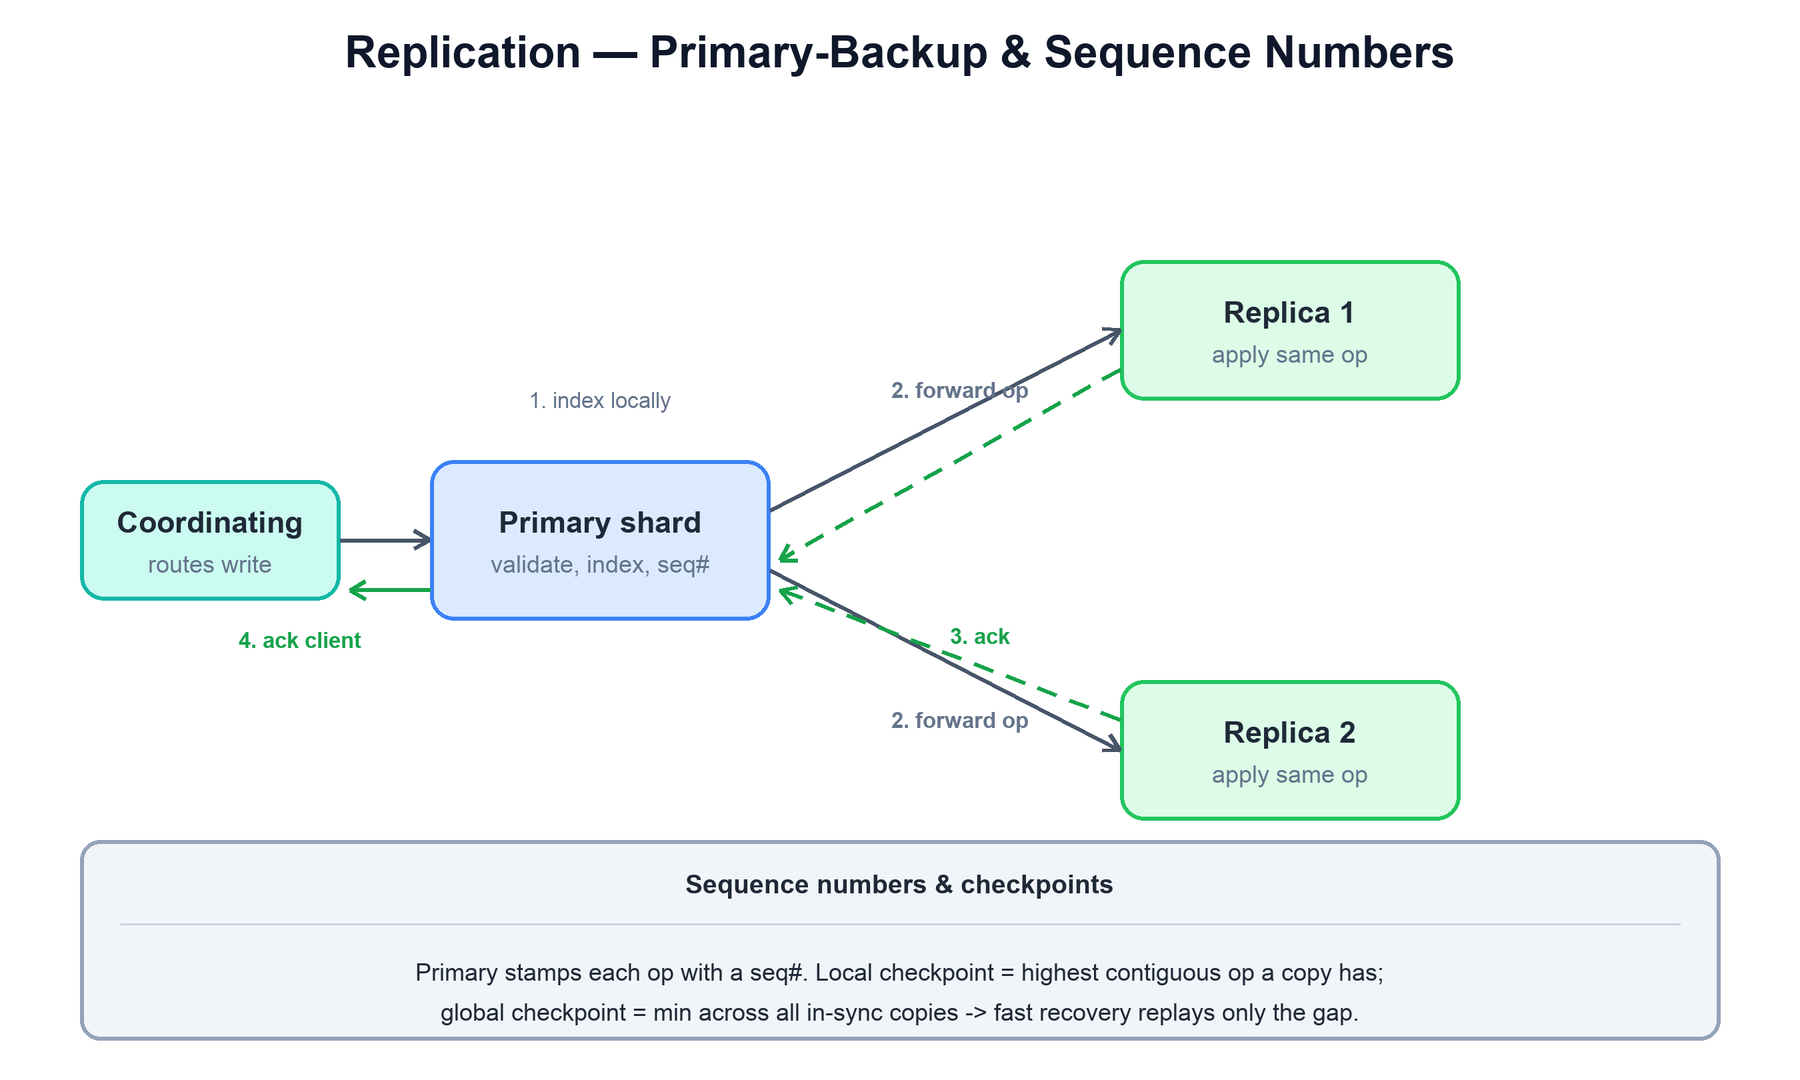
Elasticsearch replicates each shard with a primary-backup model. All writes for a shard go to its primary first; the primary then forwards them to the replicas. This is different from Cassandra's quorum model — there is a designated primary that orders the writes, which gives Elasticsearch a clear, single source of truth for each shard.
Writes go to the primary, which indexes locally and forwards the operation to each replica before acknowledging the client.
The write sequence for a single document is:
function replicate_write(doc):
  primary.validate(doc)
  primary.index(doc)                       # 1. apply locally, assign a seq#
  for replica in in_sync_replicas:
    send(replica, op = doc, seq = seq_no)   # 2. forward the same operation
  wait_for_replica_acks()                   # 3. replicas apply and ack
  return ack_to_client()                    # 4. ack once replicas confirm
Two bookkeeping concepts keep replicas in step and make recovery cheap:
Concept
What it is
Sequence number
The primary stamps every operation with a monotonically increasing seq#, so every copy can tell exactly which operations it has applied and in what order.
Per shard copy: the highest seq# below which that copy has applied every operation with no gaps.
Global checkpoint
The minimum local checkpoint across all in-sync copies. Every operation at or below it is guaranteed present on all in-sync copies.
Recovery can replay retained compatible operation history when identity/checkpoints/history retention allow it; otherwise the supported protocol may use file-based recovery. A brief outage alone does not guarantee one fixed translog-only path.
8. Query Path
A coordinator targets relevant shard copies, pruning by routing, indices, and other supported constraints. Query phase returns hit identifiers/scores; fetch phase hydrates selected hits. Distributed top-k is meaningful under compatible scoring/statistics; shard-local statistics can differ from globally scored retrieval.
Check failed/partial shard responses and timeout flags before reporting totals as exact. Aggregations have their own merge/approximation rules. Deep from/size pages create large candidate work; use supported search_after/point-in-time semantics and deterministic ordering for stable paging, with current authorization.
Query-time analyzers can intentionally differ from index-time analysis, for example synonyms, if they produce compatible matching terms. Keyword fields may have configured normalizers; 'keyword always stores verbatim' is too broad.
9. Analysis: Turning Text Into Terms
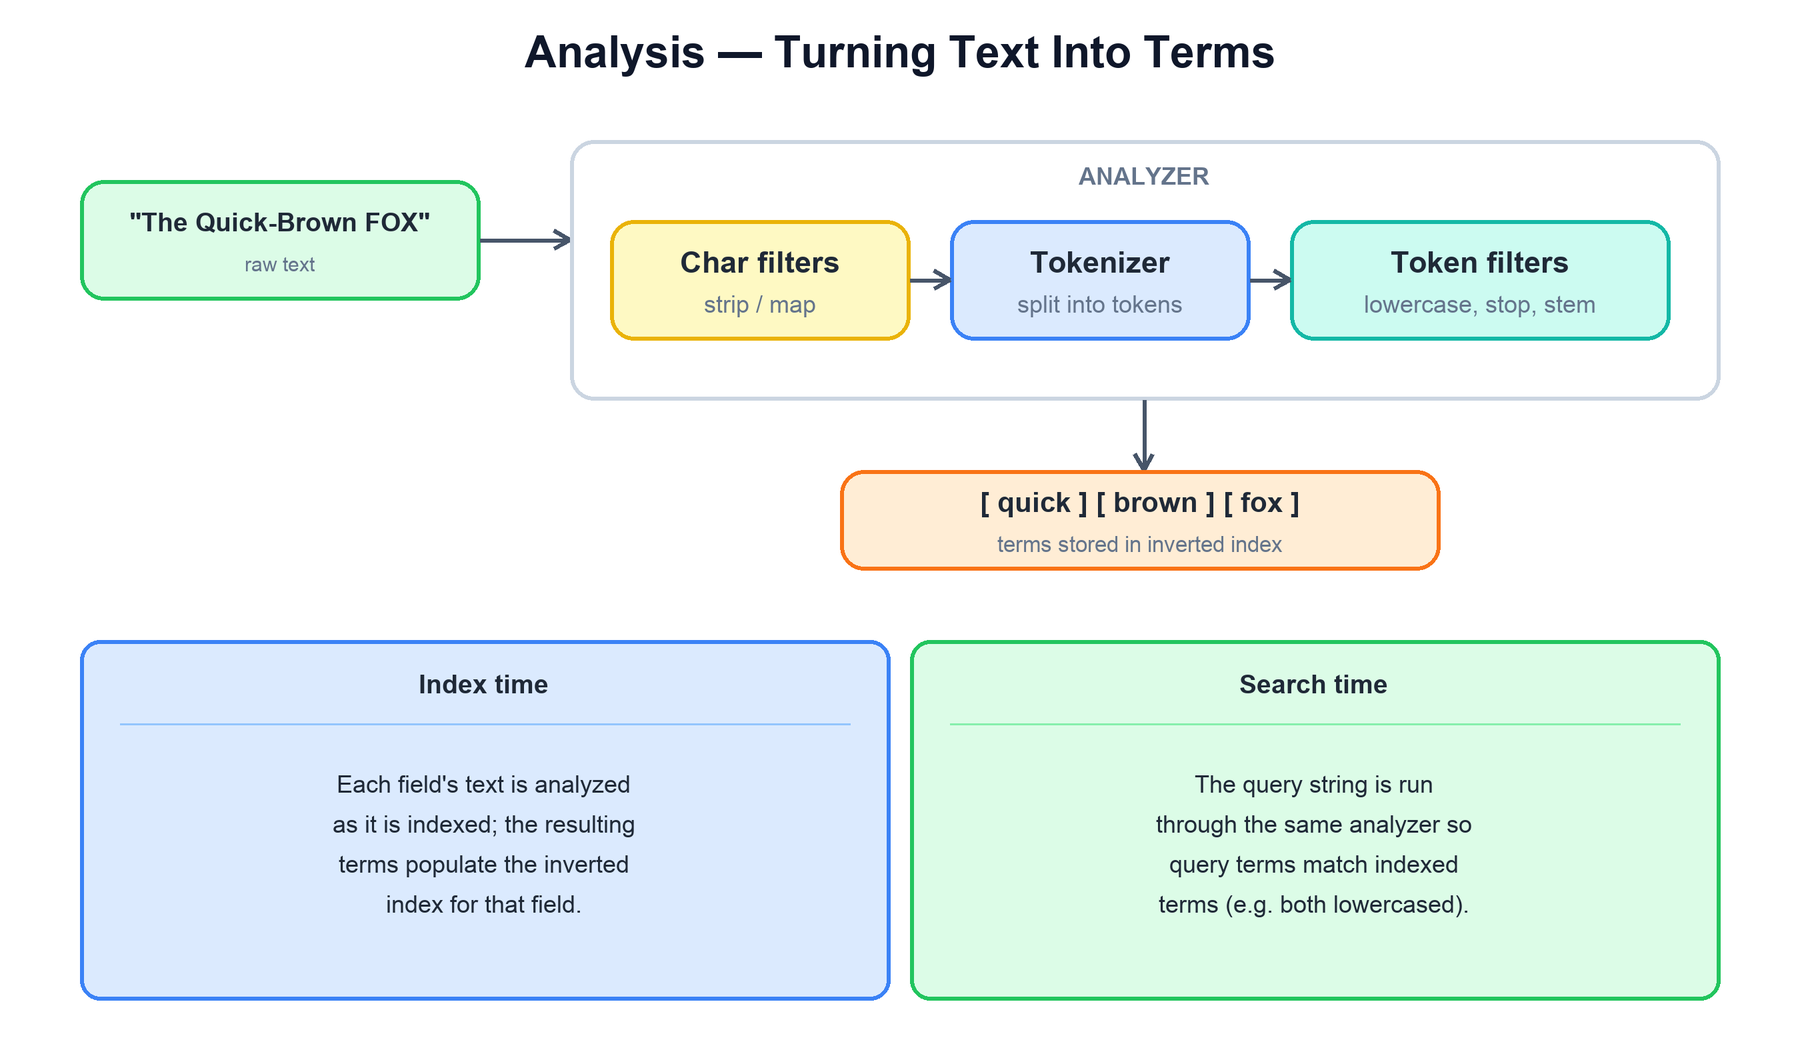
Before text can go into an inverted index, it must be broken into terms. That job belongs to an analyzer, a pipeline of three stages applied in order.
An analyzer runs character filters, then a tokenizer, then token filters, producing the terms stored in the inverted index.
Stage
What it does
Example
Character filters
Pre-process the raw string before tokenizing.
Strip HTML tags; map & to "and".
Tokenizer
Split the stream into tokens.
Standard tokenizer breaks on whitespace and punctuation: "Quick-Brown" → "Quick", "Brown".
The subtle but crucial point is that analysis happens at two times, and they must agree:
Index time: when a document is indexed, each text field is analyzed and the resulting terms populate that field's inverted index.
Index/query analysis must be compatible, not necessarily identical. Query-time synonym and other intentional transformations can use a different configured analyzer.
Index/query analysis must be compatible, not necessarily identical. Query-time synonym and other intentional transformations can use a different configured analyzer.
Worked example: an acknowledged write is not in an old search
Work through the following bounded example and its failure boundary.
Sequence for this example. The table explains the evidence and decision at each step.
Step
Evidence, decision, and expected result
Index version 2
Configured translog/replica acceptance can make the operation recoverable before search readers reopen.
Search the old reader
It can still return version 1 until refreshed. GET-by-ID and search have different visibility semantics.
Refresh or use a supported wait policy
A new reader sees the new index view; this is separate from fsync/durable commit.
Write from a stale base
Use supported sequence-number/primary-term conditions; a check then unconditional write can lose another edit.
Check your understanding: Are replicas always byte-for-byte segment copies?
Not universally. Operation-based replication may build different segment layouts while representing compatible logical operations/state.
Run and change the example
Download guide_labs.py. Python 3.10+, standard library only. In its directory, run:
python3 guide_labs.py index
python3 guide_labs.py test
The model holds separate durable and searchable snapshots, then tests conditional version updates.
The program tests its stated finite contracts. It is an educational model, not an implementation of the named production product or a proof of unmodeled distributed faults.
Analyzers (char filters → tokenizer → token filters) at both index and search time.
The recurring theme: Lucene does the searching, Elasticsearch does the distributing. Immutable segments, an append-only translog, batched refreshes, and a single ordering primary per shard are what let it be fast, durable, and near-real-time all at once.