People Management — your team is burning out from operational incidents and on-call toil while under pressure to deliver new features; how you protect the team while still meeting business goals.
Student edition · understand, apply, verify
Protect sustainable operations through workload evidence, staffing, alert quality, and recovery time.
What you should be able to do: Reduce unnecessary interruption without hiding incidents or shifting invisible work to others.
Context-dependent people-management guidance, not a universal HR/legal policy or verified autobiographical record. Work from observable behavior, explicit expectations, appropriate privacy, fair support/accommodations, and your organization's qualified process. Example outcomes are illustrative, not guaranteed.
Concepts explained in this guide
Read these definitions first, or use the linked terms as you go. The examples and limitations are local to this guide; companion pages are optional.
Toil, incident response, and error budgets
Toil is repetitive operational work that scales without lasting improvement. Incident response restores safe service first; an error budget relates risk to a user-defined SLO.
Example. Automate a repeatedly safe recovery after checking failure cases, and measure reduced effort/errors with an operator escape path.
Boundary. Not all recurring work is waste. Automation can amplify errors; preserve necessary safety controls. Budgets are policy, not universal mandates.
SLIs, SLOs, and error budgets
An SLI measures a user-relevant outcome; an SLO sets its target over a window. For a success-ratio SLO, the allowed bad fraction is 1−SLO. An SLA is a contractual commitment that may use different definitions.
Example. 99.9% successful requests over 1 billion requests allows 1 million bad requests. A time-based 30-day availability target instead allows 43.2 unavailable minutes.
Boundary. Request and time budgets are not interchangeable under variable traffic or partial failure. SLOs are not universally stricter than SLAs; choose both from their definitions and user needs.
Outputs, outcomes, and measurement
Outputs are produced things; outcomes are changes for users/business/team. Useful metrics state definition, denominator, population, period, and attribution limits.
Example. 'Shipped a tool' is output. 'Median onboarding fell ten to six days in this cohort' is an outcome with sample/context caveats.
Boundary. Before/after does not prove sole causation. Avoid gaming, selection bias, hidden costs, and unlike-team comparisons.
Ownership, accountability, and decision rights
Ownership names who drives follow-through; accountability names who answers for outcomes. Decision rights specify who chooses/approves and who is consulted.
Example. A migration has a coordinating owner, service owners, and named release authority.
Boundary. DRI/RACI/DACI are local conventions, not guarantees. Role labels do not replace authority, capacity, and follow-through.
Coaching, delegation, and expectations
Coaching develops reasoning through questions, practice, and feedback. Delegation transfers defined work/decision responsibility with support. Expectations make outcomes and behaviors explicit.
Example. Delegate a design decision with authority, constraints, check-in, and escalation trigger—not hidden standards.
Boundary. Match support to experience/risk. Performance policies and legal requirements vary; no universal PIP timeline or personality label is a fair diagnosis.
This question tests whether you can balance the health of your people against the demands of the business without pretending the two aren’t in tension. A weak answer either sacrifices the team (“we pushed through and delivered”) or ignores the business (“I told my skip we’d stop feature work”). A strong answer shows that you measure the toil, protect the team in the short term, renegotiate scope by making the cost of the toil visible upstream, and then fix the root causes so the burnout doesn’t return — treating reliability as a deliverable, not a distraction. Answer in CARL shape (Context, Actions, Results, Learnings), with most of your words on the actions.
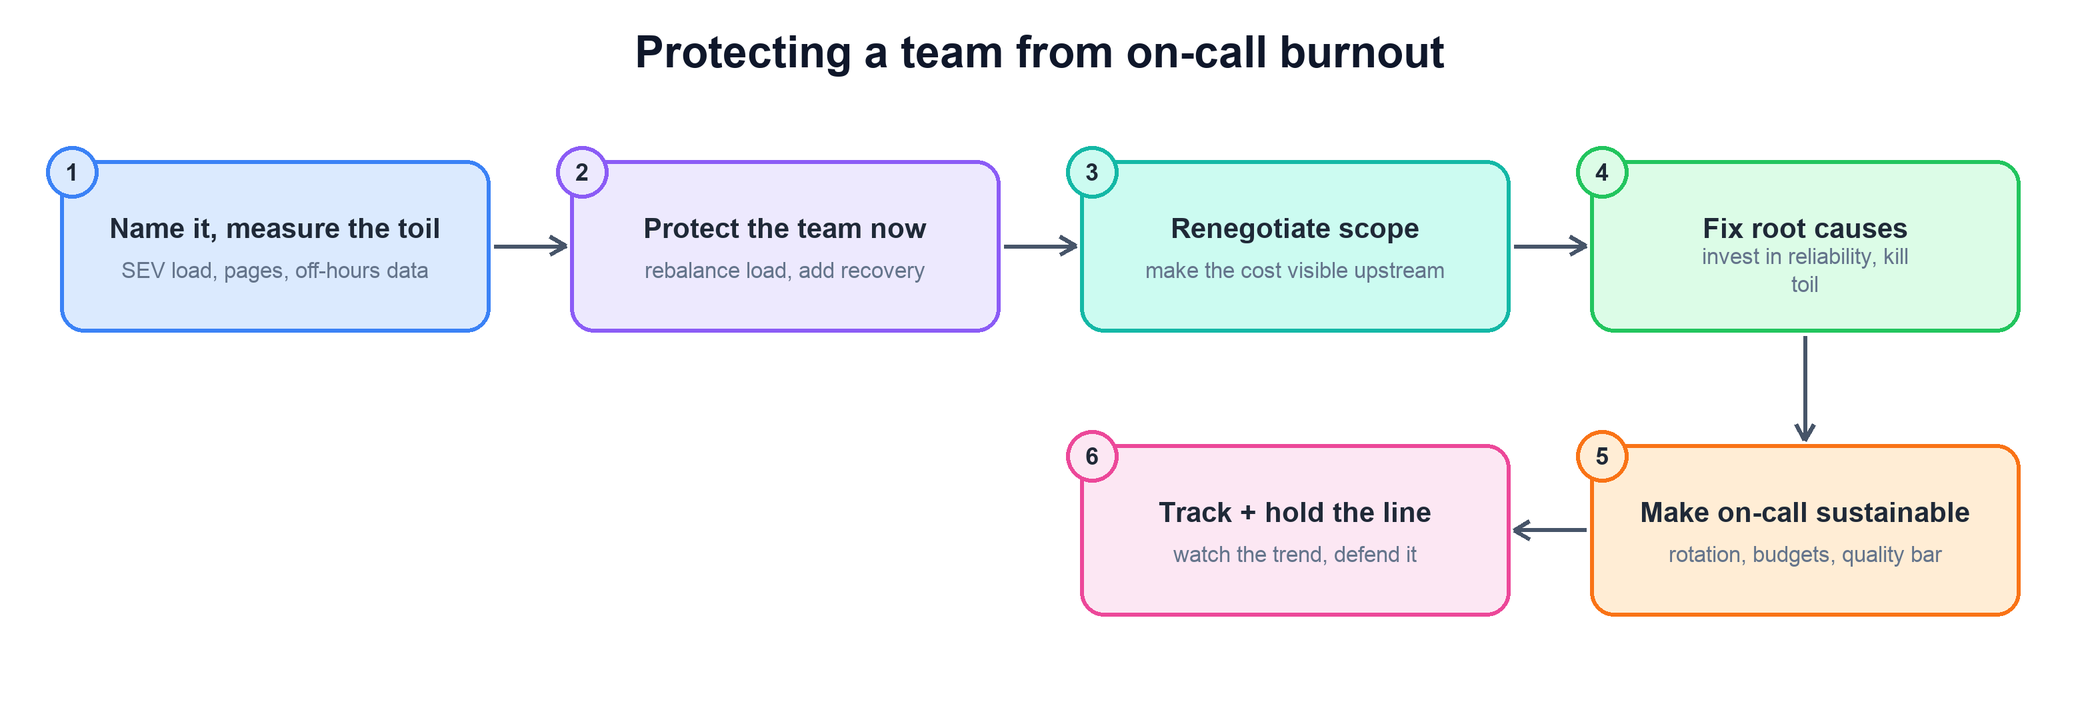
The spine: name it and measure the toil → protect the team now → renegotiate scope → fix root causes → make on-call sustainable → track and hold the line.
What this question is really testing
Two things. First, whether you treat burnout as a systems problem you can measure and fix, not a resilience problem for individuals to tough out. Second, whether you have the backbone to renegotiate with the business using data, rather than silently absorbing an impossible load and burning your best people until they leave — which is the most expensive possible outcome. The subtle trap is the manager who is “protective” by shielding the team from the pressure while quietly working themselves and the team to exhaustion; real protection means changing the equation, not just the messaging.
How to answer
Name it and measure the toil. Quantify the load — page volume, off-hours interrupts, SEV frequency, time lost to operational work versus project work. You can’t protect the team or renegotiate scope on a feeling; you need the number.
Protect the team in the short term. Rebalance the on-call load immediately, give people who took the worst rotations real recovery time, and pull the most-drained person off the fire line before you fix anything structural.
Renegotiate scope by making the cost visible. Take the toil data to your skip and stakeholders and be explicit: this much capacity is going to keeping the lights on, so the feature roadmap has to flex or reliability investment has to be funded. Force an honest tradeoff instead of pretending both are free.
Fix the root causes. Invest in the reliability work that removes the toil — the top incident sources, the missing automation, the fragile systems — so the load structurally drops rather than getting redistributed.
Make on-call sustainable and hold the line. Set an on-call quality bar (rotation size, an interrupt budget, runbook coverage), track the trend, and defend the reliability budget when the next feature crunch tries to eat it.
What the interviewer is looking for
Measuring toil as a system, not diagnosing individual weakness.
Immediate protection of the team paired with a structural fix.
Backbone to renegotiate scope with data, not silent absorption.
Treating reliability investment as a funded deliverable.
Holding the sustainable state against the next crunch.
A worked example (CARL)
Practice draft: first-person narratives below are not independently verified autobiographical evidence. Use their structure, not their claimed results; replace with your genuine safe-to-share experience.
Context. On the Ads Events storage team we hit a stretch where on-call had become genuinely unhealthy. We were carrying a heavy incident load from a storage-throttling class of issues that pushed people into repeated off-hours pages, and at the same time we had a committed feature roadmap that assumed everyone was fully available for project work. Two of my strongest engineers were visibly fraying — one told me directly in a 1:1 that they were thinking about switching teams — and the on-call handoffs had started dropping context because people were too fried to write them up properly. This was the point where “push through” would have cost me the people I could least afford to lose.
Actions. I started by measuring instead of reassuring. I pulled the actual numbers — page volume by week, how many were off-hours, what fraction of the team’s capacity was going to operational work versus the roadmap, and which incident classes drove the load — and it turned out a large majority of the pages traced back to a small handful of root causes. With that in hand I did two things in parallel. Short term, I protected the team: I expanded the on-call rotation so no one was carrying it back-to-back, I explicitly gave the most-drained engineer a two-week break from on-call and from stretch project commitments to recover, and I made writing proper handoffs a lighter, templated task so the tired person wasn’t also fighting a blank page. Then I took the toil data to my skip and the stakeholders and made the tradeoff undeniable: I showed that a large chunk of the team’s capacity was being spent keeping the lights on, and I said plainly that we could not hit the full feature roadmap and fix reliability at once — so either the roadmap flexed or we funded a reliability push. I came with a specific proposal rather than a complaint: fund a scoped reliability sprint to kill the top incident sources, and I’ll protect the highest-priority feature but push the rest by a few weeks. They agreed, because the data made the cost of not agreeing obvious. During the reliability push I had the team automate the worst manual remediation, fix the throttling root causes, and raise the alerting quality so we stopped paging on noise. Finally I set a sustainable bar — a minimum rotation size, an explicit off-hours interrupt budget we’d treat as a SEV-worthy signal if breached, and runbook coverage for the top scenarios — and I put the on-call trend on our weekly review so it stayed visible.
Results. Off-hours pages dropped sharply once the top root causes were fixed, and the operational share of the team’s capacity came back down to a level where project work was sane again. The engineer who’d been thinking of leaving stayed and later told me the thing that mattered wasn’t the break itself, it was seeing me actually change the load instead of just sympathizing. We shipped the highest-priority feature on time and the deferred items landed a few weeks later without drama.
Learnings. The load was a systems problem, and treating it as one — measure, protect, renegotiate, fix — worked far better than asking people to be more resilient. The lesson I carry: protecting a team is not shielding them from the pressure while the toil continues, it’s changing the equation, which almost always means having the honest scope conversation with the business backed by data. And an interrupt budget you actually defend is what keeps the burnout from quietly creeping back the next quarter.
Common follow-ups
What if the business says the feature roadmap can’t move?
How to answer
Make the tradeoff explicit, not emotional. Show the capacity math: if toil stays and the roadmap stays, the gap is real and something breaks — name what.
Offer options, not an ultimatum. Flex scope, fund reliability, or add capacity — put the decision and its cost in the stakeholder’s hands.
Protect the top priority. Commit to the single most important deliverable so they see you’re optimizing, not resisting.
Escalate with data if needed. If the answer is truly “do it all,” that’s a leadership decision to surface up, with the attrition risk named.
How do you tell real burnout from normal crunch?
How to answer
Look at duration and recovery. A hard sprint with a clear end is crunch; sustained load with no recovery window is burnout.
Watch the leading signals. Dropped handoffs, cynicism, withdrawal, and quiet flight risk in 1:1s precede the visible collapse.
Check the toil trend. Rising off-hours pages over weeks is a system in the red, not a one-off bad week.
Ask directly. A candid 1:1 question — “how sustainable does this feel” — surfaces it earlier than any dashboard.
How do you invest in reliability without stopping all feature work?
How to answer
Target the vital few. Fixing the top handful of incident sources removes most of the toil for a fraction of the effort.
Fund it as a budget. Reserve a standing fraction of capacity for reliability so it competes with features on equal footing.
Bank the reclaimed time. Reinvest the capacity freed by killing toil, so the fix compounds instead of getting absorbed.
Make it a deliverable. Scope reliability work with DRIs and outcomes, not as vague “tech debt” that never lands.
How do you keep the burnout from coming back?
How to answer
Set a defended interrupt budget. Treat breaching the off-hours page threshold as a signal worth acting on, not a fact of life.
Keep the trend visible. Put on-call load on the weekly review so drift is caught early, not after someone quits.
Hold the line in the next crunch. Protect the reliability budget when the following roadmap tries to eat it — that’s the real test.
Rotate and share the load. Spread on-call and toil knowledge so it never concentrates on one or two people again.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
Worked example: one rotation carries recurring overnight pages
An illustrative situation to practice reasoning, communication, and fair evidence gathering.
Sequence for this example. The table explains the evidence and decision at each step.
Step
Evidence, decision, and expected result
Measure actual workload
Count actionable pages, duration, overnight disruption, toil, and unequal distribution over comparable shifts.
Rebalance staffing/escalation, protect rest/recovery, and involve qualified support for voluntary health concerns.
Check sustained effects
Track SLO/detection coverage and workload, not just page count. Escalate an unfunded operational burden rather than normalize heroics.
Check your understanding: Does automating a runbook always reduce risk?
No. Automation can amplify errors; validate safety, bounds, abort/rollback, and operator recovery.
Practice with your own situation
Write the expected outcome/behavior, observed evidence, context and alternative explanations, your agreed support/action, decision owner, review date, and evidence that would change the plan. Keep confidential personnel material out of public examples.
Use genuine, safe-to-share evidence. Example numbers here illustrate reasoning; they are not claims about your work or a guaranteed outcome.