How to answer the reliability and SRE-partnership questions in a senior engineering-leadership loop: the framework to structure each answer, what the interviewer is really listening for, and where inside Meta to pull the evidence that backs your story.
Student edition · understand, apply, verify
Explain SRE partnership using defined user outcomes, error budgets, safe response, and operational load.
What you should be able to do: Keep request/time budgets, actual coverage, mitigation safety, and responsibility boundaries distinct.
Practice guidance for your own truthful, authorized experience. Frameworks help organize decisions/evidence; they do not guarantee results or verify personal claims. Technical risk, privacy, fair personnel processes, and decision rights remain explicit.
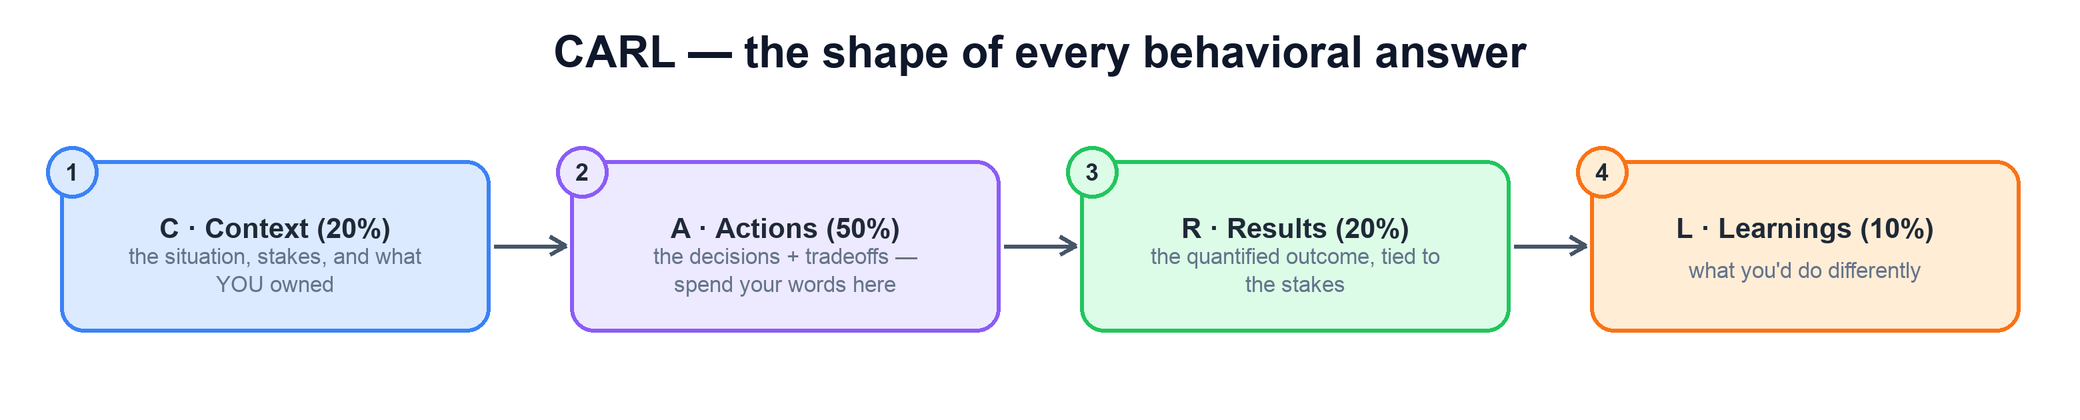
This area tests one thing: can you treat reliability as a feature you budget for, lead calmly through an outage, and make the durable fix instead of the band-aid. Interviewers are not grading whether your systems have ever broken — they assume they have. They are grading judgment: did you set explicit SLOs, spend the error budget on purpose, mitigate before you debugged, run a blameless postmortem, and drive the systemic fix that stopped the page from coming back. Every answer below is built on the CARL shape — Context, Actions, Results, Learnings — with most of your words spent on the decisions and tradeoffs.
CARL is the shape of every behavioral answer. Spend ~50% of your words on Actions — the decisions only you could have made — and never drop Results or Learnings.
Read these definitions first, or use the linked terms as you go. The examples and limitations are local to this guide; companion pages are optional.
SLIs, SLOs, and error budgets
An SLI measures a user-relevant outcome; an SLO sets its target over a window. For a success-ratio SLO, the allowed bad fraction is 1−SLO. An SLA is a contractual commitment that may use different definitions.
Example. 99.9% successful requests over 1 billion requests allows 1 million bad requests. A time-based 30-day availability target instead allows 43.2 unavailable minutes.
Boundary. Request and time budgets are not interchangeable under variable traffic or partial failure. SLOs are not universally stricter than SLAs; choose both from their definitions and user needs.
Burn-rate alerting
Burn rate is the observed bad-event fraction divided by the allowed bad fraction. Multi-window alerts require sustained long-window burn and a confirming short window so old incidents can clear.
Example. For a 99.9% SLO, 2% errors is 20× burn. In a 30-day window, 14.4× time-normalized burn for one hour consumes 14.4/720=2% of budget.
Boundary. That conversion assumes time-based measurement or roughly representative request volume. Low traffic, missing telemetry, and denominator-zero need policy; an alert alone does not guarantee response.
Toil, incident response, and error budgets
Toil is repetitive operational work that scales without lasting improvement. Incident response restores safe service first; an error budget relates risk to a user-defined SLO.
Example. Automate a repeatedly safe recovery after checking failure cases, and measure reduced effort/errors with an operator escape path.
Boundary. Not all recurring work is waste. Automation can amplify errors; preserve necessary safety controls. Budgets are policy, not universal mandates.
Ownership, accountability, and decision rights
Ownership names who drives follow-through; accountability names who answers for outcomes. Decision rights specify who chooses/approves and who is consulted.
Example. A migration has a coordinating owner, service owners, and named release authority.
Boundary. DRI/RACI/DACI are local conventions, not guarantees. Role labels do not replace authority, capacity, and follow-through.
Outputs, outcomes, and measurement
Outputs are produced things; outcomes are changes for users/business/team. Useful metrics state definition, denominator, population, period, and attribution limits.
Example. 'Shipped a tool' is output. 'Median onboarding fell ten to six days in this cohort' is an outcome with sample/context caveats.
Boundary. Before/after does not prove sole causation. Avoid gaming, selection bias, hidden costs, and unlike-team comparisons.
How to use this page. For each question: read the flow diagram to fix the shape of the answer in your head, scan the How to answer bullets, check what the interviewer is listening for, then pull one hard number from the Meta sources listed before the loop. The pages are intentionally generic — bring your own story to each flow.
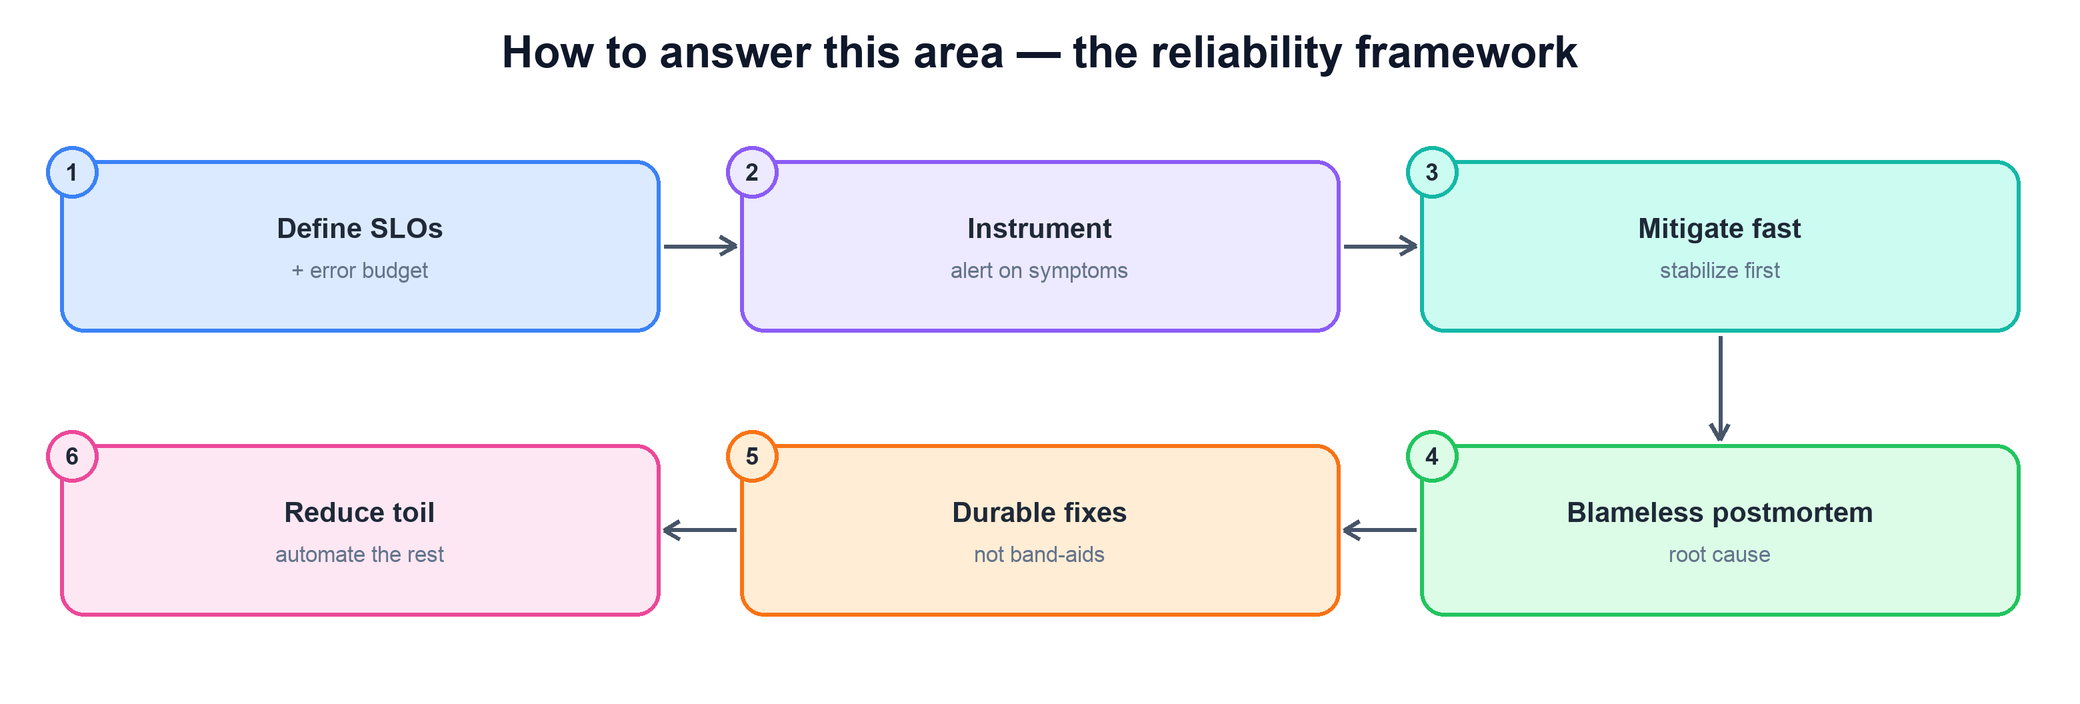
How to answer this area — the reliability framework
Use the framework where relevant, but tailor the evidence/role to the question. Reliability targets, response policies, and ownership differ by system.
The reliability spine: define SLOs and an error budget, instrument and alert on symptoms, mitigate before you debug, run a blameless postmortem, ship durable fixes, and pay down the toil that remains.How to answer
Practical availability SLOs usually allow an error budget; an absolute safety aspiration is a different property. Do not confuse the two or prescribe one target universally.
Instrument — alert on symptoms. Page on what the user feels (latency, errors, availability), not on every internal cause. Noisy cause-based alerts are how on-call burns out.
Mitigate fast — stabilize before you debug. The first job in an incident is to stop the bleeding — roll back, fail over, shed load — then find the root cause.
Blameless postmortem — find the systemic cause. Separate the human from the system. The question is what let the failure happen and what made it hard to detect.
Durable fixes, then reduce toil. Prefer the fix that prevents recurrence over the band-aid, and automate or delete the repetitive operational work that remains.
What the interviewer is looking for
Reliability framed as a budgeted tradeoff, not an absolute.
Mitigate-first instinct — calm under an active outage.
Blameless culture: systems thinking, not finger-pointing.
A bias toward durable fixes and automation over heroics.
"I" for the calls you made, "we" for how the team responded.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
How do you think about reliability for your systems, and how do you partner with SRE?
The opening philosophy question for this area. They want to hear that you own reliability as a first-class product concern and treat SRE as a shared-ownership partner, not a pager you hand off to.
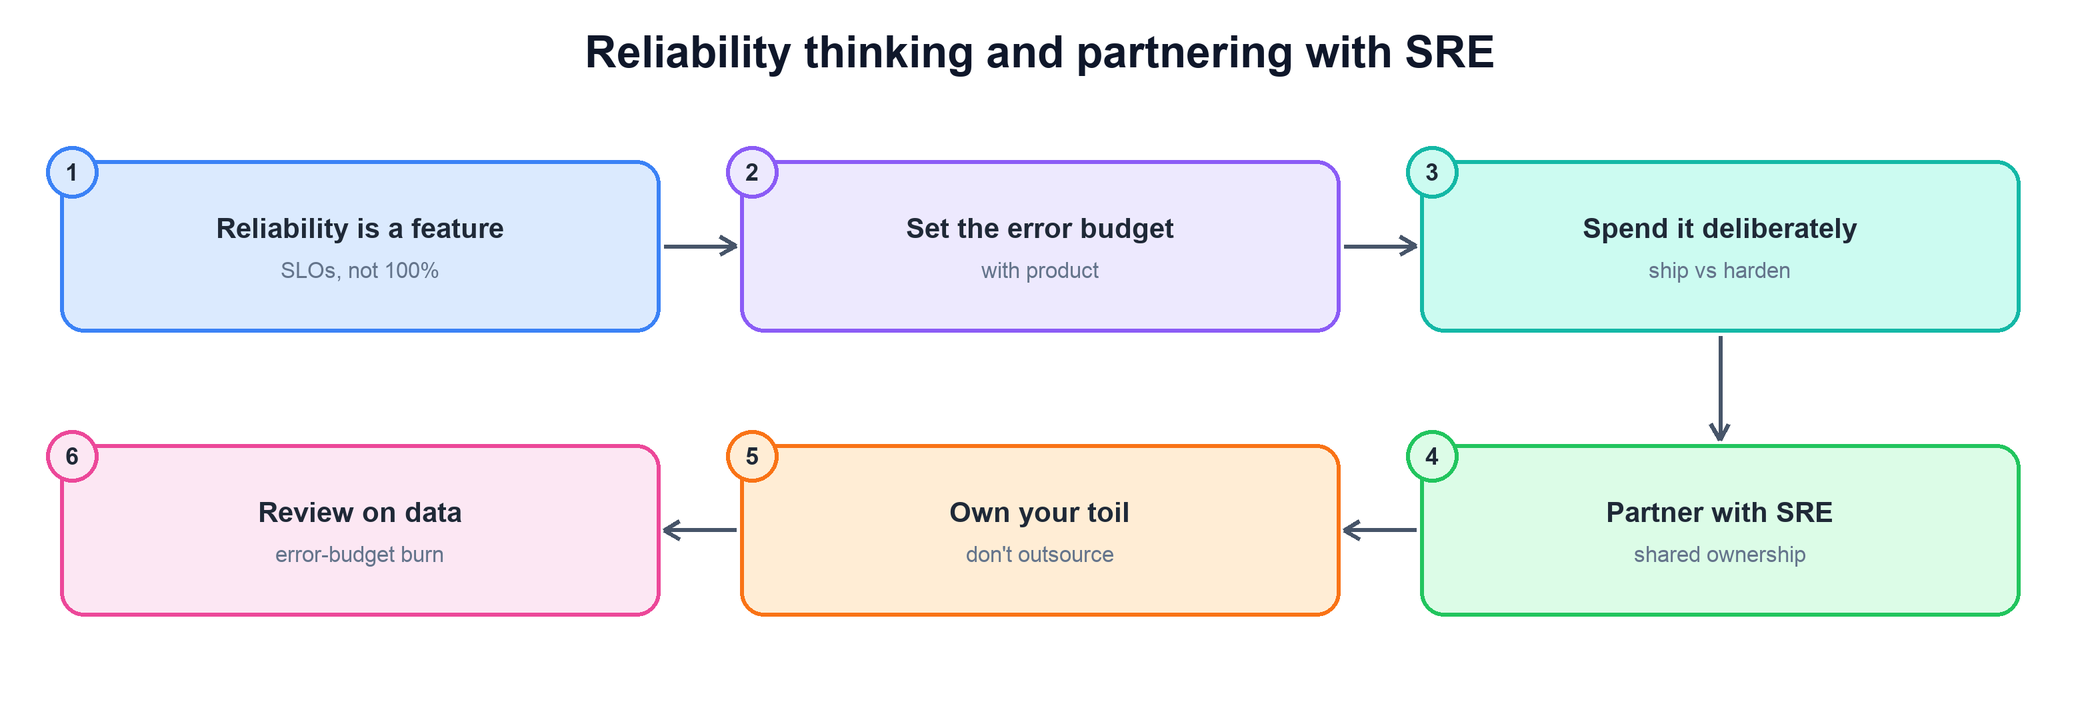
Reliability is a feature → set the error budget with product → spend it deliberately → partner with SRE on shared ownership → own your toil → review on error-budget burn.How to answer
Open by framing reliability as a feature with a cost, not a goal of 100% — the target is the SLO you can defend.
Describe how you set the error budget with product, so the business owns the reliability target alongside engineering.
Explain that you spend the budget deliberately: when it is healthy you ship; when it is burning you harden.
Position SRE as a shared-ownership partner — you don't outsource the pain; the dev team owns its own toil and pages.
Close on the operating cadence: you review on data — error-budget burn and page load — not on vibes.
What the interviewer is looking for
Reliability owned as a product concern, not delegated away.
Error budgets used to make real ship-vs-harden decisions.
A true partnership model with SRE, not a thrown-over-the-wall pager.
The dev team owning its own toil and on-call load.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
Tell me about a major incident or outage you led through. What did you do and what changed after?
The flagship question for this area. They want a real outage you led — clear roles, mitigate-first, a blameless root cause, and a durable fix that measurably changed the system after.
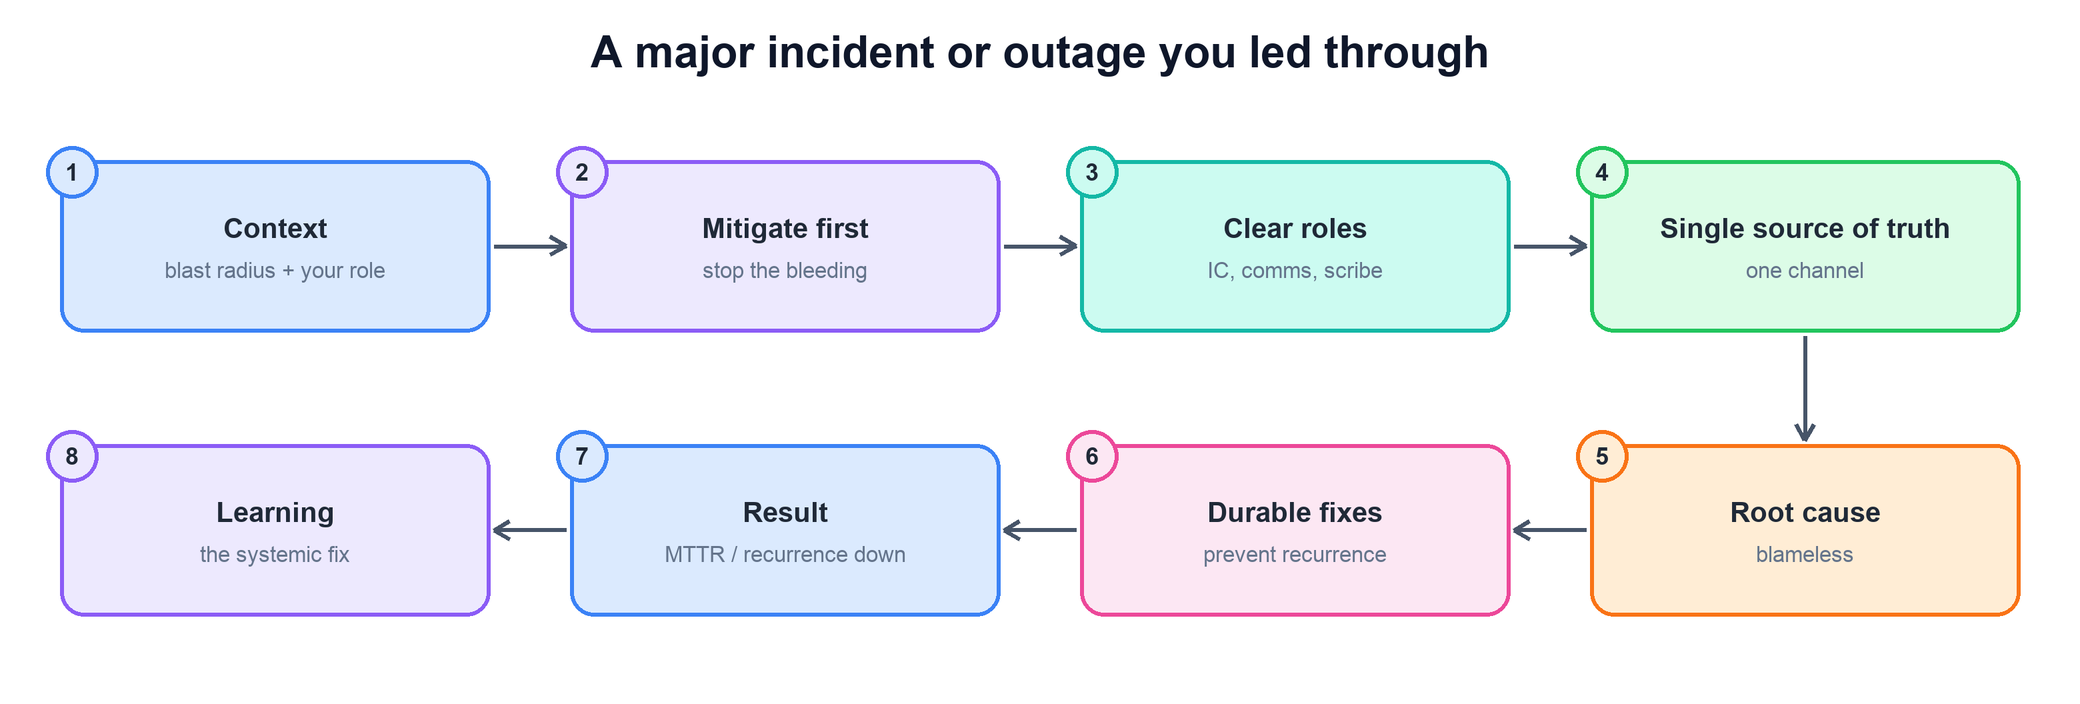
Context → mitigate first → set clear roles → one source of truth → blameless root cause → durable fixes → result → learning.How to answer
Open with the context and blast radius in two sentences: what broke, who it hit, and your role in the response.
Say you mitigated first — rolled back, failed over, or shed load to stop the bleeding before chasing the cause.
Describe how you set clear roles (incident commander, comms, scribe) and a single source of truth so the response didn't fragment.
Walk the blameless root cause and the durable fixes — the change that prevents recurrence, not the patch that hides it.
Land a quantified result (MTTR down, recurrence gone) and close with the systemic learning you carried forward.
What the interviewer is looking for
Calm command under pressure — a mitigate-first instinct.
Clear incident structure: roles, comms, one channel of truth.
A blameless, systems-level root cause — no scapegoats.
Durable fixes that measurably changed reliability afterward.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
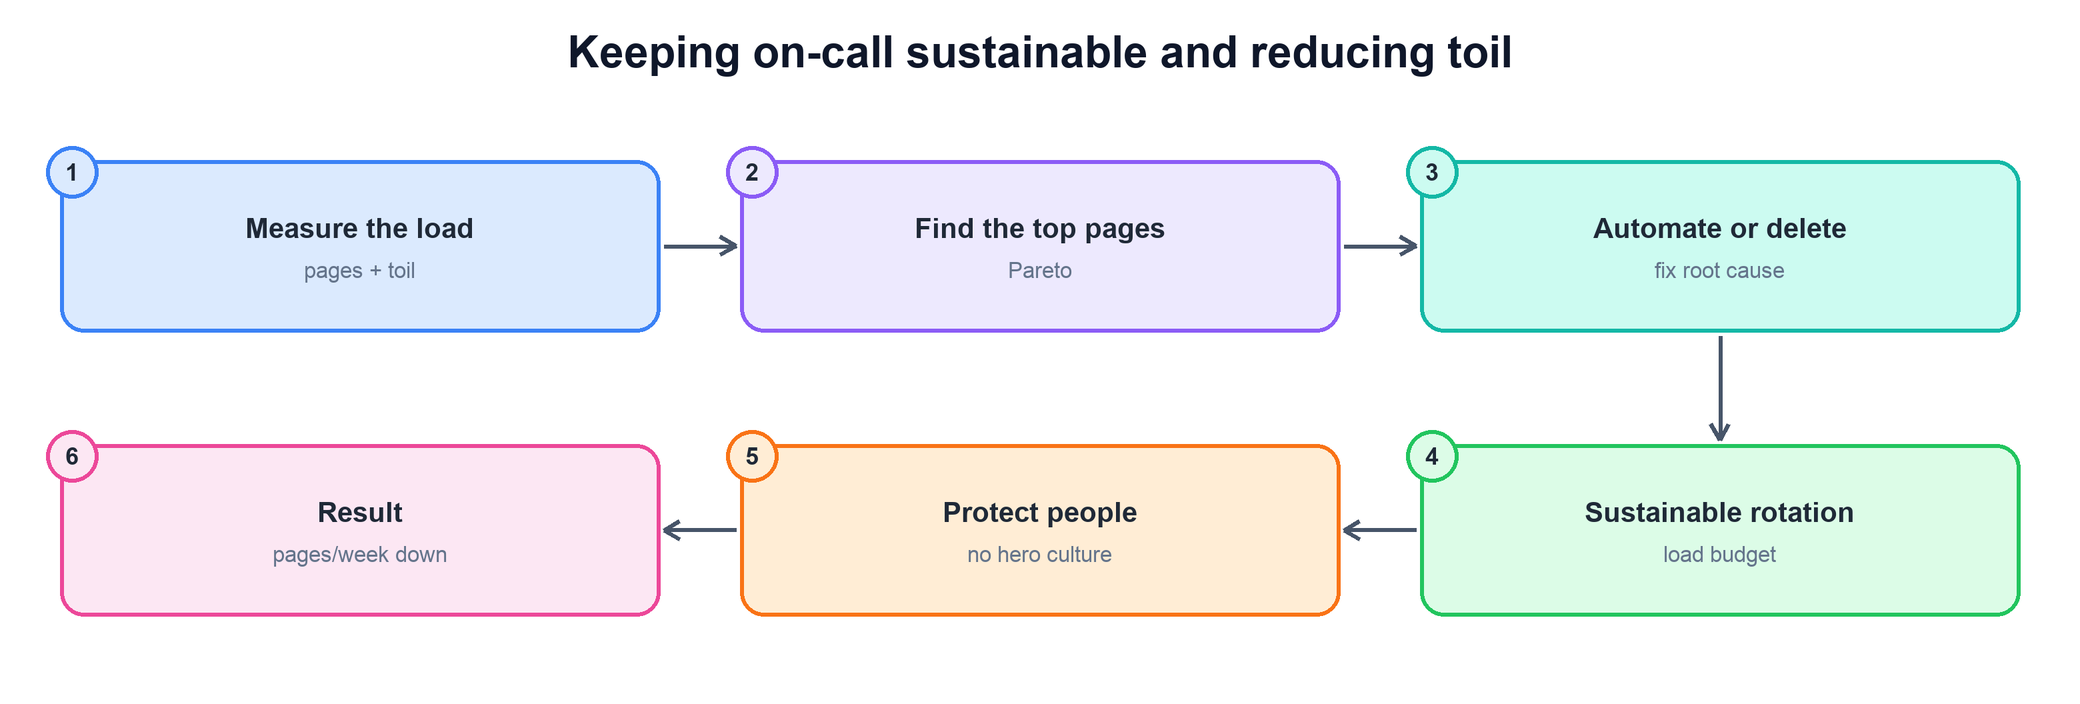
How do you keep on-call sustainable and reduce operational toil for your team?
This question tests whether you protect your people from burnout — measuring the operational load, attacking the worst of it at the root, and keeping the rotation humane.
Measure the load, find the top pages by Pareto, automate or delete them at the root, set a sustainable rotation with a load budget, protect people from hero culture, and prove pages-per-week dropped.How to answer
Start by measuring the load — pages per shift and hours of toil — so the problem is a number, not a feeling.
Use Pareto to find the top few pages driving most of the pain, and attack those first.
Automate or delete the repetitive work by fixing the root cause — auto-remediation, better defaults, or removing the alert entirely.
Set a sustainable rotation with a load budget; if a rotation blows the budget, that is a signal to invest, not to push harder.
Protect people from hero culture — reward the durable fix, not the all-nighter — and close with the drop in pages per week.
What the interviewer is looking for
Toil treated as a measurable, fixable engineering problem.
Root-cause attacks on the noisiest pages, not just triage.
A humane rotation with an explicit load budget.
Genuine care for the team — no glorifying of heroics.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
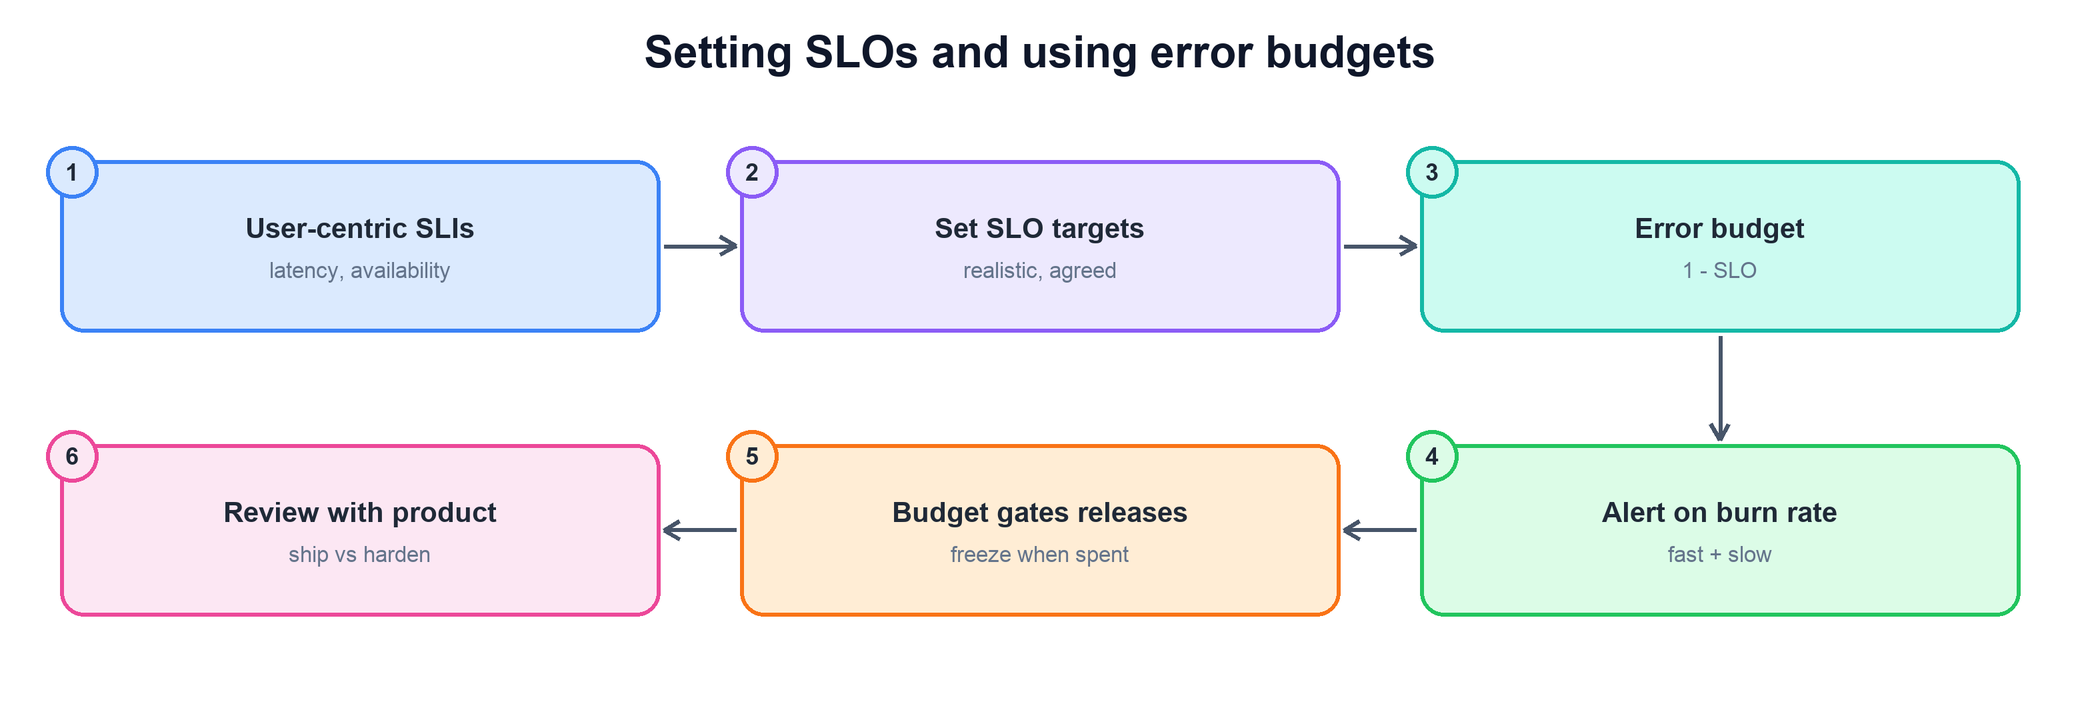
How do you set SLOs and use error budgets to make decisions?
A focused mechanics question. They want to see that you can define meaningful SLIs, set defensible targets, and actually use the error budget to gate decisions — not just put a number on a dashboard.
Pick user-centric SLIs, set realistic agreed SLO targets, derive the error budget as 1 minus the SLO, alert on burn rate (fast and slow), let the budget gate releases, and review ship-vs-harden with product.How to answer
Start from user-centric SLIs — latency, availability, correctness — the things a user actually experiences, not internal proxies.
Set SLO targets that are realistic and agreed with product, so the number has buy-in and can be defended.
Derive the error budget as one minus the SLO, and treat it as the currency for risk-taking.
Alert on burn rate with both fast and slow windows, so you catch sudden cliffs and slow leaks without paging on noise.
Let the budget gate releases — freeze risky changes when it is spent — and review ship-vs-harden with product on the data.
What the interviewer is looking for
SLIs that map to real user experience, not vanity metrics.
Targets set with product buy-in, not chosen unilaterally.
Error budgets that actually change behavior — release gates, not decoration.
Burn-rate alerting that balances sensitivity against noise.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
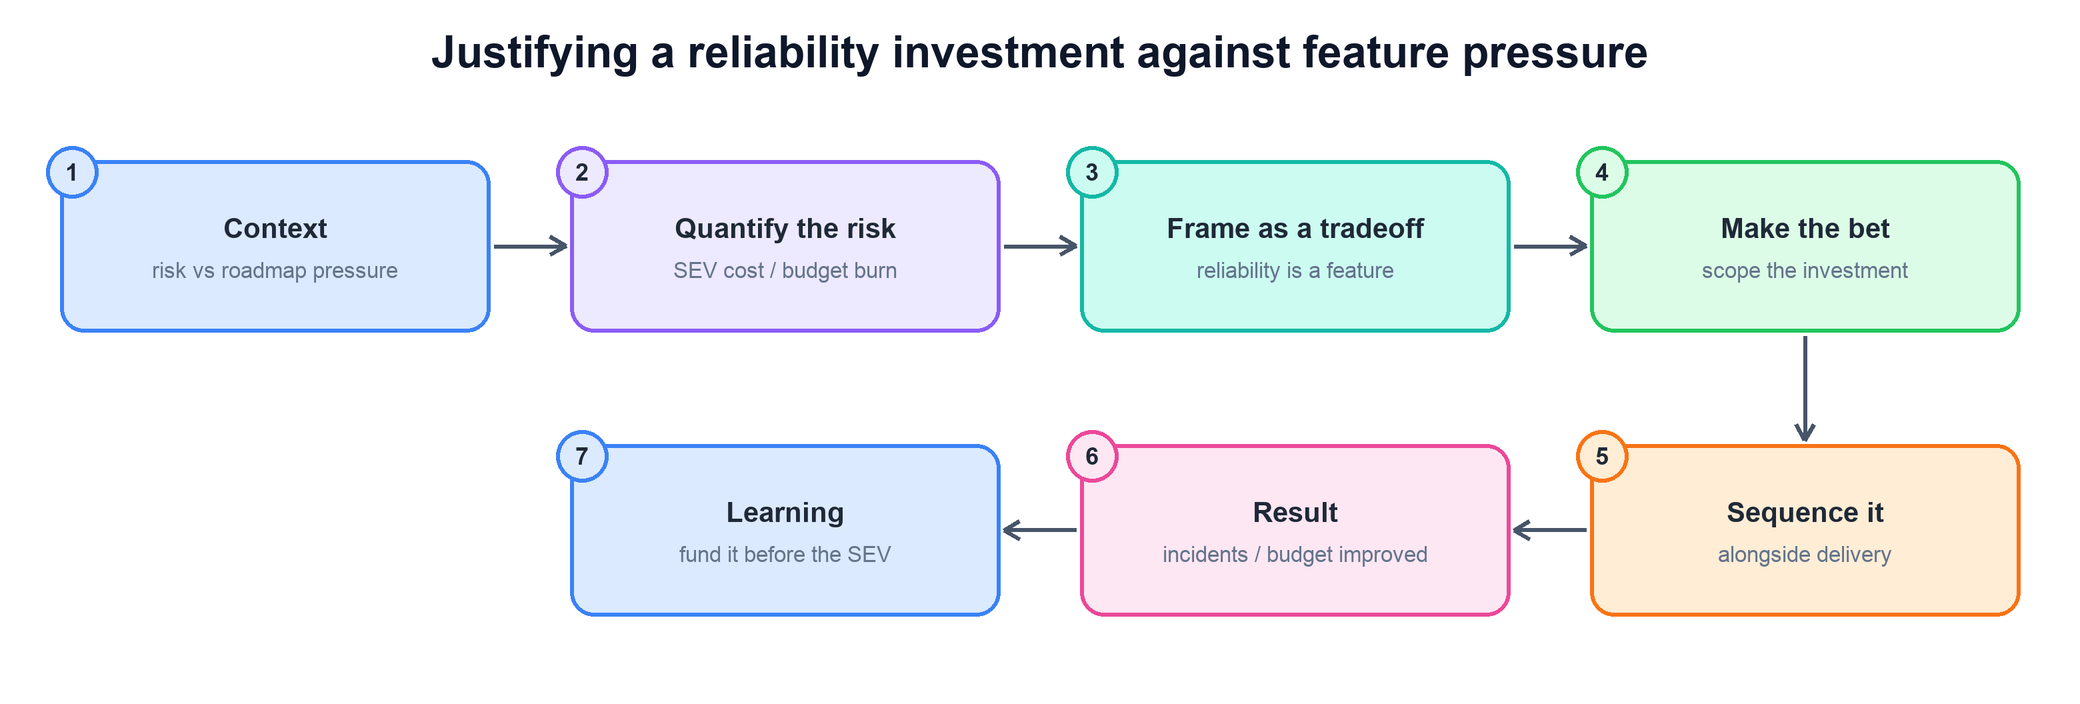
Tell me about a reliability investment you had to justify against feature pressure.
An influence-and-tradeoff question. They want to see you make the case for reliability work when the roadmap is loud — quantifying the risk, framing reliability as a feature, and sequencing the bet alongside delivery.
Context → quantify the risk in SEV cost and budget burn → frame it as a tradeoff (reliability is a feature) → make the bet → sequence it alongside delivery → result → learning.How to answer
Set the context: the reliability risk you saw and the feature-roadmap pressure pushing against fixing it.
Quantify the risk in terms leadership feels — SEV cost, hours of toil, or error-budget burn — not "it feels fragile."
Frame it as a tradeoff: reliability is a feature with ROI, and shipping on a system that is burning its budget is borrowing against the future.
Make the bet — scope the investment to the smallest version that meaningfully moves the risk — and sequence it alongside delivery rather than blocking it.
Land the result (incidents down, budget recovered) and close with the learning: fund the fix before the SEV forces your hand.
What the interviewer is looking for
Risk quantified in business terms, not engineering anxiety.
Reliability framed as a tradeoff with ROI, not a tax.
A scoped, sequenced bet — not "stop everything to fix it."
Influence: you won the investment without owning the roadmap.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
More questions you might get — SRE Partnership
All of these reduce to the same spine: set a defensible SLO, spend the error budget on purpose, mitigate before you debug, fix the system not the symptom, and protect your people. Have a story ready for each.
What's the difference between an SLI, an SLO, and an SLA — and how do you use each?
How to answer
SLI is the measurement — a user-centric signal like latency, availability, or correctness.
SLO is the target you set on that SLI internally — the line you agree to defend, never 100%.
SLA is the contract — the externally promised number with consequences; keep it looser than the SLO so you have headroom.
Use them as a stack: measure the SLI, gate decisions on the SLO and its error budget, and protect the SLA from ever being threatened.
How do you decide whether a service is reliable enough?
How to answer
Anchor on the user, not perfection — "enough" is the SLO where extra nines stop being worth the cost.
Watch the error budget: if it is consistently underspent you are over-investing and could ship faster.
Set the target with product so reliability is a budgeted business tradeoff, not an engineering preference.
Revisit on data — re-tune the SLO when usage, dependencies, or user expectations change.
Tell me about a postmortem that changed how your team operates.
How to answer
Context: name the incident in two sentences — what broke and why the postmortem mattered.
Actions: ran it blameless, separated human from system, and dug to the systemic cause and the detection gap.
Results: the durable change it produced — a new guardrail, alert, or process — with a metric like recurrence gone or MTTR down.
Learnings: the operating habit it left behind — how the team reviews or builds differently now.
How do you design alerting that pages on symptoms without drowning on-call in noise?
How to answer
Page on symptoms, what the user feels — latency, errors, availability — not every internal cause.
Tie pages to the SLO via burn-rate alerts: fast windows for sudden cliffs, slow windows for quiet leaks.
Every page must be actionable — if there's no human action, it's a dashboard or a ticket, not a page.
Audit noise relentlessly — review the noisiest alerts and tune, automate, or delete them at the root.
How do you handle a chronically unreliable dependency you don't own?
How to answer
Quantify the impact first — how much of your error budget the dependency burns — so the conversation is data, not blame.
Defend your boundary: timeouts, retries with backoff, circuit breakers, and graceful degradation so its failures don't become yours.
Make it the owner's problem with evidence — an SLO expectation backed by your burn data, escalated through the right channel.
Have a fallback plan — cache, secondary path, or feature flag — for when it fails anyway.
Describe a time you had to push back on shipping because of reliability risk.
How to answer
Context: the change under pressure to ship and the concrete reliability risk it carried.
Actions: framed it on the error budget — shipping while the budget is spent is borrowing against the future — and proposed a scoped path to ship safely.
Results: the outcome — a guardrail added, rollout staged, or release gated — and the incident you avoided.
Learnings: show influence without authority — you won on data and tradeoffs, not by blocking.
How do you build a blameless culture when an outage was clearly someone's mistake?
How to answer
Reframe the question: ask what let one person's action take the system down, not who did it.
Fix the system — the missing guardrail, review, or safety check — so the same mistake can't recur.
Model it as the leader: people surface failures honestly only when they're safe, which is how you find real root causes.
Separate accountability from blame — learning is shared and systemic; punishment just drives the next failure underground.
Before the loop: pre-load one hard number per story (MTTR cut, pages-per-week dropped, error budget recovered, SEVs avoided). Many reliability answers live or die on a single metric — pull it from the SEV review tool, the on-call tool, or your Unidash SLA dashboards ahead of time so you are not estimating in the room.
Worked example: one million requests and a 99.9% target
This example illustrates how to explain reasoning and evidence without overstating a result.
Sequence for this example. The table explains the evidence and decision at each step.
Step
Evidence, decision, and expected result
Define the SLI
For request success, specify eligible good/total events and measurement window.
Calculate allowed bad requests
1,000,000×0.001=1000. This is not automatically a downtime allowance under variable traffic.
Choose policy and alerts
Use sufficient observations, denominator/no-data handling, multi-window burn, and the team's agreed risk policy.
Explain actual improvement
Report coverage, user impact, recovery, and sustainable workload; page reduction alone can hide missed detection.
Check your understanding: Is an SLA always weaker than an SLO?
Not universally. Their definitions/windows and contractual scope can differ; compare the actual promises.
Practice with your own situation
Draft a concise real example: context, your actual role, constraints, alternatives, decisions/actions, evidence-based result with limits, and one learning. Do not invent metrics or copy someone else's claims.
Use genuine, safe-to-share evidence. Example numbers here illustrate reasoning; they are not claims about your work or a guaranteed outcome.