How to answer the operational-leadership questions in a senior engineering-leadership loop: the framework to structure each answer, what the interviewer is really listening for, and where inside Meta to pull the evidence that backs your story.
Student edition · understand, apply, verify
Explain operational leadership through safe recovery, measurement, ownership, and sustained improvement.
What you should be able to do: Show how actions preserved user outcomes and sustainable workload, not only output counts.
Practice guidance for your own truthful, authorized experience. Frameworks help organize decisions/evidence; they do not guarantee results or verify personal claims. Technical risk, privacy, fair personnel processes, and decision rights remain explicit.
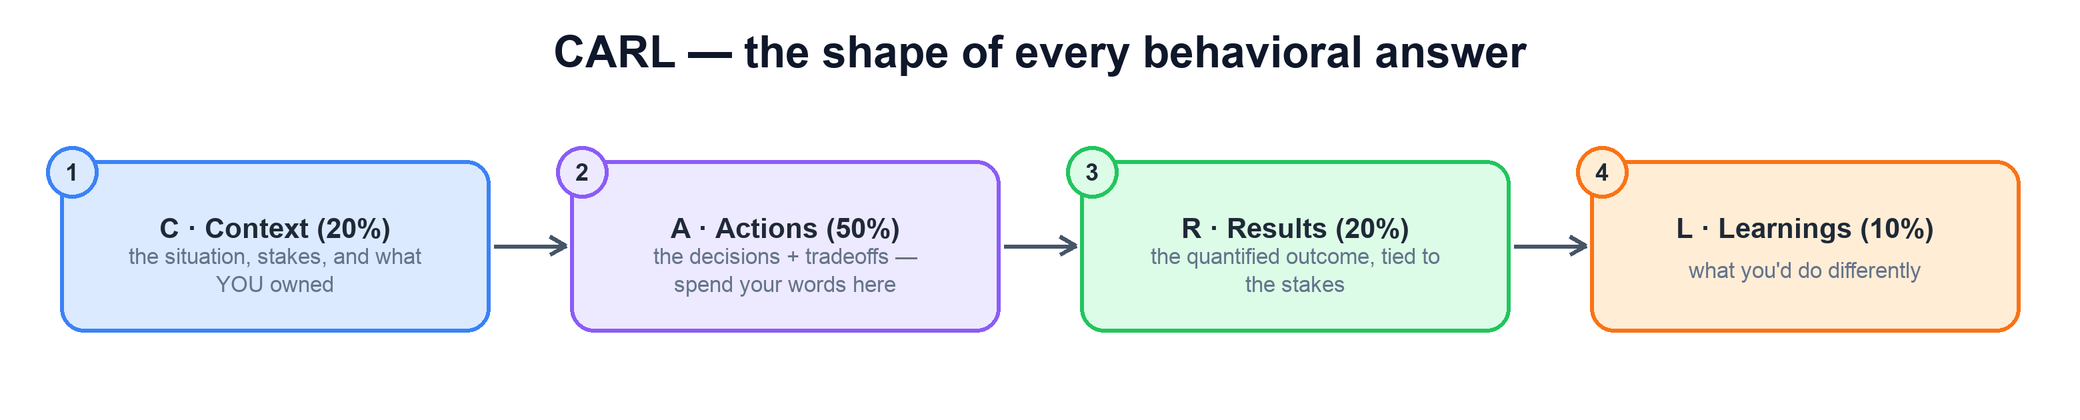
This area tests one thing: can you keep a system and a team healthy under load — reliably, cheaply, and at quality — week after week. Interviewers are not grading whether you can fight a single fire; they assume you can. They are grading operating judgment: did you watch the few metrics that matter, run a cadence that surfaces problems early, triage by impact when you can't do everything, assign clear ownership, and drive durable fixes instead of band-aids. Every answer below is built on the CARL shape — Context, Actions, Results, Learnings — with most of your words spent on the decisions and tradeoffs.
CARL is the shape of every behavioral answer. Spend ~50% of your words on Actions — the decisions only you could have made — and never drop Results or Learnings.
Read these definitions first, or use the linked terms as you go. The examples and limitations are local to this guide; companion pages are optional.
STAR and CARL interview structure
STAR means Situation, Task, Action, Result. CARL means Context, Action, Result, Learning. They distinguish conditions, responsibility, personal decisions, and outcomes.
Example. Describe the team's problem, your role, what you personally changed, and measured results; add a tradeoff and learning.
Boundary. Use genuine safe-to-share evidence. A framework does not authorize invented achievements or someone else's story.
Toil, incident response, and error budgets
Toil is repetitive operational work that scales without lasting improvement. Incident response restores safe service first; an error budget relates risk to a user-defined SLO.
Example. Automate a repeatedly safe recovery after checking failure cases, and measure reduced effort/errors with an operator escape path.
Boundary. Not all recurring work is waste. Automation can amplify errors; preserve necessary safety controls. Budgets are policy, not universal mandates.
Ownership, accountability, and decision rights
Ownership names who drives follow-through; accountability names who answers for outcomes. Decision rights specify who chooses/approves and who is consulted.
Example. A migration has a coordinating owner, service owners, and named release authority.
Boundary. DRI/RACI/DACI are local conventions, not guarantees. Role labels do not replace authority, capacity, and follow-through.
Outputs, outcomes, and measurement
Outputs are produced things; outcomes are changes for users/business/team. Useful metrics state definition, denominator, population, period, and attribution limits.
Example. 'Shipped a tool' is output. 'Median onboarding fell ten to six days in this cohort' is an outcome with sample/context caveats.
Boundary. Before/after does not prove sole causation. Avoid gaming, selection bias, hidden costs, and unlike-team comparisons.
SLIs, SLOs, and error budgets
An SLI measures a user-relevant outcome; an SLO sets its target over a window. For a success-ratio SLO, the allowed bad fraction is 1−SLO. An SLA is a contractual commitment that may use different definitions.
Example. 99.9% successful requests over 1 billion requests allows 1 million bad requests. A time-based 30-day availability target instead allows 43.2 unavailable minutes.
Boundary. Request and time budgets are not interchangeable under variable traffic or partial failure. SLOs are not universally stricter than SLAs; choose both from their definitions and user needs.
How to use this page. For each question: read the flow diagram to fix the shape of the answer in your head, scan the How to answer bullets, check what the interviewer is listening for, then pull one hard number from the Meta sources listed before the loop. The pages are intentionally generic — bring your own story to each flow.
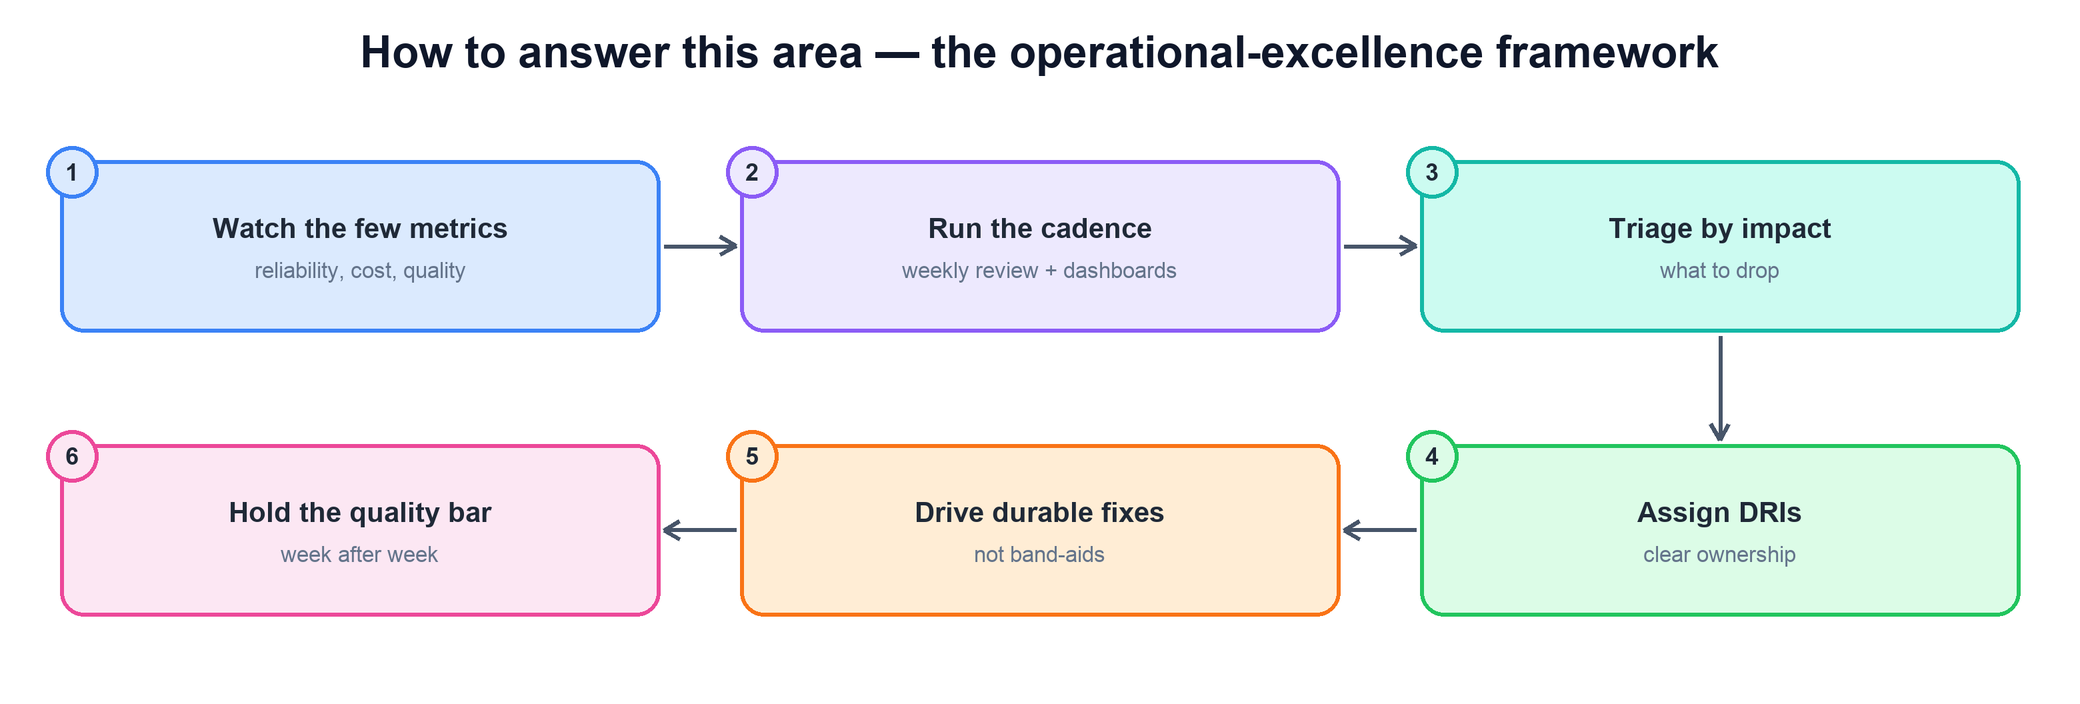
How to answer this area — the operational-excellence framework
Every operational question can be answered with the same spine. Walk it in order and you will hit the signals interviewers look for without sliding into a war story about one outage.
The operations spine: watch the few metrics that matter, run a cadence that surfaces issues, triage by impact, assign DRIs, drive durable fixes, and hold the quality bar over time.How to answer
Watch the few metrics. Name the small set of signals that actually predict health — reliability, cost, quality — and ignore the vanity dashboards.
Run the cadence. A weekly review against live dashboards beats heroics; the cadence is what catches problems while they are still small.
Triage by impact. When you can't do everything, decide what to drop on impact, not on who is loudest. Saying what you didn't fix is a seniority signal.
Assign DRIs. Every issue gets one named owner accountable to closure — no shared ownership, no orphaned action items.
Drive durable fixes. Push past the band-aid to the root cause; an outage that recurs is an operating failure, not bad luck.
Hold the quality bar. Standards only count if they survive the week you are under pressure. Show how the bar held when it was expensive to hold.
What the interviewer is looking for
A small, defensible set of health metrics — not a dashboard with forty charts.
A repeatable cadence that catches problems early, not reactive firefighting.
Real triage: a costly thing you chose not to fix, and why.
"I" for the operating decisions, "we" for how the team executed.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
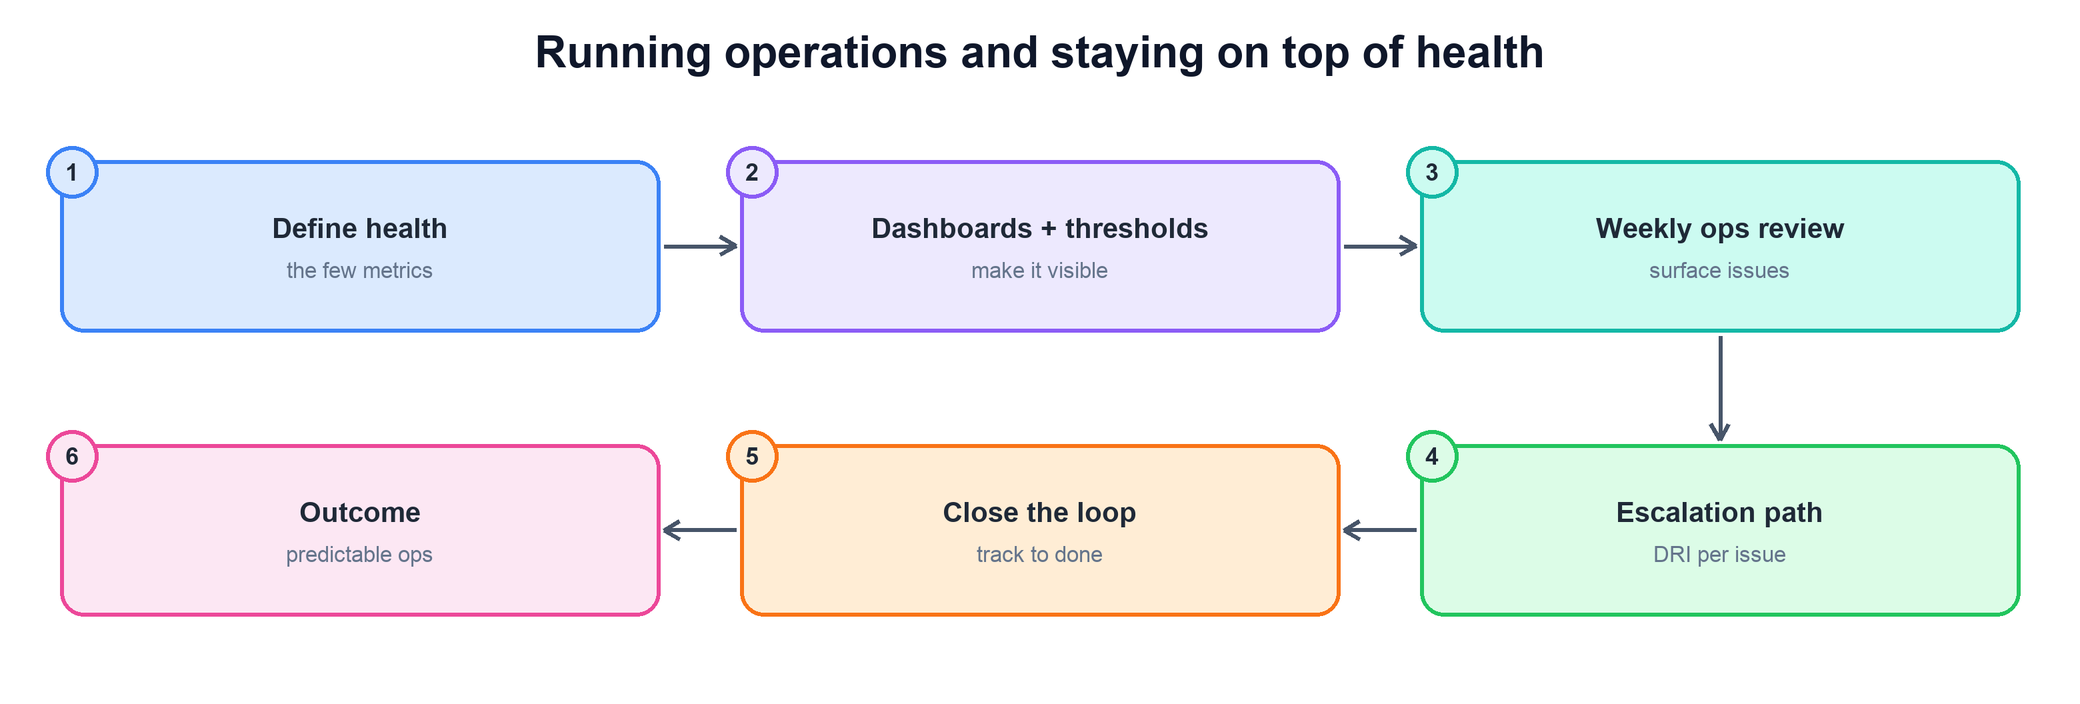
How do you run your team's operations and stay on top of its health?
The foundational question for this area. They want to see a system for staying ahead of problems — not a description of how hard your team works when something breaks.
Define health → dashboards with thresholds → weekly ops review → escalation path with a DRI per issue → close the loop to done → predictable ops.How to answer
Start by defining health — the few metrics that actually predict whether the system is in trouble, and why you chose those.
Make health visible with dashboards and thresholds so a degradation is obvious before a customer notices it.
Describe the weekly ops review where the team looks at the signals together and surfaces issues while they are cheap to fix.
Give every issue an escalation path with a DRI, so nothing falls between owners.
Close the loop: track each issue to done and confirm the metric recovered — then describe the predictable, low-surprise ops state you reached.
What the interviewer is looking for
A deliberate operating model, not ad-hoc reaction.
Leading indicators and thresholds, not lagging post-mortems only.
Clear ownership: one DRI per issue, tracked to closure.
Evidence the system became more predictable over time.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
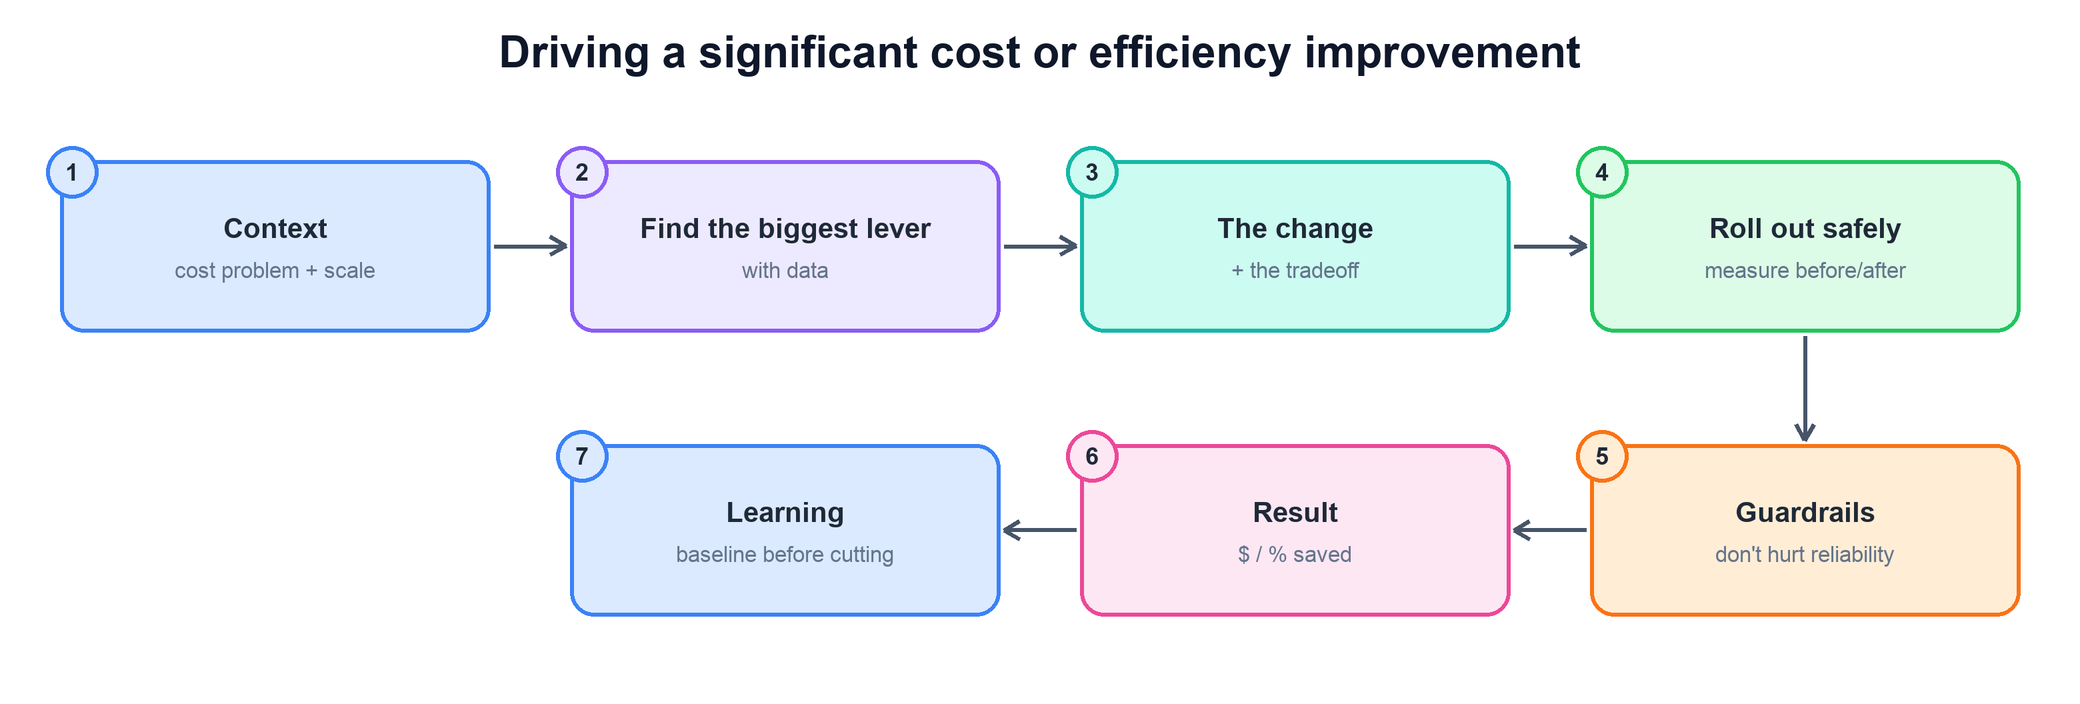
Tell me about a time you drove a significant cost or efficiency improvement.
This question tests whether you can find the biggest lever with data, make a real change with a real tradeoff, and prove the savings — without quietly breaking reliability to get them.
Context → find the biggest lever with data → the change and its tradeoff → roll out safely with before/after measurement → guardrails on reliability → quantified result → learning.How to answer
Open with the context and scale: what the cost problem was and why it was worth your time.
Show how you found the biggest lever with data — you went after the dominant cost driver, not the easiest one.
Name the change and the tradeoff you accepted; an efficiency win with no tradeoff usually means you didn't look hard enough.
Roll out safely with a baseline captured up front, so the before/after number is credible.
Describe the guardrails that kept reliability whole, land a quantified result in dollars or percent, and close with the learning — baseline before you cut.
What the interviewer is looking for
Data-driven lever-finding, not across-the-board belt-tightening.
An explicit tradeoff you owned, not a free lunch.
A baseline captured before the change, so the savings are real.
Reliability protected — cost won without a quality regression.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
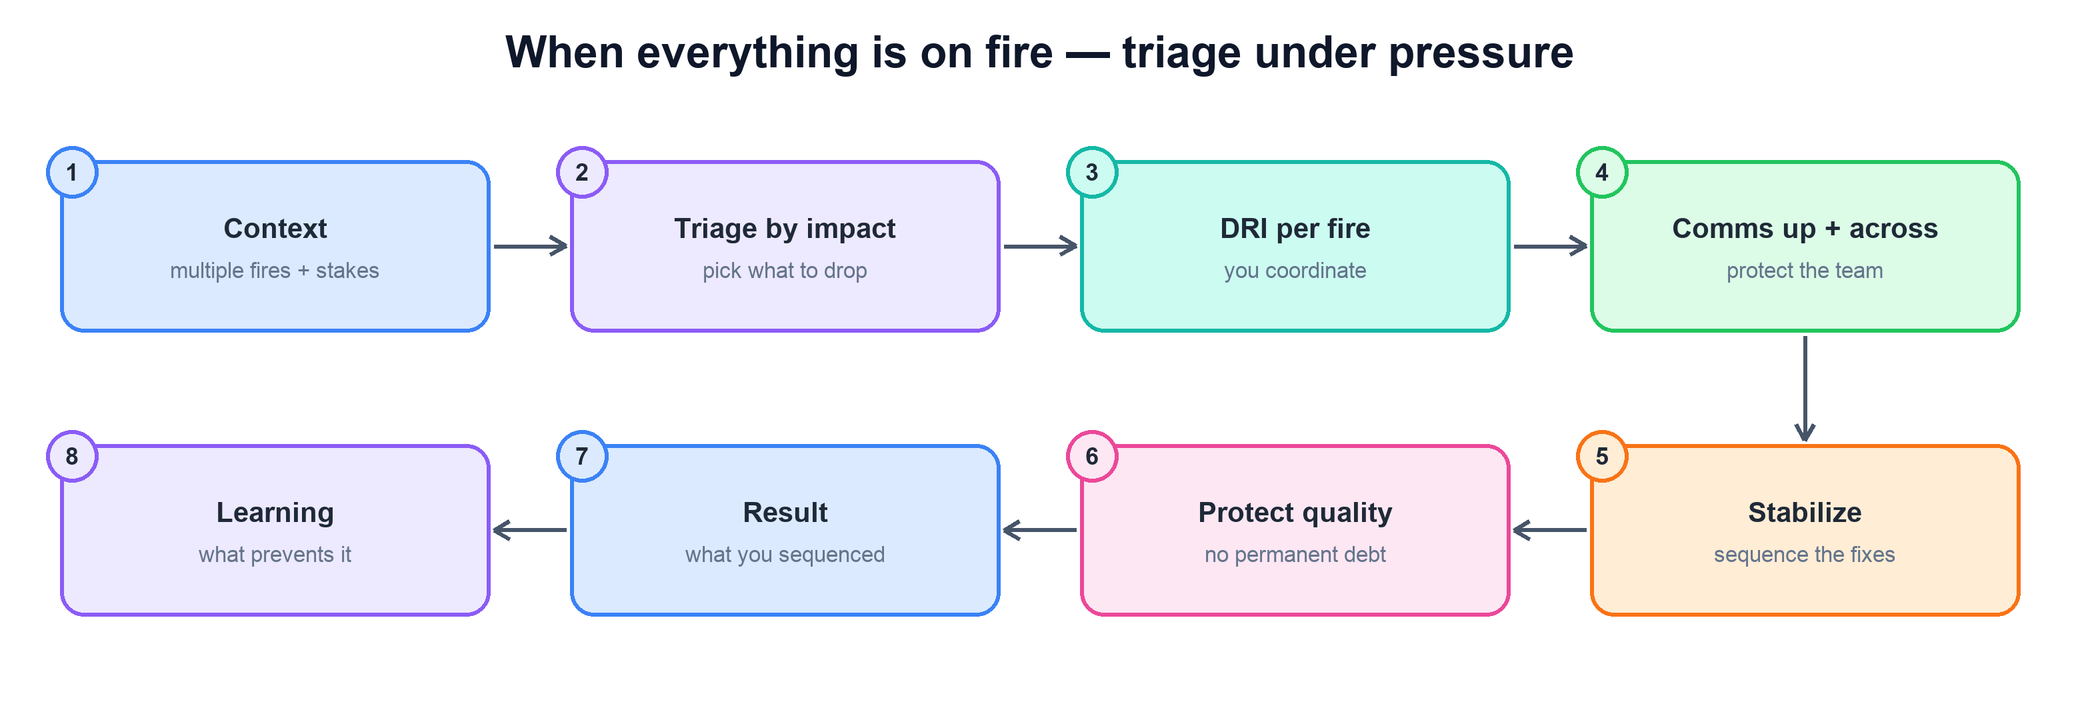
Tell me about a time everything was on fire at once. How did you triage, and how did you protect quality under pressure?
The signal here is composure and prioritization under load: with more fires than hands, can you sequence the response, protect the team, and refuse to mortgage quality for speed.
Context → triage by impact and pick what to drop → a DRI per fire while you coordinate → comms up and across → stabilize by sequencing the fixes → protect quality → result → learning.How to answer
Set the context and stakes: multiple concurrent fires and what was actually at risk.
Triage by impact and say out loud what you chose to drop — the willingness to let a low-impact fire burn is the seniority signal.
Put a DRI on each fire while you stay at the coordination layer rather than diving into one yourself.
Run comms up and across so leadership and partners are calm, and the team is shielded from the churn.
Stabilize by sequencing the fixes, protect quality so no permanent debt is left behind, then state the result and the learning about what prevents the next pile-up.
What the interviewer is looking for
Impact-based triage and a deliberate, named drop.
Delegation under pressure — a DRI per fire, you coordinating.
Calm comms that protected both stakeholders and the team.
Quality held: no permanent debt taken on for short-term relief.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
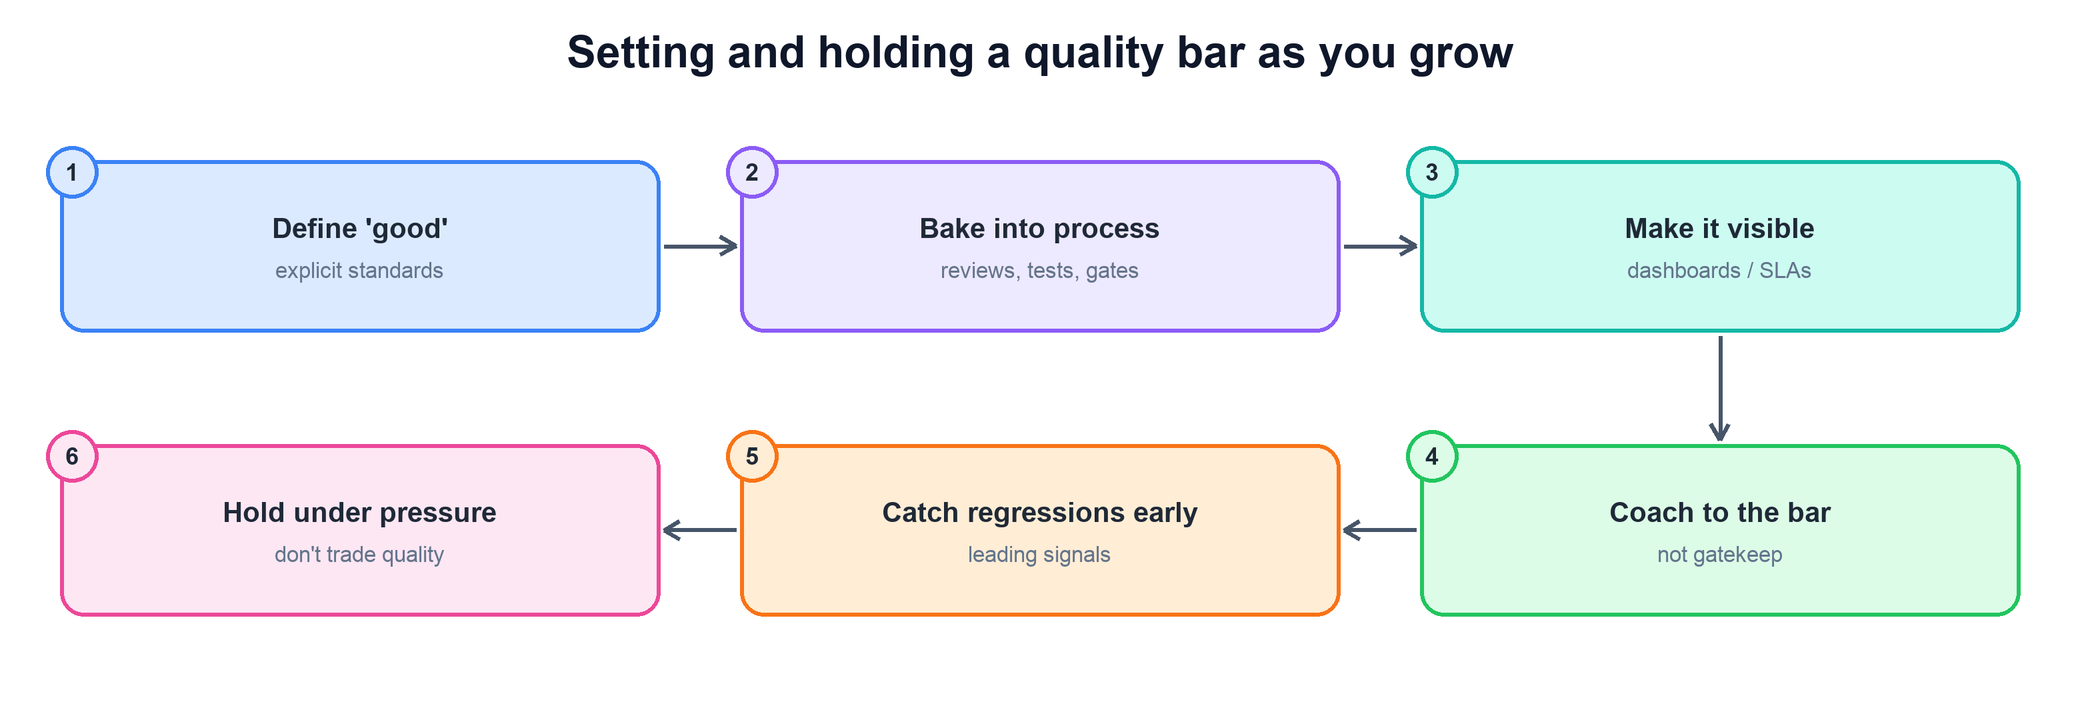
How do you set and hold a quality bar as the team grows?
An added question. As headcount climbs, quality drifts unless it is made explicit and built into the process. They want to see you define "good," bake it in, and keep it intact when delivery pressure rises.
Define "good" with explicit standards → bake it into reviews, tests, and gates → make it visible → coach to the bar rather than gatekeep → catch regressions early → hold under pressure.How to answer
Start by defining "good" explicitly — standards a new engineer can read and apply, not a feeling in your head.
Bake the bar into the process: code review norms, test requirements, and gates that make the easy path the high-quality path.
Make quality visible with dashboards or SLAs so a slip is obvious to the whole team, not just to you.
Coach to the bar instead of gatekeeping: scale quality by raising people, not by being the only reviewer who says no.
Catch regressions early with leading signals, and show a moment you held the bar under pressure when it would have been easier to ship and skip it.
What the interviewer is looking for
An explicit, written standard — not tribal knowledge.
Quality built into process and tooling, so it scales past you.
Coaching that raises the team, not a personal gatekeeping bottleneck.
The bar held when delivery pressure made it costly.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
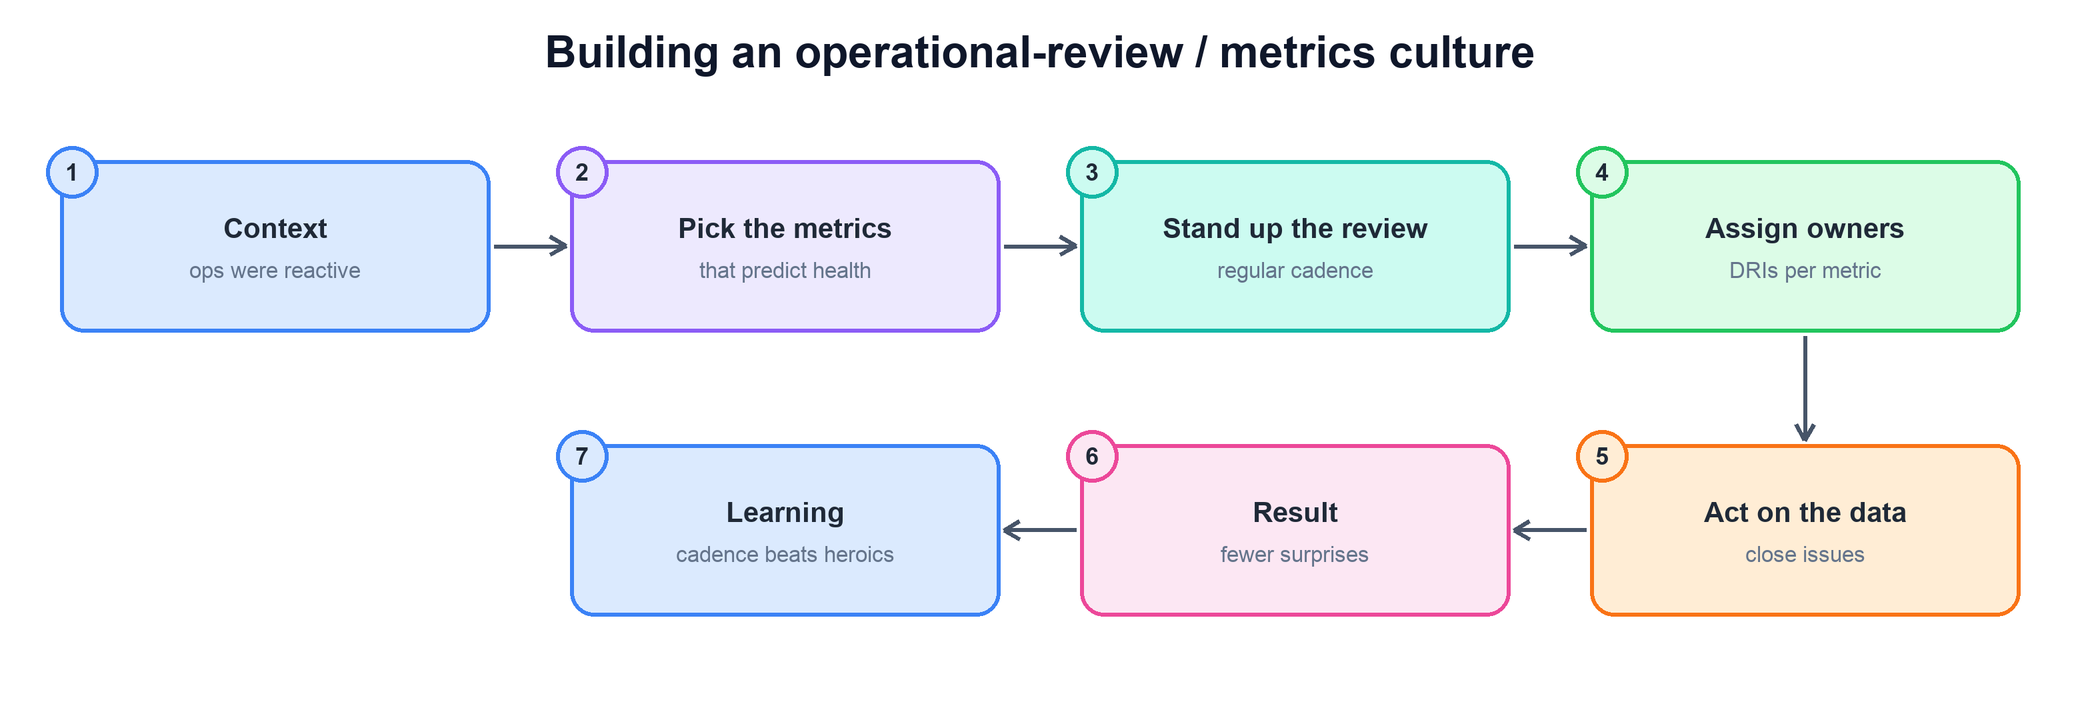
Tell me about building an operational-review or metrics culture.
An added question. The signal is installing a durable operating habit: moving a team from reactive firefighting to a regular review where the data drives the decisions.
Context → pick the metrics that predict health → stand up the review on a regular cadence → assign owners per metric → act on the data to close issues → fewer surprises → learning.How to answer
Open with the context: operations were reactive and surprises kept landing late.
Pick the metrics that predict health — the leading signals, not the comfortable ones — and explain why those.
Stand up the review on a regular cadence so the team looks at the data together before problems compound.
Assign owners per metric so each signal has a DRI who answers for its trend.
Act on the data to close issues — a review that doesn't change behavior dies — then land the result (fewer surprises) and the learning that cadence beats heroics.
What the interviewer is looking for
A genuine culture shift from reactive to proactive, not a one-off meeting.
Metrics chosen for predictive value, with an owner each.
The review changing behavior — issues closed, not just discussed.
A durable habit that outlived your direct attention.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
More questions you might get — Operational Leadership
All of these reduce to the same spine: watch the few metrics, run a cadence, triage by impact, give owners and durable fixes, and protect quality. Have a story ready for each.
How do you decide which metrics are worth tracking — and which dashboards to delete?
How to answer
Tie every metric to a decision — if no action changes when it moves, it is noise, not a signal.
Favor leading indicators that predict health over lagging counts that only confirm the damage.
Keep the set small and defensible: a handful that predict reliability, cost, and quality beats a wall of forty charts.
Delete on a cadence — retire dashboards no one acts on, so attention stays on the few that matter.
Tell me about a recurring incident. How did you break the cycle for good?
How to answer
Context: name the incident that kept recurring and what each repeat actually cost.
Find the root cause, not the symptom — a repeat fire means the band-aid never reached the real defect.
Drive a durable fix with a DRI and a guardrail that makes the failure mode impossible, not just unlikely.
Results and learning: show the recurrence rate dropping to zero and the mechanism that catches the next one early.
How do you balance reliability investment against feature delivery pressure?
How to answer
Make the tradeoff explicit with an error budget or SLA, so the choice is a number, not a gut feeling.
Let the signal gate the work: when reliability is in budget, ship features; when it is spent, the team pays down debt.
Frame reliability as enabling delivery — an unstable system slows every future feature, so the investment compounds.
Decide by impact and say what you deprioritized, so the balance reads as judgment rather than avoidance.
Describe a time you had to make a call with incomplete data during an outage.
How to answer
Context: set the stakes and the unknowns — what you did and did not know when the clock was running.
Decide on the safest reversible move first; mitigate impact before you fully understand the cause.
Reason from impact and a hypothesis, state your assumptions out loud, and keep comms flowing while you act.
Results and learning: show the outcome and the instrumentation you added so the next call is made with data.
How do you keep an on-call rotation healthy and sustainable as the team scales?
How to answer
Measure the load — track pages per shift and toil, and treat a noisy rotation as a bug to fix, not a tax to absorb.
Attack alert fatigue: tune or delete low-value alerts so every page is real and actionable.
Invest in runbooks and automation so responders are not improvising at 3am, and rotate fairly across the team.
Feed pain back into the backlog — recurring pages become prioritized fixes, keeping the rotation durable as headcount grows.
Tell me about a time you cut cost and it went wrong. What did you learn?
How to answer
Context: the cost you targeted and the cut you made — own it plainly rather than softening it.
Name what broke: the reliability or quality regression the cut caused because a guardrail or baseline was missing.
Actions to recover: how you detected it, rolled back, and restored health with clear ownership.
Learning: baseline and guardrail before you cut, and roll out behind a measured before/after so regressions surface early.
How do you run a blameless post-mortem that actually changes behavior?
How to answer
Focus on systems, not people — ask what let the failure happen, so people surface the real cause without fear.
Drive to root cause with a timeline and a few honest contributing factors, not a single scapegoat.
Produce owned, dated action items with a DRI each — a post-mortem with no tracked follow-through is theater.
Close the loop: track the items to done and show recurrence dropping, proving the review changed behavior.
Before the loop: pre-load one hard number per story (percent more reliable, dollars saved, SEVs avoided, hours of toil removed). Many operational answers live or die on a single metric — pull it from ODS, Unidash, the SEV tool, or your efficiency tooling ahead of time so you are not estimating in the room.
Worked example: a repeated incident is turned into a maintained fix
This example illustrates how to explain reasoning and evidence without overstating a result.
Sequence for this example. The table explains the evidence and decision at each step.
Step
Evidence, decision, and expected result
Clarify impact and role
State affected users, duration, evidence, and whether you coordinated, debugged, or made a risk decision.
Mitigate safely
Choose justified recovery with correct state/authority/rollback behavior and preserve evidence.
Prioritize owned improvements
Address contributing factors, tests, detection, and operational toil with owners and effectiveness checks.
Evaluate sustained outcomes
Compare incident/detection/workload metrics with coverage and context, acknowledging remaining risks.
Check your understanding: Does fewer incidents prove your intervention was the only cause?
No. Show evidence and alternatives; workload, reporting, traffic, and other changes can affect the comparison.
Practice with your own situation
Draft a concise real example: context, your actual role, constraints, alternatives, decisions/actions, evidence-based result with limits, and one learning. Do not invent metrics or copy someone else's claims.
Use genuine, safe-to-share evidence. Example numbers here illustrate reasoning; they are not claims about your work or a guaranteed outcome.