How to answer the technical-design questions in a senior engineering-leadership loop: the framework to structure each answer, what the interviewer is really listening for, and where inside Meta to pull the evidence that backs your story.
Student edition · understand, apply, verify
Explain technical leadership from requirements, alternatives, guarantees, and measured evidence.
What you should be able to do: State a genuine tradeoff and distinguish validation from proof or unsupported attribution.
Practice guidance for your own truthful, authorized experience. Frameworks help organize decisions/evidence; they do not guarantee results or verify personal claims. Technical risk, privacy, fair personnel processes, and decision rights remain explicit.
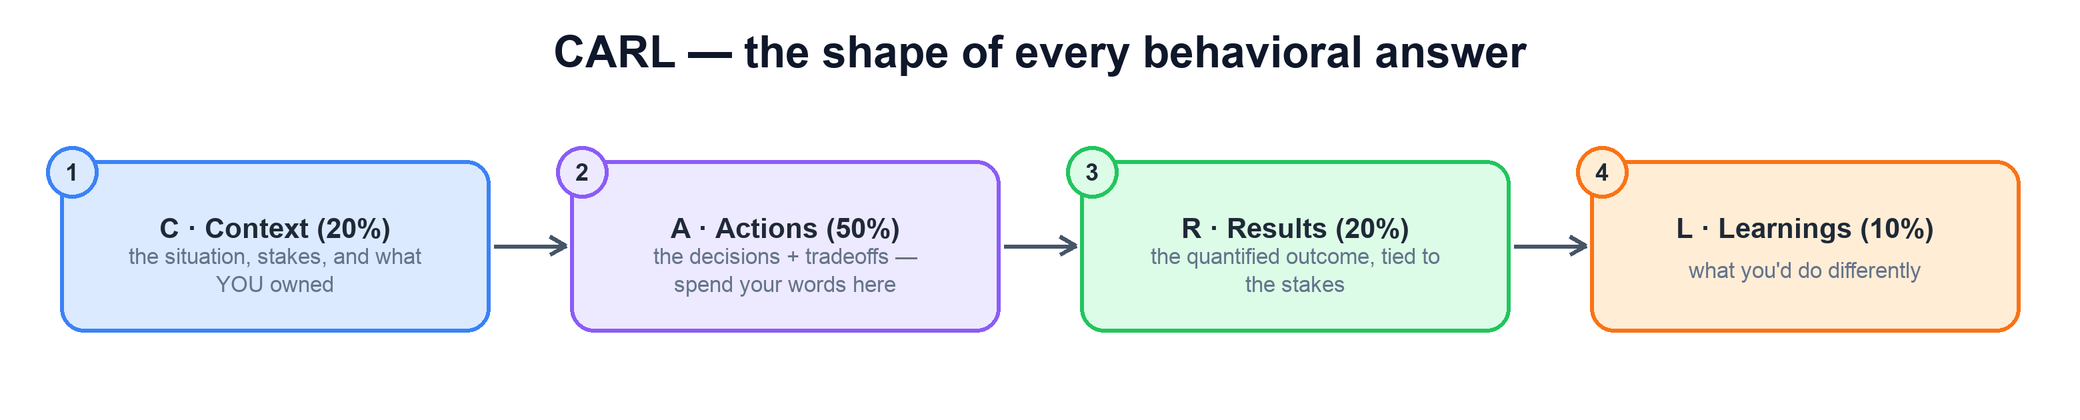
This area tests one thing: can you own a hard design decision, defend the tradeoff, and build a system that survives scale and failure. Interviewers are not grading whether you can draw boxes — they assume you can. They are grading judgment: did you understand the requirements, consider real alternatives, decide on an explicit axis, design for the failure case, and prove the design held up in production. Every answer below is built on the CARL shape — Context, Actions, Results, Learnings — with most of your words spent on the decisions and tradeoffs only you could have made.
CARL is the shape of every behavioral answer. Spend ~50% of your words on Actions — the design decisions and tradeoffs only you could have made — and never drop Results or Learnings.
Read these definitions first, or use the linked terms as you go. The examples and limitations are local to this guide; companion pages are optional.
STAR and CARL interview structure
STAR means Situation, Task, Action, Result. CARL means Context, Action, Result, Learning. They distinguish conditions, responsibility, personal decisions, and outcomes.
Example. Describe the team's problem, your role, what you personally changed, and measured results; add a tradeoff and learning.
Boundary. Use genuine safe-to-share evidence. A framework does not authorize invented achievements or someone else's story.
Decision records and reversible experiments
Record the problem, options, evidence, constraints, owner, chosen tradeoff, and reconsideration trigger. A reversible test reduces uncertainty before large commitment.
Example. Try one tenant with success/abort metrics and a data-safe rollback plan.
Boundary. Timeboxing does not bypass compliance/safety. Reversible means effects and data can actually recover, not merely that a flag exists.
Preconditions and postconditions
A precondition states required inputs/state before an operation. A postcondition states the result promised when those requirements hold and execution terminates normally. Together they make requirements testable.
Example. For sum_first(b,n), require integer 0≤n≤len(b) and numeric elements; promise the sum of b[0:n].
Boundary. State exceptions, mutation, numeric domains, and empty cases. A mathematical array range does not automatically validate a runtime input.
SLIs, SLOs, and error budgets
An SLI measures a user-relevant outcome; an SLO sets its target over a window. For a success-ratio SLO, the allowed bad fraction is 1−SLO. An SLA is a contractual commitment that may use different definitions.
Example. 99.9% successful requests over 1 billion requests allows 1 million bad requests. A time-based 30-day availability target instead allows 43.2 unavailable minutes.
Boundary. Request and time budgets are not interchangeable under variable traffic or partial failure. SLOs are not universally stricter than SLAs; choose both from their definitions and user needs.
Outputs, outcomes, and measurement
Outputs are produced things; outcomes are changes for users/business/team. Useful metrics state definition, denominator, population, period, and attribution limits.
Example. 'Shipped a tool' is output. 'Median onboarding fell ten to six days in this cohort' is an outcome with sample/context caveats.
Boundary. Before/after does not prove sole causation. Avoid gaming, selection bias, hidden costs, and unlike-team comparisons.
How to use this page. For each question: read the flow diagram to fix the shape of the answer in your head, scan the How to answer bullets, check what the interviewer is listening for, then pull one hard number from the Meta sources listed before the loop. The pages are intentionally generic — bring your own story to each flow.
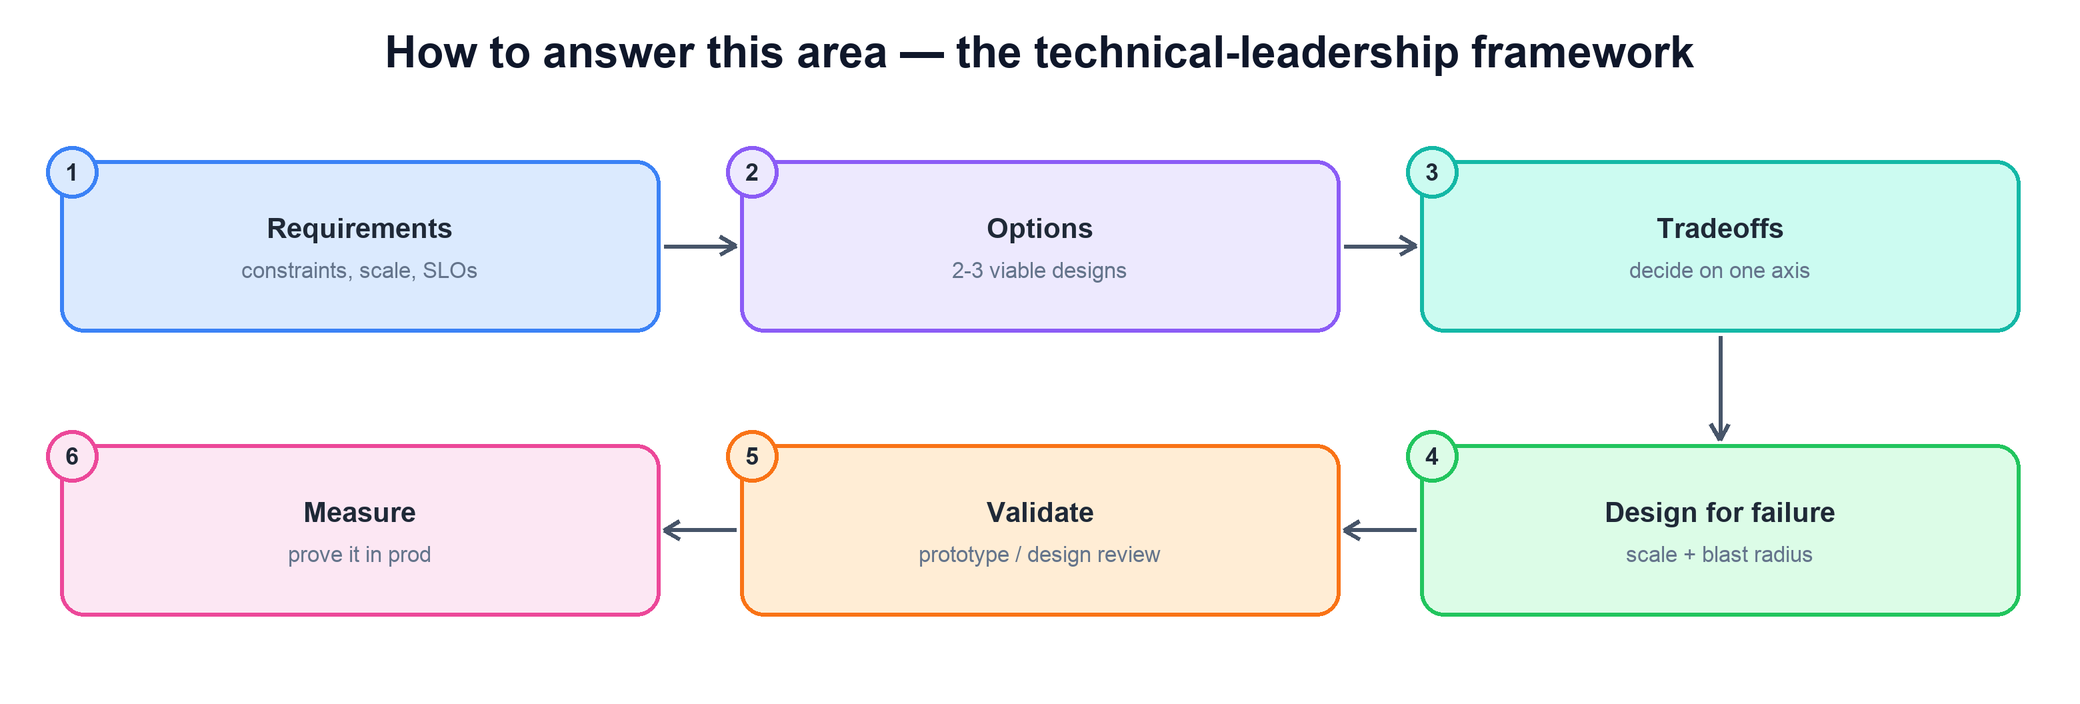
How to answer this area — the technical-leadership framework
A requirements/options/tradeoff/evidence structure is useful for many questions, but tailor it to the actual question and your role instead of treating one sequence as universally sufficient.
The design spine: pin the requirements, lay out a few real options, decide on one explicit axis, design for scale and the failure case, validate before you commit, and measure that it actually worked in prod.How to answer
Requirements first. State the constraints, the scale, and the SLOs before any design. The bar is whether you optimized for the right thing, not the clever thing.
Lay out real options. Name two or three viable designs, not one design and two strawmen. Show you saw the genuine forks in the road.
Decide on one axis. Make the tradeoff explicit — latency vs. consistency, cost vs. flexibility — and say which one you optimized and why.
Design for failure and scale. Talk through what breaks at 10x, what the blast radius is, and how the system degrades rather than collapses.
Measure production outcomes under explicit definitions and limitations; a before/after result does not prove universal correctness or sole causation.
What the interviewer is looking for
Requirements and constraints framed before any solution.
A real alternative considered and rejected for a stated reason.
One explicit, costly tradeoff — not "it was the best of both."
Failure thinking: blast radius, degradation, and recovery, not just the happy path.
"I" for the design calls you made, "we" for how the team built it.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
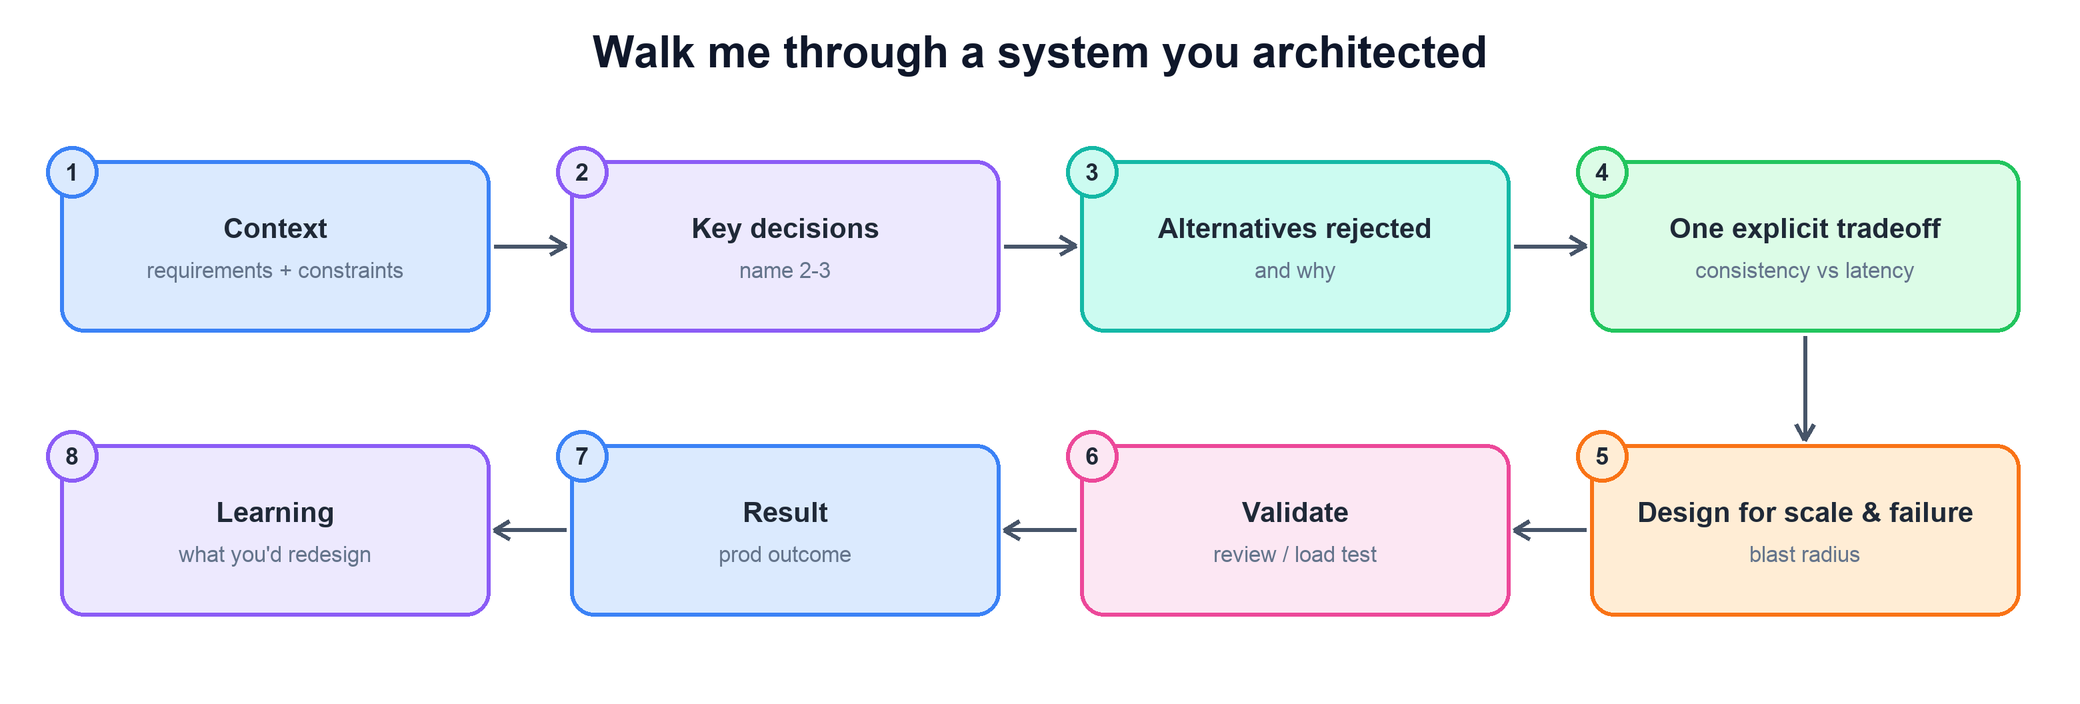
Walk me through a system you architected. What were the key design decisions?
The flagship question for this area. They want a system you owned at the design level — driven from requirements, narrowed through real alternatives, and proven in production.
Context → the key decisions → the alternatives you rejected → one explicit tradeoff → design for scale and failure → validate → result → what you'd redesign.How to answer
Open with the requirements and constraints in two sentences: the scale, the SLOs, and what you personally owned in the design.
Name the two or three key decisions that defined the architecture — the ones the whole design pivoted on.
State the alternatives you rejected and the concrete reason for each; this is the seniority signal.
Make one tradeoff explicit (for example consistency vs. latency) and explain how you designed for scale and the failure case — blast radius and degradation.
Land a production result tied to the opening requirements, and close with what you would redesign with hindsight.
What the interviewer is looking for
The design starts from requirements, not from a favorite technology.
Real alternatives weighed and rejected for stated reasons.
An explicit tradeoff, owned — not smoothed over.
Failure and scale thinking, plus a measured production outcome.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
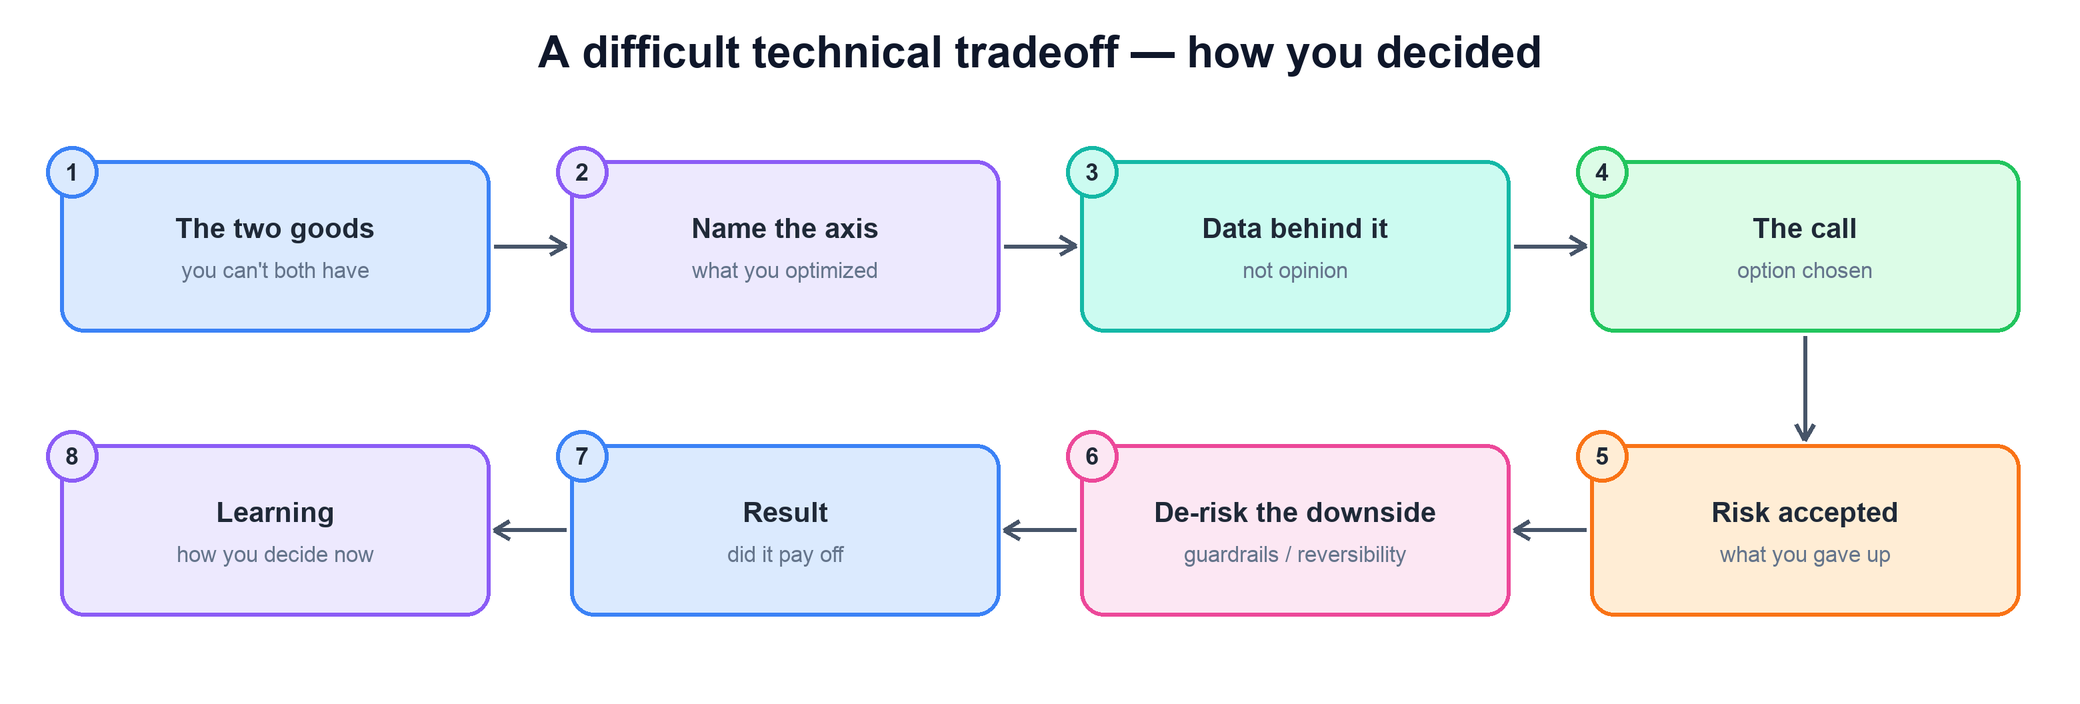
Tell me about a difficult technical tradeoff you had to make. How did you decide?
This question tests whether you can name two things that are both genuinely good, choose between them on data, and own what you gave up.
Name the two goods you can't both have, pick the axis you optimized, bring the data, make the call, accept the risk explicitly, de-risk the downside, and check whether it paid off.How to answer
Frame the two goods you could not have at once — that tension is what made it a real tradeoff.
Name the axis you optimized and why it was the one that mattered for this system.
Show the data behind the decision — a benchmark, a cost model, a load test — not opinion.
State the call you made, the risk you accepted, and how you de-risked the downside with guardrails or a reversible path.
Close with whether it paid off and the rule of thumb you now use to make this class of decision.
What the interviewer is looking for
A genuine tradeoff — two good options, not one obvious one.
A decision axis made explicit, decided on evidence.
Ownership of the cost: what you knowingly gave up.
Risk mitigation and reversibility built into the call.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
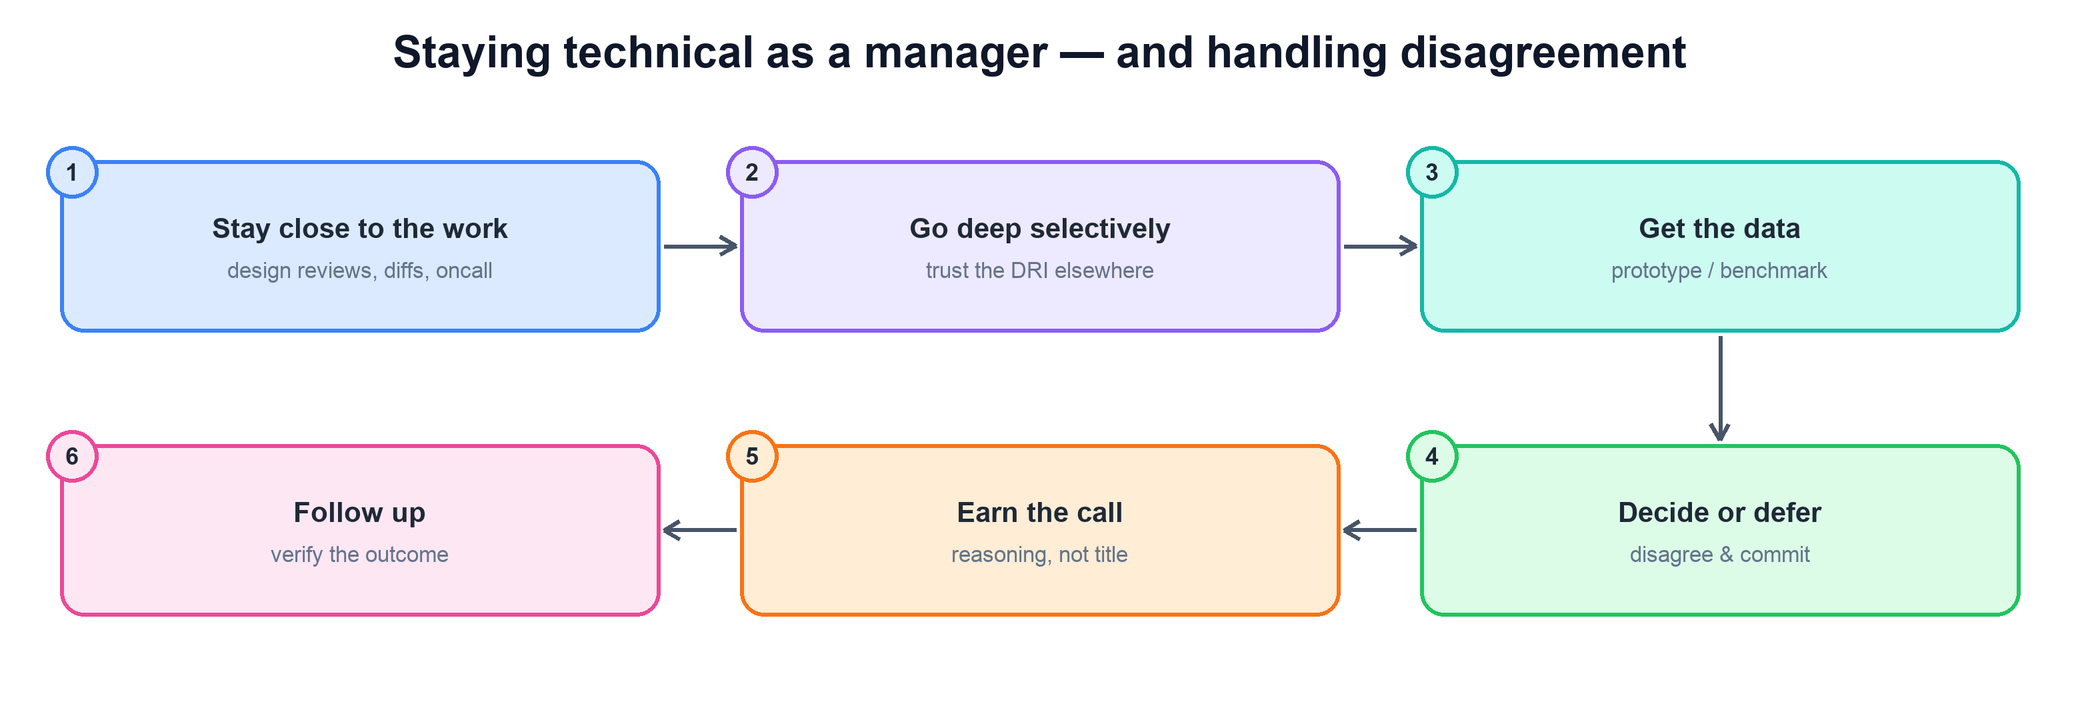
As a manager, how do you stay technical — and what do you do when you disagree with your team's technical direction?
The signal here is earned technical authority: staying close enough to the work to have a real opinion, going deep selectively, and resolving disagreement on reasoning rather than rank.
Stay close to the work, go deep selectively while trusting the DRI elsewhere, get the data, decide or defer with disagree-and-commit, earn the call on reasoning, and follow up to verify.How to answer
Describe how you stay close to the work — design reviews, reading diffs, taking oncall — so your opinion is grounded.
Explain that you go deep selectively on the highest-leverage decisions and trust the DRI on the rest.
When you disagree, get the data first: a prototype or a benchmark beats an argument from authority.
Then decide or defer — if you are still not convinced you make the call, but you disagree and commit when the team has the better evidence.
Stress that you earn the call on reasoning, not title, and you follow up to verify the outcome either way.
What the interviewer is looking for
Concrete habits that keep you technically current as a manager.
Selective depth — not micromanaging every decision.
Disagreement resolved on data and reasoning, not seniority.
Genuine disagree-and-commit, with follow-through to verify.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
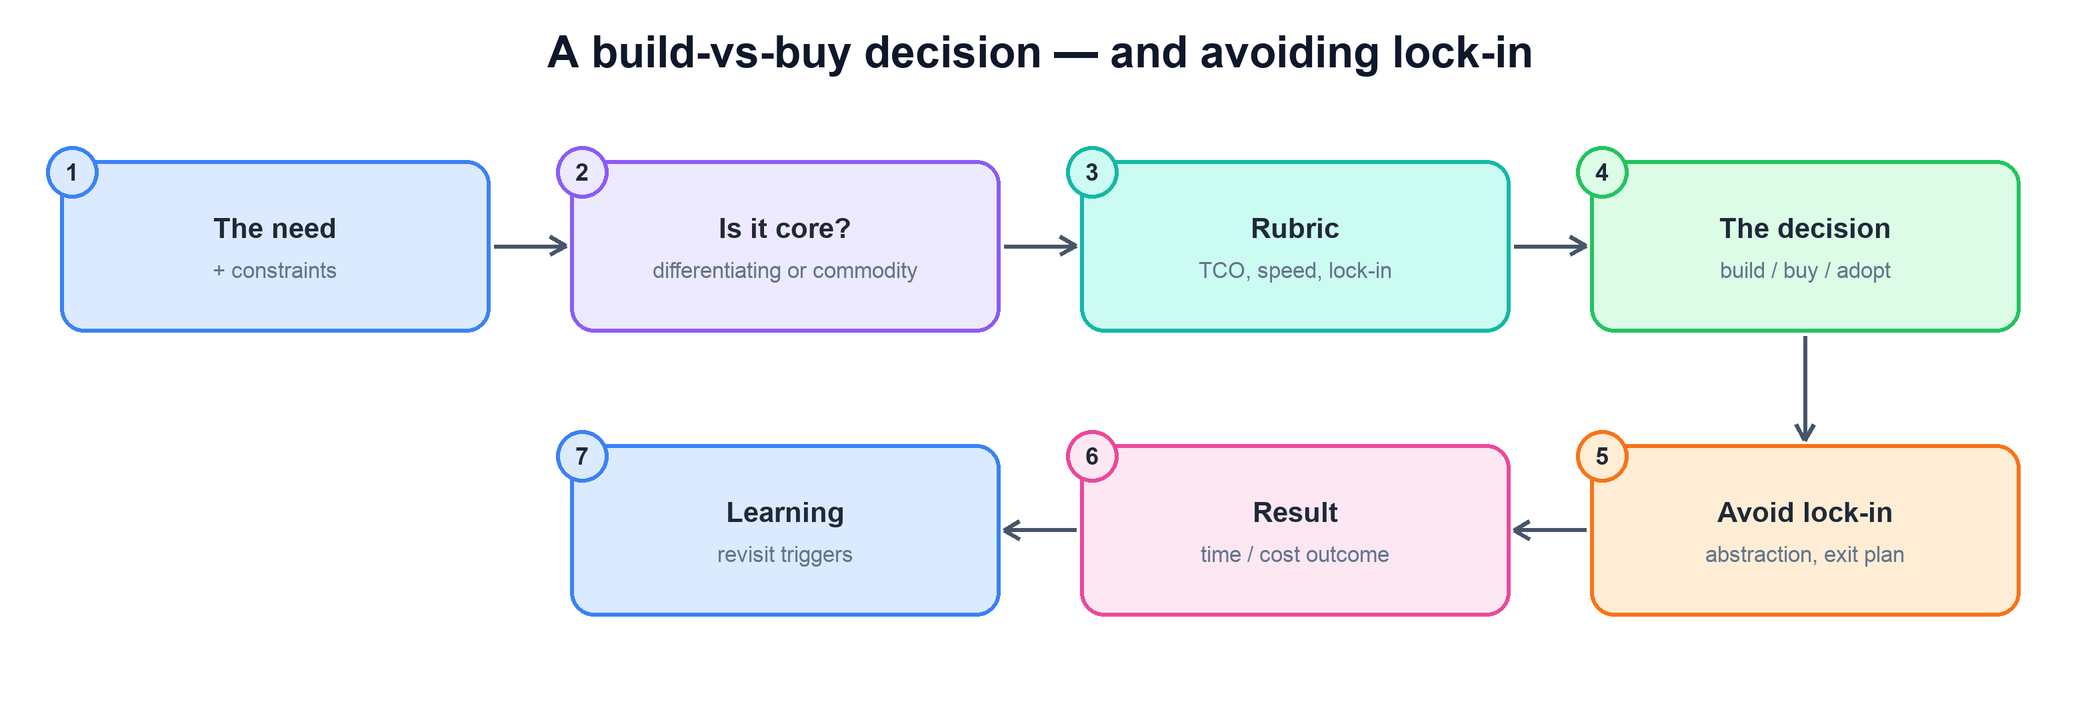
Tell me about a build-vs-buy decision you made. How did you decide, and how did you keep it from locking you in?
This question tests whether you can tell core from commodity, decide on a rubric rather than a preference, and protect the team's future optionality.
Start from the need and constraints, ask whether it is core or commodity, score on a rubric (TCO, speed, lock-in), make the build / buy / adopt call, design against lock-in, then check the outcome.How to answer
State the need and constraints — what the system actually had to do and by when.
Ask the key question: is this core? Differentiating work is worth building; commodity work usually is not.
Decide on an explicit rubric — total cost of ownership, time to value, and lock-in risk — not a gut preference.
State the decision (build, buy, or adopt an internal platform) and, critically, how you designed to avoid lock-in: an abstraction layer and a credible exit plan.
Close with the time or cost outcome and the triggers that would make you revisit the choice.
What the interviewer is looking for
A clear core-vs-commodity judgment, not "build everything."
A decision rubric, including total cost of ownership over time.
Lock-in addressed deliberately — abstraction and an exit path.
Awareness of when the decision should be revisited.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
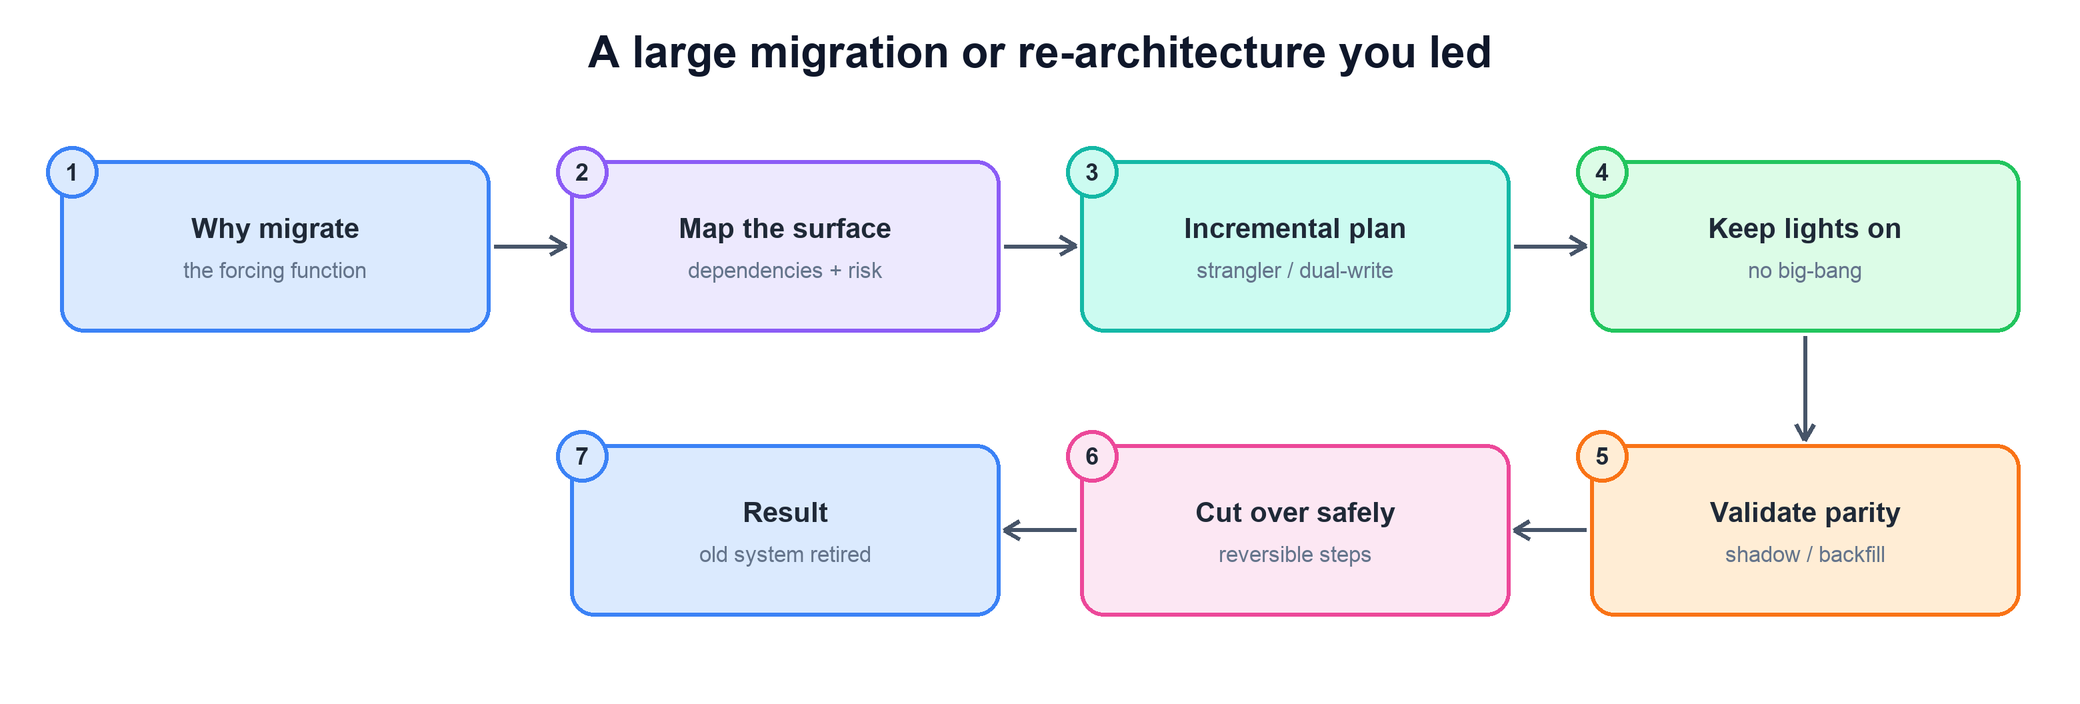
Tell me about a large migration or re-architecture you led.
A perseverance-and-design question. They want a high-risk change driven incrementally, with the lights kept on and a safe path back at every step.
Name the forcing function, map the surface and risk, plan it incrementally (strangler / dual-write), keep the lights on, validate parity, cut over reversibly, and retire the old system.How to answer
Open with the forcing function — why migrate at all, and why now — so the risk is justified.
Map the surface: the dependencies, the callers, and the highest-risk parts you had to handle first.
Lay out the incremental plan — strangler pattern, dual-write, or phased cutover — never a big-bang switch.
Show how you kept the lights on and validated parity with shadow traffic or a backfill before trusting the new path.
Describe the reversible cut-over and close with the old system retired and the reliability or cost outcome.
What the interviewer is looking for
A clear forcing function — migration as a means, not an end.
Incremental, reversible execution instead of a risky big-bang.
Parity validation before cut-over — shadow, backfill, or dual-write.
The old system actually decommissioned, with a measured result.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
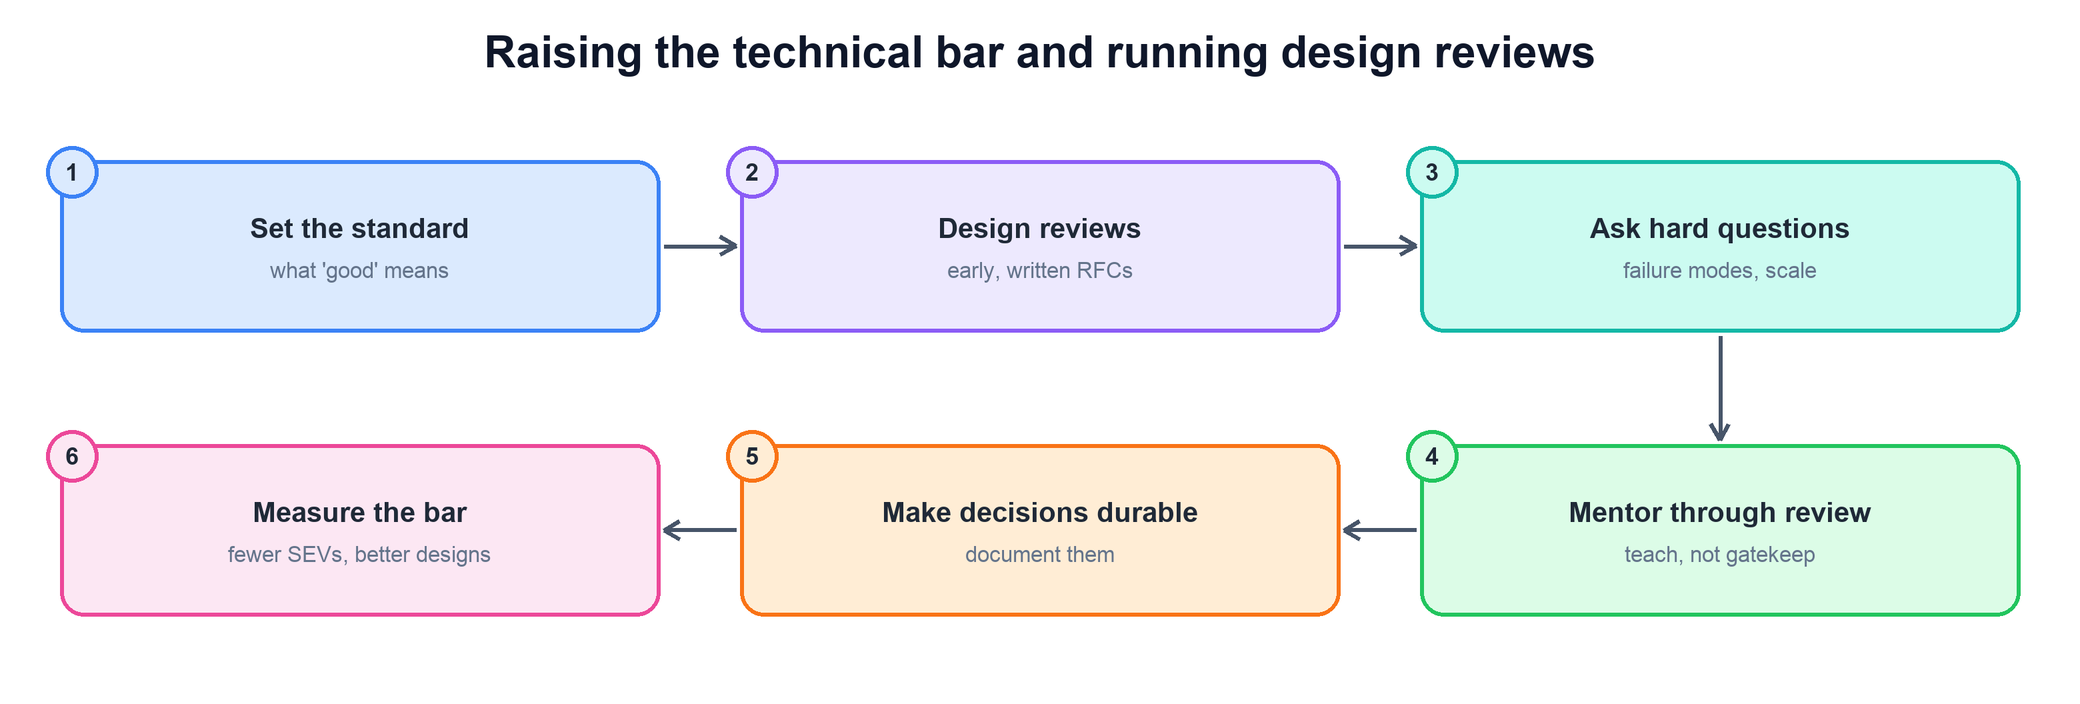
How do you raise the technical bar and run design reviews?
This question tests whether you can scale your own judgment across a team — setting a standard, teaching through review, and making the result show up in fewer incidents.
Set the standard for "good," run reviews early on written RFCs, ask the hard questions, mentor through the review rather than gatekeep, document decisions durably, and measure the bar over time.How to answer
Set the standard: make explicit what "good" looks like — clear requirements, considered alternatives, and a failure plan.
Run design reviews early, on written RFCs, before the code is written and the decision is expensive to change.
Ask the hard questions — failure modes, scale at 10x, the blast radius — consistently, so people start asking them of themselves.
Mentor through the review: teach the reasoning rather than gatekeep, so the bar rises by raising people, not by blocking them.
Make decisions durable by writing them down, and measure the bar over time — fewer SEVs, fewer reworks, better designs landing.
What the interviewer is looking for
An explicit, communicated standard — not "I just know good design."
Reviews used to teach, not to gatekeep.
Hard questions asked early, when changes are cheap.
A measurable improvement in the bar over time.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
More questions you might get — Technical Design
All of these reduce to the same spine: start from requirements, weigh real options, decide on one explicit axis, design for scale and failure, and prove it in prod. Have a story ready for each.
How do you design a system when the requirements are still ambiguous or changing?
How to answer
Pin the invariants. Find the few constraints that won't change — the data model, the SLOs — and design those first.
Defer the reversible. Keep the volatile decisions behind interfaces so a requirement change is a swap, not a rewrite.
Build to learn. Ship a thin slice to turn the ambiguity into data, then let real usage tighten the spec.
Name the cost of being wrong. Invest design effort where a wrong guess is expensive; stay cheap and flexible everywhere else.
Tell me about a design decision you got wrong. How did you find out, and what did you do?
How to answer
Own the call. State the decision and the assumption behind it that turned out to be false — no hedging.
Show the signal. Say how you found out: a metric, an incident, a scaling wall — and that you were watching for it.
Act, don't sunk-cost. Describe the correction and how you contained blast radius while you fixed it.
Bank the learning. Close with the rule or guardrail you adopted so this class of mistake can't recur.
How do you choose between consistency and availability for a given system?
How to answer
Start from the business cost. Decide what a stale read or a rejected write actually costs the user — that, not theory, picks the axis.
Go per-operation. Don't pick one for the whole system; money paths want consistency, feeds tolerate staleness.
Name the partition behavior. Say explicitly what the system does when the network splits — reject, or serve stale and reconcile.
Make the weaker side safe. Bound staleness or add idempotency and reconciliation so the relaxed guarantee stays correct enough.
Walk me through how you'd design for 10x the current scale.
How to answer
Find the first bottleneck. Name the component that breaks first at 10x — usually a hot shard, a single writer, or a queue — and design from there.
Scale horizontally. Show how you partition state and remove single points so capacity grows by adding nodes, not bigger ones.
Shed load gracefully. Add caching, backpressure, and admission limits so the system degrades instead of collapsing past capacity.
Validate the model. Back the plan with a load test or a capacity model, not a hunch, and re-check at each multiple.
How do you manage and pay down technical debt without stalling delivery?
How to answer
Make it visible. Track debt explicitly and tie each item to the velocity or risk cost it imposes — not "the code is ugly."
Pay down the high-interest first. Target the debt that slows the most work or threatens reliability, not the most annoying.
Bundle with feature work. Refactor along the path of changes you're already making so cleanup ships value, not just risk.
Stop the bleeding. Set a standard that new code clears the bar, so the debt stops compounding while you pay it down.
Tell me about a time you had to simplify an over-engineered design.
How to answer
Name the over-build. Point to the speculative flexibility or premature abstraction that wasn't earning its complexity cost.
Tie complexity to pain. Connect it to a real cost — slow onboarding, more bugs, harder ops — to justify the cut.
Cut deliberately. Describe collapsing layers or removing config back to the actual requirements, with tests guarding behavior.
Show the payoff. Close with the result: less code, fewer failure modes, faster changes — and the YAGNI rule you now apply.
How do you evaluate a new technology before betting a system on it?
How to answer
Start from the requirement. Evaluate against the problem you actually have, not the technology's hype or your curiosity.
Prototype the risky part. Spike the hardest use case and the failure modes early — benchmark, don't trust the marketing.
Weigh the total cost. Score operability, maturity, community, and lock-in, not just the happy-path feature fit.
Limit the blast radius. Adopt behind an abstraction with a fallback, so a bad bet is contained and reversible.
Before the loop: pre-load one hard number per story (latency cut, throughput gained, error rate dropped, SEVs avoided). Many design answers live or die on a single metric — pull it from Scuba, ODS, or Unidash ahead of time so you are not estimating in the room.
Worked example: a design improves writes but worsens read tail
This example illustrates how to explain reasoning and evidence without overstating a result.
Sequence for this example. The table explains the evidence and decision at each step.
Step
Evidence, decision, and expected result
State requirements
Name the user workload, scale, consistency/durability, latency, cost, and your decision role.
Compare real options
Show representative workload evidence and uncertainties, not a preferred option plus strawmen.
Explain the costly tradeoff
Specify what was accepted, how failure/rollback was handled, and what would trigger reconsideration.
Report actual results
Give definitions, population, period, and observed outcome; distinguish your contribution and alternative causes.
Check your understanding: Does a successful production metric prove the architecture is universally correct?
No. It is evidence for measured conditions; invariants and fault/model assumptions still matter.
Practice with your own situation
Draft a concise real example: context, your actual role, constraints, alternatives, decisions/actions, evidence-based result with limits, and one learning. Do not invent metrics or copy someone else's claims.
Use genuine, safe-to-share evidence. Example numbers here illustrate reasoning; they are not claims about your work or a guaranteed outcome.