When a Critical Dependency or Remote Team Falls Behind
Cross-functional Collaboration — a critical component you don’t own is slipping and threatens your launch, or a remote or vendor team has fallen behind and the process and timeline need resetting; how you diagnose the real cause, manage the stakeholders, and get the project back on track.
Student edition · understand, apply, verify
Respond to a dependency delay with joint evidence, support, realistic replanning, and explicit fallback constraints.
What you should be able to do: Separate a date estimate from a commitment and verify whether degraded/fallback behavior is actually acceptable.
Context-dependent collaboration guidance. Examples/numbers are illustrative; first-person practice drafts are not verified personal history. Respect decision rights, safety/legal obligations, privacy, and the partners' actual capacity. No framework guarantees agreement or delivery.
Concepts explained in this guide
Read these definitions first, or use the linked terms as you go. The examples and limitations are local to this guide; companion pages are optional.
Stakeholders and alignment
A stakeholder is affected by or able to affect a decision. Alignment means understanding goals, constraints, tradeoffs, and the decision process; it does not require unanimous agreement.
Example. Finance values cost predictability, customers migration effort, and operations safe recovery. State these criteria before choosing.
Boundary. Consultation is not an unlimited veto. Name decision authority, required evidence, deadline, and escalation.
Ownership, accountability, and decision rights
Ownership names who drives follow-through; accountability names who answers for outcomes. Decision rights specify who chooses/approves and who is consulted.
Example. A migration has a coordinating owner, service owners, and named release authority.
Boundary. DRI/RACI/DACI are local conventions, not guarantees. Role labels do not replace authority, capacity, and follow-through.
Decision records and reversible experiments
Record the problem, options, evidence, constraints, owner, chosen tradeoff, and reconsideration trigger. A reversible test reduces uncertainty before large commitment.
Example. Try one tenant with success/abort metrics and a data-safe rollback plan.
Boundary. Timeboxing does not bypass compliance/safety. Reversible means effects and data can actually recover, not merely that a flag exists.
Opportunity cost and prioritization
Opportunity cost is benefit forgone by choosing one investment over another. Compare expected value, effort, uncertainty, constraints, and dependencies under finite capacity.
Example. A feature can delay reliability work; compare user benefit with risk reduction and explain the choice.
Boundary. ROI/RICE/weighted scoring are aids, not exact laws. Units, uncertainty, mandatory constraints, and critical paths can dominate scores.
Outputs, outcomes, and measurement
Outputs are produced things; outcomes are changes for users/business/team. Useful metrics state definition, denominator, population, period, and attribution limits.
Example. 'Shipped a tool' is output. 'Median onboarding fell ten to six days in this cohort' is an outcome with sample/context caveats.
Boundary. Before/after does not prove sole causation. Avoid gaming, selection bias, hidden costs, and unlike-team comparisons.
This question separates leaders who manage a plan from leaders who manage reality. A weak answer either escalates instantly (throwing the other team under the bus), assumes the remote or vendor team simply is not working hard enough, or absorbs the slip in silence and hopes it recovers. A strong answer shows you lead with curiosity, not blame: you get to ground truth fast, distinguish a real slip from a schedule wobble, and diagnose whether the cause is engineering, scope, priority, or a broken working relationship — unclear specs, timezone latency, missing access, or a dependency you owe them. Then you work the problem with the owning team before escalating, adapt the process and re-baseline the timeline instead of just pushing the date, protect your launch with options rather than ultimatums, and escalate cleanly and early when the data says you must — all while protecting a partnership you will need again. Answer in CARL shape — Context, Actions, Results, Learnings — and spend most of your words on the Actions.
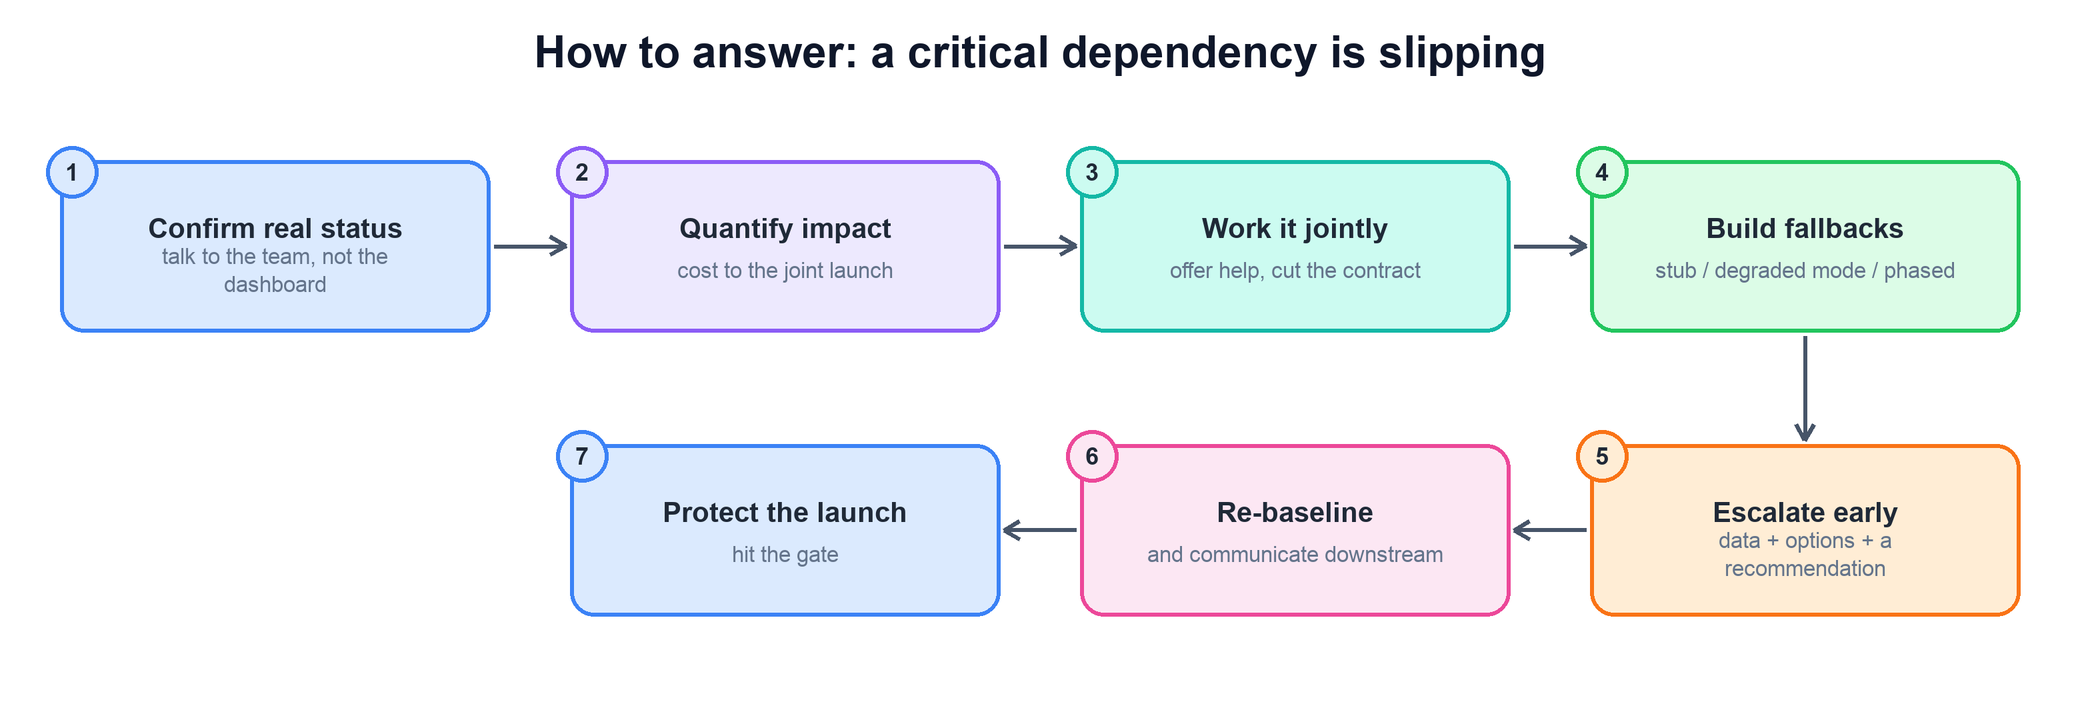
The spine: confirm the real status → quantify impact on your launch → work the problem jointly → build fallback options → escalate early with data → re-baseline and communicate → protect the launch.
What this question is really testing
Whether you can lead through influence rather than authority. The team that is slipping does not report to you, may be in another timezone, and may have its own competing priorities. The interviewer wants to see that you can build a shared picture of reality without blame, create pressure through transparency rather than politics, and make a hard call — wait, work around, cut scope, or move the date — with a clear head. It also tests whether you protect the relationship: you will need this team again, so how you handle the slip matters as much as whether you hit the date.
How to answer
Get to ground truth first, with curiosity not blame. Talk directly to the owning team’s engineers and lead, not just the status dashboard, and assume competence — distinguish a one-time slip, a systemic under-scope, a priority conflict, and process failures you may own (unclear specs, timezone latency in the feedback loop, missing access, or a dependency they are waiting on from you), because the fix differs for each.
Quantify the impact in shared terms. Translate the slip into what it costs the joint launch — the gated milestone, the downstream teams, the customer commitment — so the conversation is about the mission, not about fault.
Work the problem jointly before escalating. Offer help — lend an engineer, cut the interface to a smaller contract, unblock a dependency they have — and co-own a recovery plan with explicit checkpoints.
Reset the cadence and re-baseline the plan. Tighten the feedback loop — embed a liaison who overlaps their hours, add a short daily overlap window, and set a review SLA so a question does not cost them a full day — then turn the slip into a re-baselined milestone plan or an explicit scope decision, not a silent delay.
Build fallback options in parallel. Prepare a stub or degraded-mode path, a scope cut, or a phased launch so you are never single-threaded on someone else’s recovery.
For a vendor, use the contract as a lever, not a weapon. SLAs, the statement of work, and adding a second vendor engineer are real levers — but reach for them only after you have ruled out the environment (specs, access, and dependencies you owe them), or you will pay for pressure with a broken relationship.
Escalate early, with data and a recommendation. If the recovery plan misses a checkpoint, escalate to both managers together — not to win, but to force a priority decision — and bring options, not just a complaint.
What the interviewer is looking for
Ground truth over dashboard status — you talk to people, not tickets.
Impact framed around the shared mission, not blame.
Genuine offers of help before any escalation.
Parallel fallback options so the launch is never single-threaded.
Escalation that is early, data-backed, and carries a recommendation.
A worked example (CARL)
Practice draft: first-person narratives below are not independently verified autobiographical evidence. Use their structure, not their claimed results; replace with your genuine safe-to-share experience.
Context. On the Ads Events / AIMS storage team we were launching a new low-latency read path for an events product, and it depended on a schema-and-throughput change owned by a remote ingestion team two timezones away. Their piece was on the critical path — without it our launch gate could not pass — and about five weeks out their status quietly moved from green to yellow, then their weekly update slipped a milestone with no explanation. Two downstream teams were sequencing their own work behind our launch, so a slip on our side would cascade.
Actions. I resisted the urge to fire off an escalation email and instead set up a direct working session with their tech lead and the two engineers actually doing the work — scheduled in the overlap window of our timezones so it was a real conversation, not an async ping. What I learned changed everything: it was not a one-off slip, it was a priority conflict. Their team had been pulled onto a separate reliability effort, and our change had lost an engineer to it. So the problem was not engineering, it was prioritization, and that told me the fix had to happen at the manager level — but not yet, and not as a fight. First I made the impact undeniable and shared: I wrote a one-page brief that translated their slip into concrete downstream cost — the gated launch, the two teams queued behind us, and the customer-facing commitment — and I framed it as “our joint launch is at risk,” not “you are late.” Then I looked for ways to buy the date back on our side of the fence: I offered to lend one of my engineers who knew the ingestion schema to pair with theirs, and I proposed cutting the interface contract down to the minimum our launch actually needed, deferring the richer version to a fast-follow. In parallel — and this is the part I care most about — I built a fallback so we were never hostage to their recovery: a degraded-mode read path that used the existing ingestion format, slower but launchable, that would let us hit the gate with reduced scope if their change did not land. We co-owned a written recovery plan with two checkpoints. When the first checkpoint slipped, I escalated exactly as I had told them I would — a joint note to both managers, with the impact brief, the recovery plan, the options, and a clear recommendation to either restore the engineer for two weeks or approve our reduced-scope launch. Because I had escalated with data and options rather than blame, the conversation was about priority, not about fault, and it resolved in one meeting.
Results. The two managers restored the engineer for a focused two-week push, and with my lent engineer pairing on the schema, the reduced-contract version landed in time to pass the launch gate. We shipped roughly on the original date with slightly trimmed scope and fast-followed the richer interface a few weeks later. The downstream teams stayed on their sequence. Just as importantly, the ingestion team came out of it as a stronger partner — because I had led with help and transparency, not politics, they trusted us on the next joint project.
Learnings. Two things. First, a status dashboard tells you that something slipped; only talking to the people doing the work tells you why, and the why determines whether the fix is engineering, scope, or prioritization. Second, always build the fallback in parallel — the reason I could escalate calmly and negotiate from strength was that I was never actually dependent on a single outcome. Optionality is what turns a crisis into a decision.
Common follow-ups
When exactly do you escalate versus keep working it yourself?
How to answer
Escalate on a missed checkpoint, not a feeling. Agree checkpoints up front so escalation is triggered by objective data, not frustration.
Escalate to decide, not to blame. The purpose is to force a priority call that is above both teams’ pay grade — frame it that way.
Escalate early enough that options still exist. A late escalation is just a status report on a failure; an early one preserves choices.
Bring a recommendation. Never escalate a naked problem — bring the two or three options and say which one you would pick and why.
How do you keep the relationship intact when you have to escalate over their head?
How to answer
No surprises. Tell the owning team the escalation is coming and why, before it lands — ideally co-author it so it is a joint ask for help.
Frame it as priority, not competence. Make clear the issue is contention for their time, not their engineering — that is almost always true and it protects trust.
Lead with help first. If you have already offered engineers and scope cuts, the escalation reads as “we tried everything” rather than “they failed.”
Close the loop generously. Credit the team publicly when they recover, so the lasting memory is partnership, not the escalation.
What if there is no viable fallback and their piece is truly required?
How to answer
Then the date is the variable. If scope cannot flex and there is no workaround, be honest early that the date must move — hiding it only compounds the cost.
Re-baseline with the downstream teams. Give the teams queued behind you the new reality immediately so they can re-plan — the cascade is worse than the slip.
Invest to remove the single point of failure. Treat the hard dependency as a risk to fix — fund a second path or shared ownership so you are not this exposed next time.
Make the priority tradeoff explicit to leadership. If their team genuinely cannot deliver, that is a resourcing decision for leadership, framed with the full downstream cost.
How do you spot a slip early instead of at the last checkpoint?
How to answer
Track leading indicators, not just the final date. Watch diff velocity, design-doc sign-off, and the color trend of weekly updates — yellow that persists is a red in disguise.
Build a lightweight joint cadence. A short weekly cross-team sync on the shared critical path surfaces trouble before it hits a milestone.
Instrument the interface. Agree on a concrete integration checkpoint (a working stub, a contract test) well before the final date so drift is visible.
Build the personal channel. A direct relationship with their lead means you hear “we’re worried” informally, long before it shows up in a status.
What changes when it’s an external vendor vs. an internal partner team?
How to answer
The diagnosis is the same. Specs, access, feedback-loop latency, and dependencies you owe cause the slip in both cases — audit your own half first either way.
The levers differ. Internally you use shared goals and escalation to a common manager; with a vendor you have a statement of work, an SLA, and the option to add contracted capacity.
The context gap is wider with a vendor. They lack your tribal knowledge, so example-driven specs and a liaison in their hours matter even more.
Protect the relationship in both. An internal partner you will work with for years; a good vendor is worth keeping too — blame burns both.
How do you re-baseline a timeline without losing trust?
How to answer
Re-baseline once, on data. A single, evidence-backed reset preserves credibility; serial slips of a week at a time destroy it.
Turn it into a scope decision. “Ship the critical subset on the original date, fast-follow the rest” is a decision leadership can make, not just a delay to absorb.
Communicate up early with options. Surface the reset as soon as the trend is clear, with a recommendation attached — hiding it removes every good option.
Give downstream teams the new reality immediately. The teams sequencing behind you need the re-baselined dates at once so they can re-plan — the cascade is worse than the slip.
Evidence to collect with your approved tools
A decision/review record with the problem, constraints, options, and your contribution.
Relevant tests, dashboards, or measurements with definitions, denominators, dates, and uncertainty.
Incident or delivery records showing actual outcomes and unresolved limitations.
Stakeholder agreements and follow-up actions with owners and review dates.
Only authorized, minimized, safe-to-share evidence. Do not copy confidential personnel notes into a public story.
Worked example: a dependency slips by three weeks
Use the following scenario to practice making goals, uncertainty, responsibility, and evidence explicit.
Sequence for this example. The table explains the evidence and decision at each step.
Step
Evidence, decision, and expected result
Establish current evidence
Ask the owners what remains, what assumptions changed, and whether your team owes access/specification/other inputs.
Compute downstream effects
Map critical-path milestones and capacity, not just an overall red status.
Compare supported options
Offer help, reduced scope, a safe adapter/fallback, or a changed launch date; a stub cannot fake a required correctness/security function.
Rebaseline and review
Name decision authority, owners, explicit checkpoint evidence, and early escalation triggers. Avoid forcing unsustainable timezone availability.
Check your understanding: Should a fallback always be built to preserve the date?
Only if it satisfies permitted user, safety, security, and data semantics at acceptable cost. Otherwise replan or move the date.
Practice with your own situation
Choose a real cross-team decision. Record the shared problem, each party's constraints, options, assumptions, authority, agreed actions, owner/date, observed outcome, and reconsideration trigger. Use authorized evidence and distinguish contribution from attribution.
Use genuine, safe-to-share evidence. Example numbers here illustrate reasoning; they are not claims about your work or a guaranteed outcome.